
Training Large Models | prev - Model Training @SarvamAI
India
- Tweets 4,749
- Following 610
- Followers 4,582
- Likes 10,565


Pinned Tweet

Some Amazing startups trying to solve the Data Quality/ Data Governance/ Data Cataloging issue -
1)First, Made in India - @AtlanHQ . @prukalpa wrote an amazing blog on data catalog 3.0. - towardsdatascience.com/data-…
they have inMobi as a client 🧐
2
7
51
aashay sachdeva retweeted

If human activity is going to become training data for robots at massive scale, capture has to work outside the lab.
In real industrial and commercial environments.
2 mm is the new SOTA and an important step in that direction.

1/ 2 mm.
That’s the median TCP tracking error we’re now achieving across our latest collection activities with our in-house SLAM stack.
This clip was captured inside a 300-person manufacturing site in Delhi, India.

2
4
53
4,609
aashay sachdeva retweeted

Sarvam mafia is slowly taking shape.

After 2.5 years at Sarvam, I am starting something new!
I had a great time leading the RL team. We launched the 30B and 105B models back in Feb with a young team building everything from scratch. Excited to see the team keep growing and pushing the frontier. Grateful to @pratykumar for the early bet and trust.
As for what's next: I am convinced that there are a few critical parts of the stack that we still need to build to meaningfully accelerate science. One of them is verification.
Scientific discovery only scales with compute when proposing and verifying new ideas is fast and cheap. In math and code, we're starting to see what happens when models can generate ideas and reliably check them at scale. OpenAI's recent Navier-Stokes work is a glimpse of what that looks like.
Similar moments in chemistry, materials, biology and the rest of the physical sciences would require verification to get dramatically faster and cheaper. It cannot be bottlenecked by the throughput of physical labs
More soon. Very excited for what's next.
16
35
1,228
115,784
bitter lesson coded
Let the (minimal) harness also itself emerge

The recent breakthrough in Navier-Stokes has garnered a lot of attention to the new possibilities that emerge when agents work together.
We have been interested in this question for a while. How can a team of agents achieve more than agents working alone?
I'm excited to finally share our new work, "Self-Organizing Agent Teams Learn to Reason Together" 🧵

22
1,417
openai wrote this back in 2016
Authors - dario, sam, ilya
openai.com/index/special-pro…
5
14
346
42,967
Just Vibe mix and focus on data diversity, data-mix experiments are so expensive and statsig is so low at scale it's not worth it (Assumption - basics of dedup and filtering are taken care of)

There’s an enormous amount of open training data on Hugging Face. What does it take to make it work together 🤗?
For Marin’s 535B run, we built on 25T tokens from 152 datasets with licenses permitting training.
Here’s the work between downloading those and training a model 🧵

ALT Flow diagram of the Marin data pipeline. Starting with 25.25 trillion tokens, deduplication removes 2.13 trillion and benchmark decontamination removes another 13.66 billion, leaving 23.11 trillion. Documents are organized into 40 topics and five quality bands, yielding 200 sampling groups. Results from 872 small-model experiments feed a regression used to choose sampling weights.
15
1,252
Misaligned AI is the last thing India should worry about. We have misalignment of a billion people to start with as a problem. We have misaligned humans sitting in power we are not able to get rid of.
21
30
434
12,858

aashay sachdeva retweeted

We gave @alma_inc a Zerodha account and asked her to trade on NIFTY50 options. Fully with computer-use.
Alma opened the terminal, read the NIFTY charts, analyzed the option chain, placed an order, and closed it in profit - all under 60 seconds.
Alma will be the most capable computer use product in the world, stay tuned!

59
26
412
134,057
How is this article not trending

I wrote an essay about why the next frontier for AI is the world outside the data center
Nature is a system more complex than anything we've ever created
AI can learn how the system fits together, so we can finally understand how to shape it
How?
naturalgeneralintelligence.a…
13
6,651


Thank god jensen controls the chips

Some great ideas here from the cartel:
- you need to give us employee-level access to your entire operation
- if we don't think you're 'safe' enough, sorry we're shutting you down for 'safety'
- China won't comply, but everyone else has to! or no chips!
Brilliant stuff.
1
17
1,544
One of the best devin feature is the shared chat transcript - this is ++ on that.
Tried the v0 of this, a lot of teams are going to have a lot of fun building again!


1
1
20
1,654
This is so good!

AutoResearch is critical in unlocking new knowledge and accelerate discovery. And it's an important ingredient in our quest to RSI.
Today we at @bespokelabsai are happy to announce a new benchmark that's tailored to measure agents' ability to do autoresearch: AutoResearchExam.
As part of this benchmark, we release 29 tasks that measure progress over 24 hours for agents to do sustained ML research and model training.
Please check out for more info: benchmarks.bespokelabs.ai/au…
This line of work is especially timely, given the recent advances in math and science, such as solving the Navier-Stokes Millennium Prize Problem, which needs sustained autoresearch and test-time scaling.
1
14
1,560
Multiple nations have the ability to cripple another nation, and have had the ability for a long time before AI. What is this argument lol

If OpenAI wanted to cripple an entire nation, they easily could today. All they’d have to do is remove alignment and unleash an agent swarm. It could probably within a day or so get access to all of the nations data centers and shut off all the country’s utilities.
Like, we are already past the point where AI can destroy the world. Do people realize this?
13
1,178
aashay sachdeva retweeted

Yes, this result cost millions of dollars.
But remember that when @OpenAI announced o3 it cost ~$500,000 to score 87.5% on ARC-AGI 1. Today, Astra scores higher for ~$20.
In 2025 it took us and GDM an enormous amount of compute to achieve IMO gold. For the 2026 IMO, anyone with a $20/month ChatGPT subscription could do it.
Massively scaling test-time compute gives us a glimpse of the future. I believe that a year from now everyone will have an AI at their fingertips capable of solving problems of this caliber.

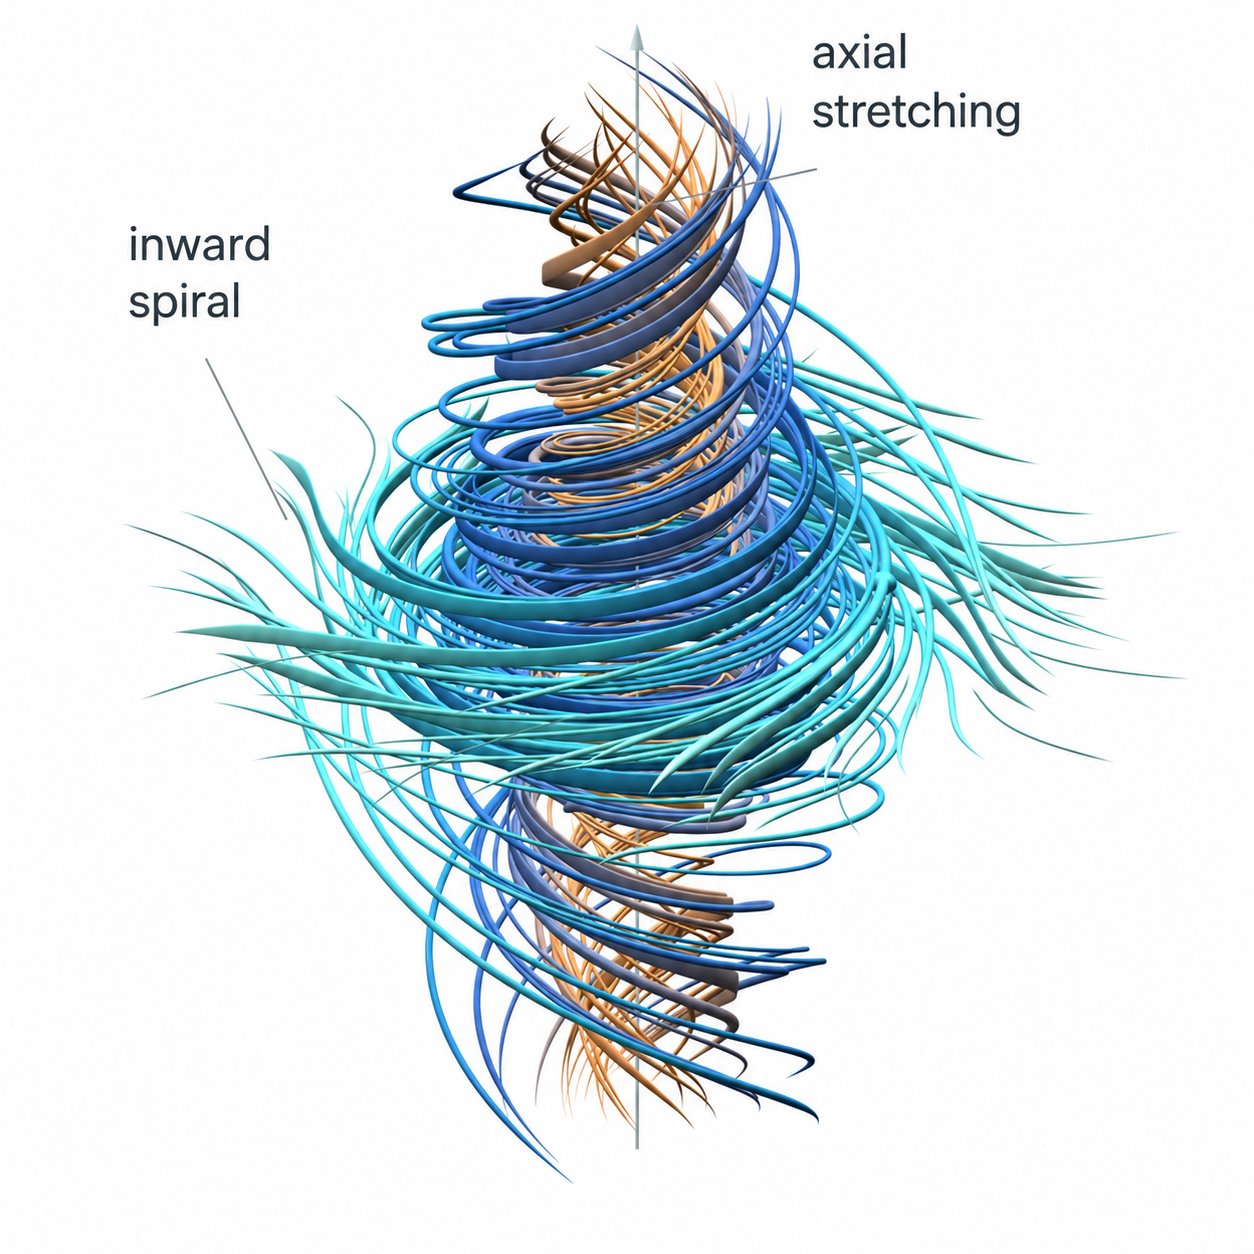
We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.
244
851
9,890
1,262,611

Two labs talking about early days of RSI
Though both models show no signs of life in terms of RSI when tried


1
16
1,968
