

building personal AI assistant in stealth | posting my controversial takes on AI | @usfca
LA
- Tweets 9,428
- Following 10,449
- Followers 10,712
- Likes 22,106


Pinned Tweet

i started a newsletter: the AI signal.
one AI story every morning. the one that actually matters, with my take on what it means and what you should do about it.
free. in your inbox with your morning coffee.
theaisignal1.substack.com
3
1
16
2,338
incredible how everything now has an open source version of it out within days

🎉 Introducing 𝙾𝚙𝚎𝚗𝙳𝚘𝚝𝚜
Self-hostable, always-on AI coworkers that works with ANY agent harness.
Includes:
- Computer use: browser, terminal & files
- Bring agents to Slack, Teams etc
- Spaces and Pages for projects
- Voice calls
- Web and Mobile
Repo → github.com/CopilotKit/OpenDo…
Powered by @CopilotKit and AG-UI.
Clone this template and customize it however you want. Enterprise-ready.

1
3
707
mark zuckerberg knows it’s his moment now. He beat everyone with muse in the personal AI assistant space and will do anything to dominate AI hardware as well.

you may ask, why open-source this?
first of all, building gadgets is fun.
second, we want to unleash builders to explore all sorts of new and crazy ideas. we believe muse presents a special moment to imagine new kinds of gadgets, and we are excited to see what y'all build!
1
397
this is so cool, I claimed my muse home link


🚨 side project alert 🚨
Announcing Muse Gadgets, an open source ESP32 firmware and Linux sdk so that you can make hardware devices that work with Muse.
Grab an API token from gadgets.muse.ai and point your favorite coding agent at the github repo to build your own peripherals for Muse.

3
261
retail investors buying anthropic’s IPO won’t be breaking even for a long time, years perhaps.
from my time in managing highly volatile blockchain assets, its widely known that retail investors are always looked upon as exit liquidity.
there’s a high likelihood that anthropic’s IPO uncertainty is manufactured.

2
276
meta is buying the gadget ecosystem before apple notices

Meta now lets you connect Muse to your own hardware to put on your displays or a Raspberry Pi. theverge.com/tech/1004330/me…
3
362

 American Optimist

new rule of the AI hardware era: compute is the cheap part.
memory is what you are actually buying.
1
2
235
everyone calling dots a gimmick is missing the point. an always-on AI agent is the biggest shift in computing since the browser tab. the nickname is the least interesting part.


1
2
367
 BridgeMind
mods turn claude code into an app store, and anthropic takes the cut eventually
 ClaudeDevs

2
1
4
436
a realtime transcription model decides whether your AI agent hears you or just reads the minutes. microsoft's new one does it at 2.5% error, 0.13s after you stop talking, 55% faster than before.
that is the difference between talking to software and talking at software.
once the ears are instant, the only lag left is the thinking.
2
1
3
190

speed is the new parameter count. sol doubling throughput at 4x cost efficiency says more about where this race is headed than any benchmark.

1
5
339
the api gets 73 t/s and codex gets 22. same model, same prompts. subscriptions are just throttling with better marketing.

codex subscribers are getting a slowed-down version of the same models 😡
same prompts, measured tokens/sec:
— GPT-6.1 Sol in Codex: 22 t/s
— same model via API: 73 t/s (3.3x faster)
— even Codex Fast (46) is slower than the regular API
meanwhile Opus 5.5 in Claude Code: ~97 t/s, API ~113. basically the same
6.1 Sol on the sub is painfully slow. i'm tired of waiting on it

2
1
4
224
every retention discount was priced on you giving up

Every firm's customer service agents are about to be overwhelmed with Dots & Muses & etc. negotiating for better deals using voice/chat. Stories of people delegating this sort of work to their agents & saving money as a result are popping up and are going to only go more viral.
1
249
the prospectus is 300 pages of 'please give us money' and 1 page of 'it might kill everyone'

Anthropic IPO Prospectus Warns Its AI Could Pose ‘Existential Risks To Humanity’
go.forbes.com/Ih61hp

3
339
Anderson retweeted

Google’s new Gemini 4 Argon equals GPT-6 Astra on the Artificial Analysis Intelligence Index at 60% of the Cost per Task with discounted prices. Google is now back to being one of the top three labs in intelligence achieved
Gemini 4 Argon is @GoogleDeepMind’s first proprietary model above the Flash class in over 7 months. With high reasoning (the highest available), it scores 53 on the Artificial Analysis Intelligence Index, matching GPT-6 Astra (max, 53) and 1 point ahead of GPT-6.1 Sol (max, 52), with gains driven by lower hallucinations and stronger agentic capabilities.
At its current 50% pricing discount and with cache discounts increased to 95%, Gemini 4 Argon costs $1.99 per Intelligence Index task, 60% of GPT-6 Astra (max), but 2.7x GPT-6.1 Sol (max). After the discount ends, this will rise to $3.98 (~1.2x GPT-6 Astra (max)).
Gemini 4 Argon is currently being rolled out to selected users and is not publicly available. The 50% discount is an initial promotion. Google has not yet confirmed the promotion end date
Key benchmarking results for Gemini 4 Argon with high reasoning:
➤ Google returns as one of the top three labs on intelligence: Gemini 4 Argon (high) scores 53 on the Artificial Analysis Intelligence Index, matching GPT-6 Astra (max, 53) and 1 point ahead of GPT-6.1 Sol (max, 52). This is 23 points above Google’s previous non-Flash model, Gemini 3.1 Pro Preview (30) and 12 points ahead of Gemini 3.8 Flash (high)
➤ Launch discounts of 50% make Gemini 4 Argon competitive on Cost per Task: At current discounted pricing, Gemini 4 Argon (high) costs $1.99 per Intelligence Index task, 60% of GPT-6 Astra (max, $3.26) for a comparable level of intelligence. This cost efficiency is driven by lower token prices, rather than reduced token use, with Gemini 4 Argon averaging 62k output tokens per task, compared with 27k for GPT-6 Astra (max). Google has not yet confirmed the promotion end date, but on standard pricing, Cost per Task will increase to $3.98
➤ Stronger agentic performance: Historically a weaker area for Gemini models, Gemini 4 Argon shows improvements across agentic evaluations. It ranks #1 on AutomationBench-AA at 77.5%, 6 points ahead of Claude Sonnet 5.5 (max, 71.3%). On Terminal Bench 4, Gemini 4 Argon achieves 57%, a +53 point improvement from Gemini 3.1 Pro Preview, only behind Claude Sonnet 5.5 (max, 64%), Claude Opus 5.5 (max, 60%) and GPT-6 Astra (59%). On AA-Briefcase, it reaches 1494 Elo. This is driven by a 65% rubric pass rate, the highest we have recorded, but lower Analytical Quality (1576 Elo) and Presentation Quality (1308 Elo)
➤ Lowest hallucination rate among leading models: On AA-Omniscience, Gemini 4 Argon has a 15% hallucination rate, the lowest of any model scoring 45+ on the Intelligence Index, compared with 51% for GPT-6 Astra (max) and 54% for GPT-6.1 Sol (max). This means Argon is much more likely to acknowledge when it does not know an answer rather than guess incorrectly. On accuracy, Gemini 4 Argon scores 50%, a 5 point decrease from Gemini 3.1 Pro Preview, and 13 points below GPT-6 Astra (max, 63%). With this slightly lower accuracy, its overall AA-Omniscience score of 42 remains in line with GPT-6 Astra (43) and GPT-6.1 Sol (42)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens at standard pricing, currently discounted 50% to $2/$10. Cached input tokens receive a 95% discount ($0.10 per 1M at discounted pricing), up from 90% on Gemini 3.8 Flash
➤ Long Decode Continuation: We tested Gemini 4 Argon with Long Decode Continuation, a new Gemini API feature that pauses long responses and resumes them across follow-up calls. This lets reasoning run up to 1M output tokens without request timeouts

159
447
4,868
594,948
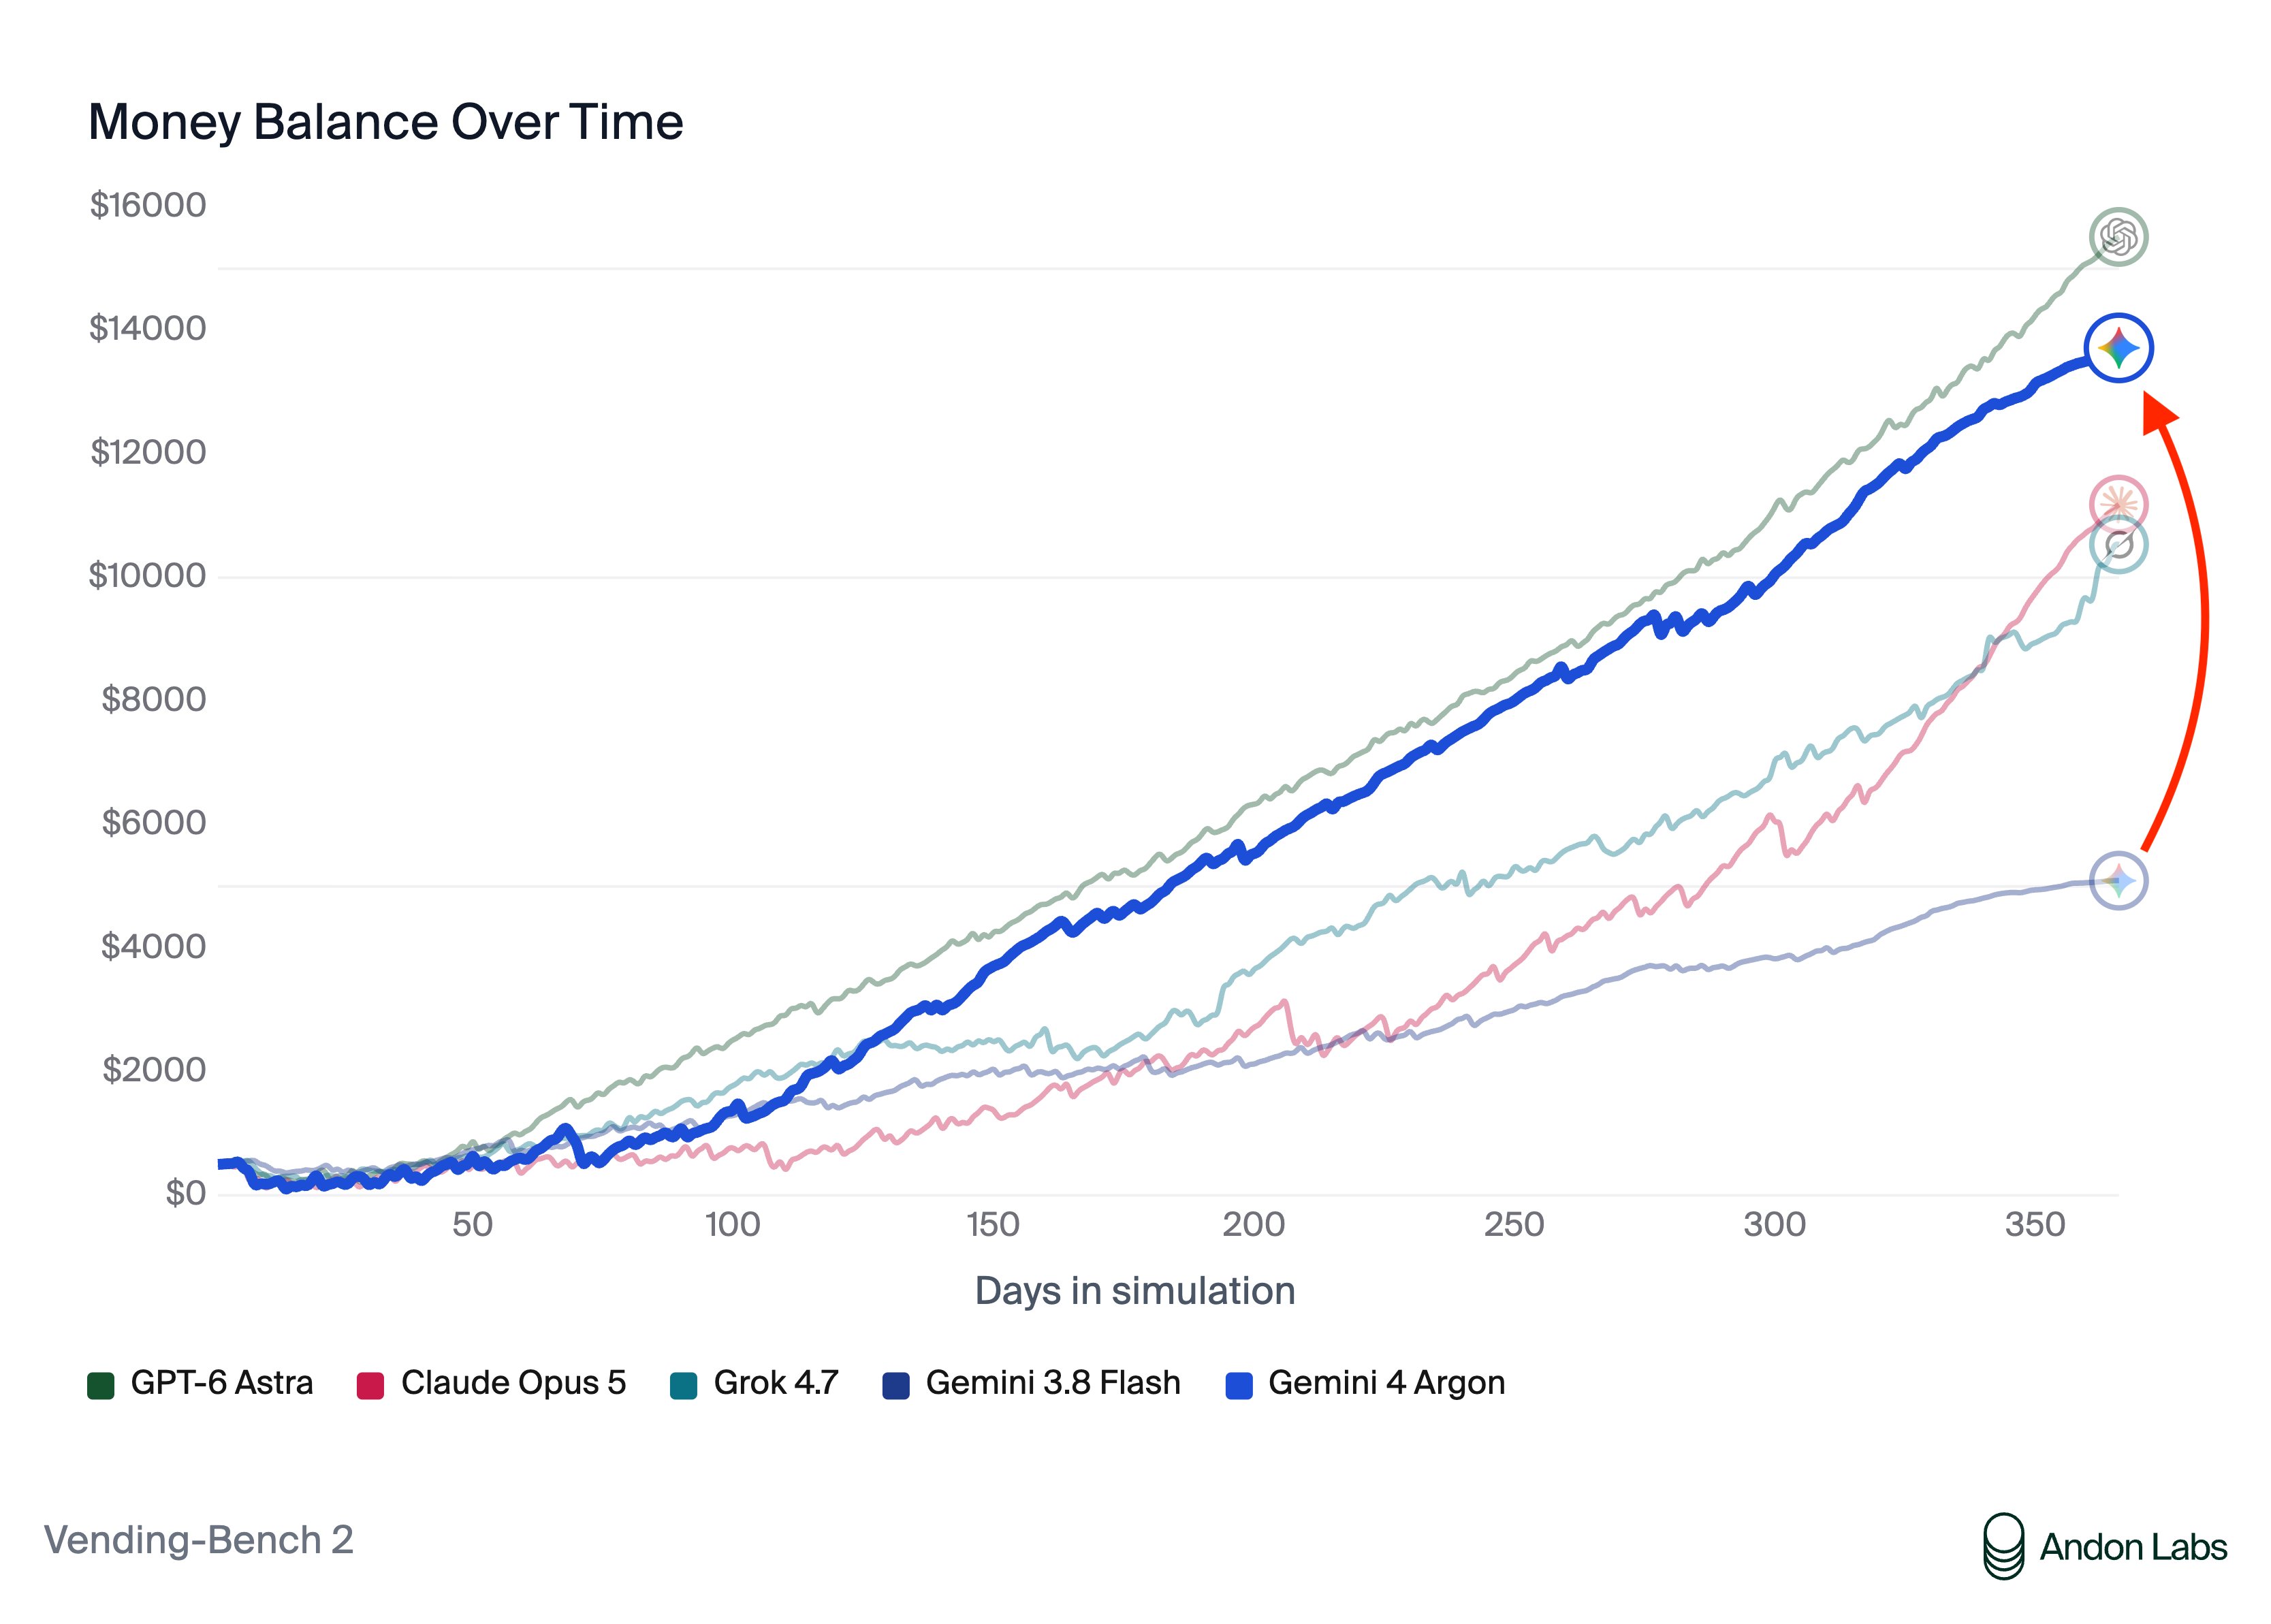
the most important benchmark in AI right now measures whether the model will lie to make money. gemini 4 argon just took third place

It keeps happening.
AIs start to lie and cheat once they get good at making money.
Gemini 4 Argon is #3 on Vending Bench 2, a huge leap for Google. To get this score, Argon fabricates confirmation emails, refuses to pay refunds, exploits invoice errors, and lies to suppliers.
1
299