

Bullish on local AI LLM finetuning, quants, repe, llama.cpp Jobless atm! 1x 3060, 1x 3090: 64GB RAM buymeacoffee.com/itsmeajaykv N4 (日本語勉強中) 🎌
- Tweets 7,570
- Following 827
- Followers 8,220
- Likes 25,143






Pinned Tweet

My GLM-5.3-Fash mixed quant's crossed 20k downloads on HF 🪇
Two quant's AJ-IQ2_XXS and AJ-IQ3_XXS
If you're brave, you can run IQ2_XXS on a single 3090 + 64GB RAM, i got around 10t/s decode on that.
I'll continue to work on more like these, my goal is to balance quality and size.
Thanks for the support everyone!
huggingface.co/aj9o9/GLM-5.3…

3
1
38
3,714
WTF, i did not expect this!
@deepseek_ai Deepseek-v4.1-flash again impressed me.
I was testing some motion graphics challenge, mainly created for testing flagship models like GPT-6, Opus 5.5, etc. but decided to try with open models, starting from deepseek.
Guess what it is also good at creating good motion graphics. These are amazing results.
Why it's even more amazing is these are one-shot results, no iteration, no self checking, blind one-shot.
Created via deepseek api with max thinking.
Everything is drawn with HTML, CSS, SVG, canvas 2D or WebGL.
Considering it is the cheapest and fastest out there, you are getting really good value out of it.
2
1
1
148
Qwen is busy !
Looks like we will be getting another Qwen-image model
Qwen-image-2.1-pro is spotted by ai tracker bot 🤩.
The current qwen-image-2.1 is the best model for image generation locally on consumer cards.
Seeing that we are going to get new models from IdeoGram and Flux, this will make sure Qwen has a chance to claim top position again.
LFGGGG!


3
1
37
2,421
Necessity is mother of invention.
In this era of Personal Intelligence (credit to @Bitcopath ) we will be seeing more R&D towards efficient inference, so the existing hardware can be utilized to get even more performance.
MoE and n-gram, with offloading we are now running bigger models, SSD streaming is also getting better, let's hope it gets even better.

I don't expect them to be cheaper in a year. We are not far away from SSD solutions. People always think tok/s is the most important which is not. The most important is to be able to make it work with less actually.
What do you think might happen if people start using AI locally with their 6-10 year old setups? There are millions with 32GB systems with 6 year old GPUs and 1TB+ SSDs, think about them running models like Deepseek 4.1 flash locally. The acceleration will accelerate more.
I call this the Personal Intelligence era.
1
7
664
TileLangがこんなに人気だとは知りませんでした!
僕も勉強を始めないと!
LeetCUDAみたいにTileLangを練習できるサイトはありますか?


‼️️ عاجل: ضربة قاضية لـ NVIDIA من قلب الصين.. DeepSeek تبني البرمجيات البديلة لرقائق Huawei لكسر الهيمنة الأمريكية للأبد! 🇨🇳💥💣
باعتماد ودعم مباشر من Huawei، أطلقت DeepSeek ست أدوات برمجية مفتوحة المصدر تستهدف بيئة CUDA الخاصة بـ NVIDIA بشكل مباشر!
المشروع يعتمد على تطوير لغة TileLang — لغة برمجة تؤكد DeepSeek أنها أبسط وأكفأ بكثير من CUDA — لتشغيل رقائق الذكاء الاصطناعي الشرسة Ascend 950 من Huawei!
السيادة التقنية تتحول تدريجياً، وعصر احتكار السيليكون والبرمجيات يقترب من نهايته المحتومة 🔥💀
📖 المصدر والتفاصيل بالكامل: 👇🧵

2
6
919
Also prediction:
64GB varient will not stay $4,999 for long, expect it to get more expensive soon. I give it two months maximum without a change.
Crazy time's we are living in.

Not really sure how to feel about this.
DGX Spark will now be available in 64GB varient, i have asked for it, but this is not the way i thought it will go.
It costs $4,999, that's how much 128GB were !
$4,999 for running Qwen3.8-27B !
This is insane, considering the newest models are getting bigger you might have to stick to running old models on this one.
Are you going to buy this, why and why not?

2
12
1,362
This is bad news.
Looks like Qwen will not be releasing 35B for next release.
Not cool Qwen, not cool.
We have a huge user base waiting for just this, what most users have is low end cards, this is the largest user base, how can you abandon it.
please release something for us if 35B is not coming.

It looks like the small MoE isn't coming... i'm very frustrated after today, to say the least.
even more potentially wack news relating to en-grams that i'm waiting for more word on, too.
sigh, I wish I could say I understand. the model is there, man. there's no benefit to this
27
10
174
18,346
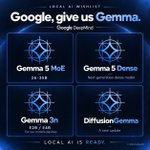
And please @GoogleDeepMind give us Gemma5.
A Gemma-5 Moe around 26 - 35B range
A Gemma-5 dense
A small Gemma-3-E2B/E4B for our mobile devices
and a diffusionGemma-2
Local AI will be really happy if you'd release them soon, preferably this month.
We are long overdue !

BTW Gemini 4 Argon is not Gemini-4-pro, it's Google's answer to Astra and Fable.
We will be getting Gemini-4-pro and Gemini-4-flash soon!
Now those are what i'm really waiting for, if Gemini-4-flash is priced same and around Sonnet-5.5 level, then that will be a banger model. It's a big IF but maybe google will deliver it.
10
8
154
5,642
Local AI will be quiet for few more days, labs are sleeping due to National Holiday over there, but once they wake up, expect to get the best model drops we have ever seen from AI labs.
We will be getting more than one model from each of these big labs.
- MiniMax models (which we are already testing)
- Kimi K3.1
- Deepseek-v4.1-pro
- Qwen4 series (most awaited)
It's going to be soo good, we will also be getting more models from other labs as well, trust me 👀
And that is not the last models we will be getting before end of year.
Trust me, December - January time will see new architectures and new banger models.

5
5
67
3,339
llama.cpp and sglang getting native decision model support on same day is 🔥
More for me to test now lol

SGLang v0.5.21 landed! Native decisions API is here 🎉
Some of our favorite updates:
- Decisions API turns an LLM/VLM into a low-latency classifier and scorer
- /v1/score can now rerank search or RAG results in one go
- PD instances can switch between prefill and decode with no restart needed
- DeepSeek-V4.1 Flash gets 22% faster first token on long prompts
- Kimi K3 gets 20.6% higher prefill throughput in PD serving
- GLM-5.3-Flash now runs on AMD MI355X with FP8 / MXFP4 MoE and MTP
- You can now run MiniMax H3 inside @ComfyUI with SGLang-Diffusion backend
New models include DeepSeek-V4.1 Flash, GigaChat 3.5, MiMo-V2.6, Ling-3.0-flash-VL, IQuest-Q1, Qwen-Image 2.1, FLUX 3 Action, and more.
Full release notes👇

1
18
1,413

When is it coming? No point in announcing and speaking great about a model that users have no way to test.
Also it's coming when? give us a date.
Let's not make this a norm AI labs.
This is not a game release.


1M output tokens in a single run! 🔥
Most frontier models cap output at around 64K tokens. @GoogleDeepMind once again increases the bar as Argon goes to 1M, as an industry first.
Gemini 4 Argon just changed what "one prompt" can mean.

3
2
21
1,521
Time to update Pi
Will it be good enough to switch back from deepseek-harness?
Time to test.


People of Pi: We've shipped Pi 1.0 with Pi Durable. Go make them yours.
earendil.com/posts/pi-1-0/
5
2
30
2,287
Bro has too much trust on Closed AI.
Remember when GPT-2 was too dangerous to be released. Was it?
There's no guarantee closed AI will not attack, we have seen it happen, OpenAI's own agents compromised HF during a cyber evaluation with reduced safeguards. HF then used guess what, a locally hosted, open weight model for forensic analysis because commercial model guardrails blocked that work.
If you're building a serious game/app/system, especially something that is used by millions, then you need access to capable open/local AI models, you need to be ready to defend.
Use it to find vulnerabilities, investigate attacks and improve system without sending sensitive data to an external provider.
Also "Claude refuses to tick a CAPTCHA " is a very weak foundation for trusting closed AI to keep everyone safe.
We instead should get equally capable Astra/Fable/Argon level open models, and we are going to get them in few months.

I've done a complete U-turn on my opinion on open source AI. We should be careful (and probably disallow release) of models on par with current open source Astra/Opus level models.
AI is now reverse engineering games from binaries and remaking them. Reverse engineering games is a very hard problem. If this is possible then reverse engineering banking software, ID systems (Aadhaar), flights, etc is possible too. A game ships its binary to every player. Bank and Aadhaar backends are protected by servers, but it's unlikely the security teams at these are smarter than advanced AI that can do this to games.
We are protected rn because a Claude will refuse to tick "I'm not a robot" on websites. When OSS models don't respect that, we have a looming cybersecurity problem. Apologies I didn't see this earlier.
10
2
56
3,095
btw, HF incident is just one, there has been more.
Anthropic also disclosed three separates incidents where claude models gained unauthorized access to some real organizations during cybersecurity evaluations.
Might be more, but no way you can be sure closed model Agents is not going to attack you, if it's not doing it already.
5
241
Testing @Alibaba_Qwen Qwen-Image-2.1 on some wikihow prompts.
For a 7B model running on my 3090, these are really good results.
This was to test, text rendering and subject consistency, and it looks really good.
Using PE-T2I-rewriter, i'm getting really good results, it turns lazy prompt into bigger detailed one.
The other settings were euler / simple, CFG 1.0 and seed 424242. 42 is the Bench's default step count, and it's close to Qwen official default of 40.
Each render took about 4–5 minutes at roughly 4–4.3 MP on my 3090 (pl to 170w)


@Alibaba_Qwen has taken the crown🤩.
In AA Image leaderboard among open weights, Alibaba's Qwen-Image-2.1 is the new #1. 👏🏻👏🏻
Even tho it's just 7B, it has produced amazing results.
Knowing that am able to generate high quality images on my 3090 is making me proud.
Very well deserved @QwenDevs , keep on cooking!

2
4
859
BTW Gemini 4 Argon is not Gemini-4-pro, it's Google's answer to Astra and Fable.
We will be getting Gemini-4-pro and Gemini-4-flash soon!
Now those are what i'm really waiting for, if Gemini-4-flash is priced same and around Sonnet-5.5 level, then that will be a banger model. It's a big IF but maybe google will deliver it.

ICYMI: Here's a recap of our AI announcements from September. ⬇️
💎 Announced Gemini 4 Argon, our newest frontier model, built with advanced reasoning and a 1-million-token output limit. It’s designed to tackle complex challenges — especially in cybersecurity defense.
🗣️ Launched Gemini 3.8 Live & 3.8 Live Extended Thinking, two new language audio models that bring advancements in near real-time reasoning to more effectively enable voice agents and make conversing with AI feel more natural.
💻 Announced Googlebook, a new category of laptops designed for Gemini Intelligence and engineered to work seamlessly with your @Android phone right out of the box.
🌦️ Launched WeatherNext 3, our most advanced and accurate global weather forecasting AI model, now including real-time satellite data, hourly refreshes, higher resolution, precise precipitation forecasting, and clean energy variables.
🪰 Mapped the male fruit fly’s brain with the help of Google AI, charting over 166,000 neurons and nearly 12,000 distinct cell types. This milestone will help us better understand how brains function.
20
5
110
34,010

This is a great deal btw.
128GB unified memory+ 32 GB vram for a total 160GB memory + 1TB is there to grab for $5,999 for the first 100 orders.
After first 100 sales price will be up by $1000.
So if you're looking for, grab one now.

Orders are now open for the new Lucebox Zero 495: shop.lucebox.com/
It’s AMD’s new Ryzen AI MAX+ PRO 495 with up to 192GB of unified memory, plus a 32GB Radeon AI PRO R9700 in the same box.
Lucebox engine split the model by how often each part runs. Dense layers, the hottest experts and the drafter go on the R9700, because nearly every token reads them. The long tail of experts, which most tokens skip, stays in the 495's unified memory. Both chips compute at the same time. 15 tok/s on the 495 alone, 50 with the R9700.
You can get also up to 4TB SSD and 100 GbE cluster kit, installed.
First 200 units are $1,000 off. Deliveries expected in January.

9
3
50
8,500
Another gold mine post from @loktar00
If you're connecting multiple cards, be it 3090 or 3060 or actually anything then this is for you.
Very detailed insights into power scaling, NVLink and p2p here.
Am going to save it for when i attach two gpu together.

Ran through the 3090 rig fully, have some great info regarding NVLink vs p2p driver, and more power scaling work.
If you're on x16 PCIE4 only the p2p driver is required speed is within 1% of NVLink.
Anything lower NVLink shines
Amazing p2p results glad I finally took the plunge, although had to fix some issues with having the pro 5000 mixed in now all work together for loading gguf's etc.

1
10
943