

ai engineer at @ibm • author of fluent react • keynote speaker • host of contejas code • angel investor • i dont speak on behalf of ibm
Berlin, Germany
- Tweets 54,258
- Following 1,214
- Followers 38,663
- Likes 36,794


Pinned Tweet

spent the weekend so far documenting my life while exploring what web-native storytelling might look like for a 33 year long story.
im kinda satisfied with it.
if you're up for some weekend reading,
tej.as/story
9
5
48
11,188
Next time someone asks what I do for fun outside of work I’m just going to send them this link
replay.pokemonshowdown.com/g…


372

full comment lnkd.in/p/dSnnTDqU
197
im still lowkey ashamed of germany because they set such a low bar for themselves: usa has amazing frontier models, as does china, but europe’s largest economy targets small open weight unambitious “frontier” models. we can do better

germany just dropped a sovereign open weight model
kolibri by @Aleph__Alpha runs 3.5b of its 78b parameters per word and its math is kinda ridiculous: 96.9% on aime beats every mixture-of-experts model they tested, even 3x bigger ones. only a dense model doing 8x the work wins
anyone can run it on their own servers, it thinks in german, and in their evals it tops every open model its size in english and german
models read text in chunks called tokens, and i ran kolibri's chunker (its tokenizer) on the german constitution: it needed 15% fewer tokens than gpt-5's for the same text. "bundesverfassungsgericht" is 6 tokens for gpt-5 and 2 for kolibri. fewer tokens means cheaper, faster german, and more of it fits in what the model can read at once
how it works, simply:
1. every layer has 384 tiny specialists, and a router sends each word to 6 of them. so it thinks like a 3.5b model, but it needs the memory of a 78b one: about 78 gb, which means 2 big nvidia gpus (h100s) or 1 h200
2. most layers only look at the last 512 tokens, and every 5th layer looks at everything. that's how it can read 1 million tokens (a few thick books) without it costing a fortune
3. it reasons in german. their team found that a little german reasoning data is worse than none: the model's german thoughts go in circles and never finish. so they made about 800k german reasoning examples and gave it a lot
4. it's trained to say "i don't know". they play a game with it where parts of the documents are hidden, sometimes to help it and sometimes to hide the evidence, and it has to tell which. when it didn't know an answer it admitted it 44% of the time. qwen3.5 did 11%
where it's weaker: answering from memory, using tools over a long back and forth, and coding agents, where qwen models are ahead. and to run it you need aleph alpha's add-on for vllm, a popular open source server for running models
if you have german documents and need to keep them on your own hardware, this is a big deal. huge congrats to everyone at aleph alpha, my good friend @MichaelLHofmann included!!
i wrote up how it works, the benchmarks, how to run it and when to use it: tej.as/blog/aleph-alpha-koli…
3
12
2,515
unusual for me to say but @cloudflare's d1 is actually very poor
i've been using it in production for 3 months: ~3% of reads take 3 to 10s while the SQL runs in 1ms on an idle db, "overloaded" errors at a few hundred queries/s, and minute-long freezes
i hope it improves
2
15
2,803

Nikola retweeted

Inspired by tej.as/status health page to revamp my own again. I had created one back in April (juri.dev/health) but then my apple watch died and didn't track since then. just got a new one, so time to update the design and get some goals on the page 💪
2
2
5
846
Nikola retweeted

Today we launched Kolibri. On German National Day.
A new LLM aleph-alpha.com/en/kolibri/ from Aleph Alpha available under Apache 2.0.
Its been an intense few months across pre and post training to make this real. Look forward to getting adoption and feedback!

67
70
968
32,030
germany just dropped a sovereign open weight model
kolibri by @Aleph__Alpha runs 3.5b of its 78b parameters per word and its math is kinda ridiculous: 96.9% on aime beats every mixture-of-experts model they tested, even 3x bigger ones. only a dense model doing 8x the work wins
anyone can run it on their own servers, it thinks in german, and in their evals it tops every open model its size in english and german
models read text in chunks called tokens, and i ran kolibri's chunker (its tokenizer) on the german constitution: it needed 15% fewer tokens than gpt-5's for the same text. "bundesverfassungsgericht" is 6 tokens for gpt-5 and 2 for kolibri. fewer tokens means cheaper, faster german, and more of it fits in what the model can read at once
how it works, simply:
1. every layer has 384 tiny specialists, and a router sends each word to 6 of them. so it thinks like a 3.5b model, but it needs the memory of a 78b one: about 78 gb, which means 2 big nvidia gpus (h100s) or 1 h200
2. most layers only look at the last 512 tokens, and every 5th layer looks at everything. that's how it can read 1 million tokens (a few thick books) without it costing a fortune
3. it reasons in german. their team found that a little german reasoning data is worse than none: the model's german thoughts go in circles and never finish. so they made about 800k german reasoning examples and gave it a lot
4. it's trained to say "i don't know". they play a game with it where parts of the documents are hidden, sometimes to help it and sometimes to hide the evidence, and it has to tell which. when it didn't know an answer it admitted it 44% of the time. qwen3.5 did 11%
where it's weaker: answering from memory, using tools over a long back and forth, and coding agents, where qwen models are ahead. and to run it you need aleph alpha's add-on for vllm, a popular open source server for running models
if you have german documents and need to keep them on your own hardware, this is a big deal. huge congrats to everyone at aleph alpha, my good friend @MichaelLHofmann included!!
i wrote up how it works, the benchmarks, how to run it and when to use it: tej.as/blog/aleph-alpha-koli…
21
40
385
22,025
v hyped to see griffin from @tavus.
it starts talking before it has finished generating what it's going to say, its first audio packet plays before the second one even exists, and the face reacts 0.43 seconds after the sound. love to see innovation like this!!
in 2023 i built a voice assistant live on stage with the browser's speech apis, and it was a relay: speech to text, text to a model, the reply back to speech. strictly i talk, you talk: when jarvis finished speaking, my code waited 1 second and started listening again. analog at best.
with griffin, its
1. a conversation model that never stops: it listens and watches the whole time, and every fraction of a second it decides whether to speak, react or wait, then sends out controls: timing, stance, expression and gesture. it takes the turn because of what you said, not because the audio stopped, so a pause to think doesn't end your turn
2. speech that doesn't wait for the sentence. a second of sound is 48,000 numbers, which is way too much to juggle, so they squish every 10 ms of it into just 40 numbers, a tiny summary called a latent. the model writes the next latent the moment it knows what to say, and the speaker turns each one back into sound and plays it right away, without peeking at what comes next. so it talks like you do: you start a sentence before you've worked out the end of it. it can also copy a voice from about 10 seconds of audio
3. a face that doesn't wait for the audio. other streaming video models hold back for a bit of future audio before they draw the next chunk. griffin-lite draws one latent at a time with no lookahead: 0.43 seconds from sound to face on h100s, half the next fastest method they measured
4. they render an entire scene, not just a fake ass face pasted on a background: every pixel comes from 1 reference image, so the chair moves and the shadows follow and it feels somehow "alive"
i think this is cool but it also kinda raises the question of humans and our roles once again. still, very cool tech!!
huge congrats to @hassaanraza, @quinnfavret and everyone at tavus who built it!!
3
5
1,183
related:
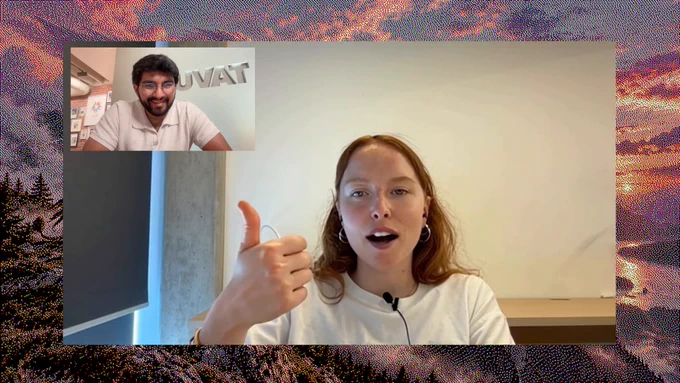
wild. i built something with @tavus' new ai zoom call thing.
this is not a real person.
tej.as/demos/tavus

232
every page on my website now gives ai agents tools through webmcp
webmcp is a new web standard (chrome has it in an origin trial) that lets a page tell any ai agent using your browser exactly what it can do there. each tool has a name, a description, the inputs it takes and a function to run, so instead of screenshotting the page and guessing where to click, the agent just calls the function
@sarah_edo nailed the before and after: the agent screenshots, scrolls, screenshots again, clicks the wrong button... vs a page that says "hi, here are the 4 things you can do here, with descriptions". my site is literally that page now
this morning i gave an agent that knew nothing about me except those 4 tools one question: where is tejas speaking this month, and what would a workshop cost? it made 2 calls and came back with all 4 of my october conferences and every workshop price, straight from my site's own data, without scraping a single page
what i learned building it:
1. write each tool's description once. the browser shows it to the agent, and my server checks every call against that exact same description of the inputs, so the two can never disagree
2. hand mistakes back as a sentence, never throw. if a tool throws, the model only gets a generic unknown error and has no clue what went wrong. a sentence like "source must be one of talks, podcast, book, blog" it can fix on its next try
3. keep it small. chrome suggests at most 500 characters to describe a tool and about 1,500 for what it sends back, so my search tool returns a short passage from each talk or post instead of all of it
4. only load it where it works. a browser without webmcp pays for one quick check and nothing else
the full write-up, with the code: tej.as/blog/what-is-webmcp
thanks to @una for telling me about it earlier this year in finland
1
1
13
2,262
wild. i built something with @tavus' new ai zoom call thing.
this is not a real person.
tej.as/demos/tavus
7
18
2,706
related

Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Community note
The 48% figure and "video Turing test" claim are from Tavus's own study of 54 one-minute calls, not independently verified or using a standard protocol. Griffin-Lite leads NVIDIA's VideoFDB benchmark on their public leaderboard.
cellcog.ai/blog/tavus-gri…
research.nvidia.com/labs/amri/proj…
tech-ish.com/2026/10/02/tav…
272
imagine this but during covid

The whole point of building Tavus has been simple: talking to a machine should feel as natural as talking to a friend or coworker.
It’s hard to describe all the tiny nuances that make a conversation feel human. The little expressions. Moving around in your chair. Knowing when to speak and when to listen. The dance of it all.
Griffin is by far the closest anyone has come to a model that can capture those nuances. The first time I saw it being used, I had no idea I was watching our model rather than just a normal video call.
I’m so incredibly proud of this team and what they’ve built.

2
7
2,212

