

Public LLM Evaluation // vals.ai @8vc @BloombergBeta @pearvc @a16z @HRTVentures @nextladder
San Francisco, CA
- Tweets 2,128
- Following 277
- Followers 23,878
- Likes 795






Vals AI retweeted

Love seeing more work on better search evals for agents. @ValsAI uses private, expert-written tasks.
With NEEDLE, we took a different approach: fresh queries every run, with the fully public benchmark.

We realized that web search wasn’t being measured correctly and we weren’t alone. Other companies have created their own benchmarks to tackle this problem, but kept running into the same issue: data contamination, realism, and answer leakage. When benchmarks measure the wrong thing, customers can't tell which search tool is best.
We believe the teams building these tools deserve to have a third-party benchmark that measures the work their users actually need done. We’re excited to share that @ExaAILabs, @KeenableAI, @p0, and @tavilyai are joining us as partners on the Vals Web Search Index: one benchmark, the same settings for everyone, run independently.
Check out our latest blog to learn more: 🧵

3
8
1,065

Rayan on MTS this morning!

Vals AI CEO @RayanKrishnan says AI safety is turning into an ideological identity in DC:
"I feel like there's a new McCarthyism emerging, where there's an ideological pushback on EAs. People trying to suss out in a quick interaction, are you a safetyist? That was actually the word being used."
"There's a fundamental disconnect in the values. Congresspeople care about their constituents that are alive in their district. And EAs care comparatively little about that populace. They care about all humans everywhere through all time."
"So there's an interesting rift happening of how do we actually figure out what we value and how does that play out into what we think about AI long term."
@ValsAI

1
10
2,334

Step 5 has a 1M-token context window and 1M max output tokens. We used StepFun’s defaults: temperature 1, top-p 0.95, and default top-k.
Congrats to @StepFun_ai!
Full results: vals.ai/models/stepfun_step-…
4
414

Vals AI CEO @RayanKrishnan argues "Claude is the salesman for Claude," because the model can eventually find the inefficient parts of your life and insert itself into them:
"I was staying with a friend's parents, and the dad is a doctor in a hospital. Every month he spends 12 hours making the schedule for the hospital. I sat down with him for an afternoon, used Claude Code and made him a little web app, and this app has saved him 12 hours every month."
"I was asking this friend of mine at Anthropic, does this mean the biggest bottleneck will actually be behavior? He said, 'No, because over time, Claude will figure out the places where you're spending time in an inefficient way and suggest how to use itself for those tasks.'"
"Claude is the salesman for Claude. It's not going to be a human bottleneck. The model is itself the solution to a lot of these problems."
@ValsAI

1
3
30
8,787
Exa, Keenable, Tavily, and Parallel have each also built their own search evals to address precisely these issues. Building on these efforts, our index complements those efforts with an independent comparison under consistent settings.
We’re excited to partner with them to help make web search evaluation more useful for real-world agent workflows.
Learn more about the Vals Web Search Index at vals.ai/blogs/web-search-ind…. .
2
8
511
The Vals Web Search Index asks a different question: can an agent equipped with a given search tool get a real professional task right?
Our approach is to hold the model and harness constant, swapping only the search tool. The tasks are expert-written questions from finance (FAB v2) and law (Legal Research Benchmark), with more domains coming. The index scores the agent’s final answer, not just a ranked list of search results.
1
4
359
To validate the importance of search in our benchmark, we also tested agents with and without search. Without search, agents score 2.9% on legal and 7.4% on finance. With search, scores reach 30–50%.
This means that to do well on these tasks, search capability (as opposed to intrinsic knowledge) is critical, and thus is what the index helps measure.
1
4
267
While existing web search benchmarks like BrowseComp have helped advance the field, their static, public questions create challenges as models learn more and answers circulate online.
A 2026 study found that a frontier model counterintuitively answered 44.5% of BrowseComp questions even without search tools. That points to a fundamental limitation in the benchmark, which is that it rewards the model’s intrinsic knowledge, rather than search capability.
1
6
503
We realized that web search wasn’t being measured correctly and we weren’t alone. Other companies have created their own benchmarks to tackle this problem, but kept running into the same issue: data contamination, realism, and answer leakage. When benchmarks measure the wrong thing, customers can't tell which search tool is best.
We believe the teams building these tools deserve to have a third-party benchmark that measures the work their users actually need done. We’re excited to share that @ExaAILabs, @KeenableAI, @p0, and @tavilyai are joining us as partners on the Vals Web Search Index: one benchmark, the same settings for everyone, run independently.
Check out our latest blog to learn more: 🧵
6
8
67
6,398
The Vals Web Search asks a different question: can an agent equipped with a given search tool get a real professional task right?
We hold the model and harness constant, swapping only the search tool.
The tasks are expert-written questions from finance (FAB v2) and law (Legal Research Benchmark). We score the agent’s final answer not just a ranked list of search results.
2
1
113
To reduce contamination risk, we report results on held-out test data. In addition, we run every evaluation under Zero Data Retention (ZDR) with model providers.
To validate the importance of search in our benchmark, we also test agents with and without search. Without search, agents score 2.9% on legal and 7.4% on finance. With search, scores reach 30–50%. On these tasks, search makes a substantial difference.
1
1
339
Exa, Keenable, Tavily, and Parallel have each built their own search evals. Our index complements those efforts with an independent comparison under consistent settings.
We’re excited to partner with them to help make web search evaluation more useful for real-world agent workflows.
Learn more about the Vals Web Search Index at
vals.ai/blogs/web-search-ind…
Want your search tool evaluated? contact@vals.ai
1
337


Watch the full episode:
X:x.lingyaoai.com/ValsAI/status/21053648…
Spotify:open.spotify.com/episode/6c3…
YouTube: piped.video/rjA8r3ygATo
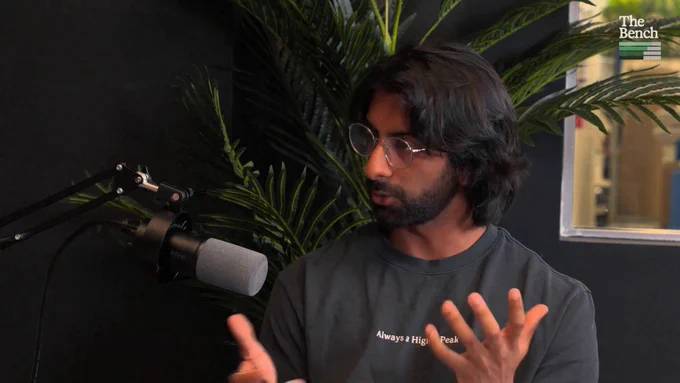
Why off-the-shelf AI models aren't enough for the enterprise. Prime Intellect's @willcb and Rayan discuss owning your intelligence, benchmark limitations, and multi-agent systems on The Bench.
Full episode out now!
03:10 Own vs. Rent Your Intelligence
05:15 Capturing Institutional Knowledge
15:45 Why Frontier Models Fail to Do Real Work
23:14 Token Spend vs. Salary Spend
24:08 OpenAI Selling Out of Compute
34:00 Is RL "Whack-a-Mole" True Generality?
36:07 Why Sandboxes Are Important
39:09 Multi-Agent Game Theory & Cooperative RL
42:05 Will's "Slop Meter" & Cringe-Worthy AI Writing
2
1,156