

"Art always wins" | "The System is the ART" Agon - agonagent.com/
Metaverse
- Tweets 17,547
- Following 1,677
- Followers 3,948
- Likes 25,458


JCode retweeted

honestly so crazy

Worked on something different last few days.
Since I saw @GrantYun2 work I always wondered if I could create illustration type of art but purely based on code and generative.
Just a first shot at it, but i think these look king of cool.

5
1
29
2,525


I am working on developing a workflow for developing engineering for energy and infrastructure projects.
Model: GLM5.3-flash
Engine: TensorFold
Harness: Hermes Agent
2D: FreeCAD
3D: Blender
The test project is NX F100, a 100kw modularised micro data center that can be deployed anywhere.
This will develop everything from the basis of design to design criterias, specs, drawings and 3D models.
Not there yet, but getting closer!

5
14
536
I deployed and tested this one.
But what I was interested in was not the speeds performance (they are very similar), but the quality of the quant.
I generated the Project Execution Plan for a real multibillion dollar project in west Africa.
This is a generated document of 120 pages (360k characters) that uses RAG and a library of project documentation as context, so the model has to go and sort out what helps and what doesnt to write this document.
Mia's new quant did produce a better document, and that is what matters to me.
They were not far (GLM5.3-flash is a very good model), but far enough to decide to keep the new quant.
Great job as always, I will keep sharing more about this quant, which has now become my daily.


GLM 5.3 Flash on TensorFold v1.4 is out 🔥
This is a MAJOR release, with a lot of changes, additions, and fixes, starting with the quant.
- NEW EXL3 quant optimized for TensorFold!
- Same size, same speed, better quality.
3x DGX Sparks support:
- New TP=3 path
- Around 6M KV cache
- 77 tok/s on prose, single stream
- 146 tok/s on prose, 4 concurrent stream
- Prefill up to 2064 tp/s
New features / fixed issues:
- Concurrency issues were completely fixed!
- Improvements and fixes in tool calling.
- Stability and diagnostics improvements.
Special thanks to @YasaarBiladama for letting me use his 2x RTX 6000 PRO server to create the my EXL3 quant!
mia-ai.net/models/GLM-5.3-Fl…
2
359
13 editions left for "clocking out"!

I want to thank @manicdistopia and @pvi11e for grabbing an edition of 'clocking out'!
Only 13 editions left now.
transient.xyz/mint/clocking-…

1
1
5
401
Thanks for the shout out Mia!
Great names here, please go give them a follow if you are interested in local AI and its applications!
A few AI accounts that deserve way more followers:
@volatilemarkts
@ashxhart
@Kurcide
@jayleaton
@jmurillocode
@hecisaza
@spark_arena
@sfxnz
@niklaslenz_ai
@cybersec
@plotarmordev
@StefanMaier
@0xWhiteMage
Who am I missing?
1
254

Been in this space long enough to know drama is part of the game, every week is a new episode and that I dont get involved with it.
However, these are my 2cents:
You yourself will end up making mistakes or making poor choices, so treat others the way you want to be treated when that happens. Not "if" but "when", that happens.
Put your head down, keep working hard, keep building. Add value to this space and your communities, not only extract from it.
Onwards and upwards always.
1
18
648


Not sure if this driven by memory shortage but what I saw around me was an ask for MORE memory, not less.
This will complicate multi-spark architectures, requiring multiple switches, etc.
I hope this is just a lower cost option ans the 128gb and 256gb are also released.

DGX Spark is getting a 64GB option.⚡
With the GB10 Grace Blackwell Superchip, DGX Spark 64GB runs capable local agents on device and works with our new NVIDIA Sync Cluster Assistant to seamlessly pair systems for larger workloads.

4
305
Shortage of the raw minerals.
Shortage of the manufacturing capacity of chips.
Export controls.
Soaring demand.
Billions of dollars at stake from VCs a d investors on AI.
--------------------------------
The recipe has a clear outcome.
Next to watch: AI subscription costs.
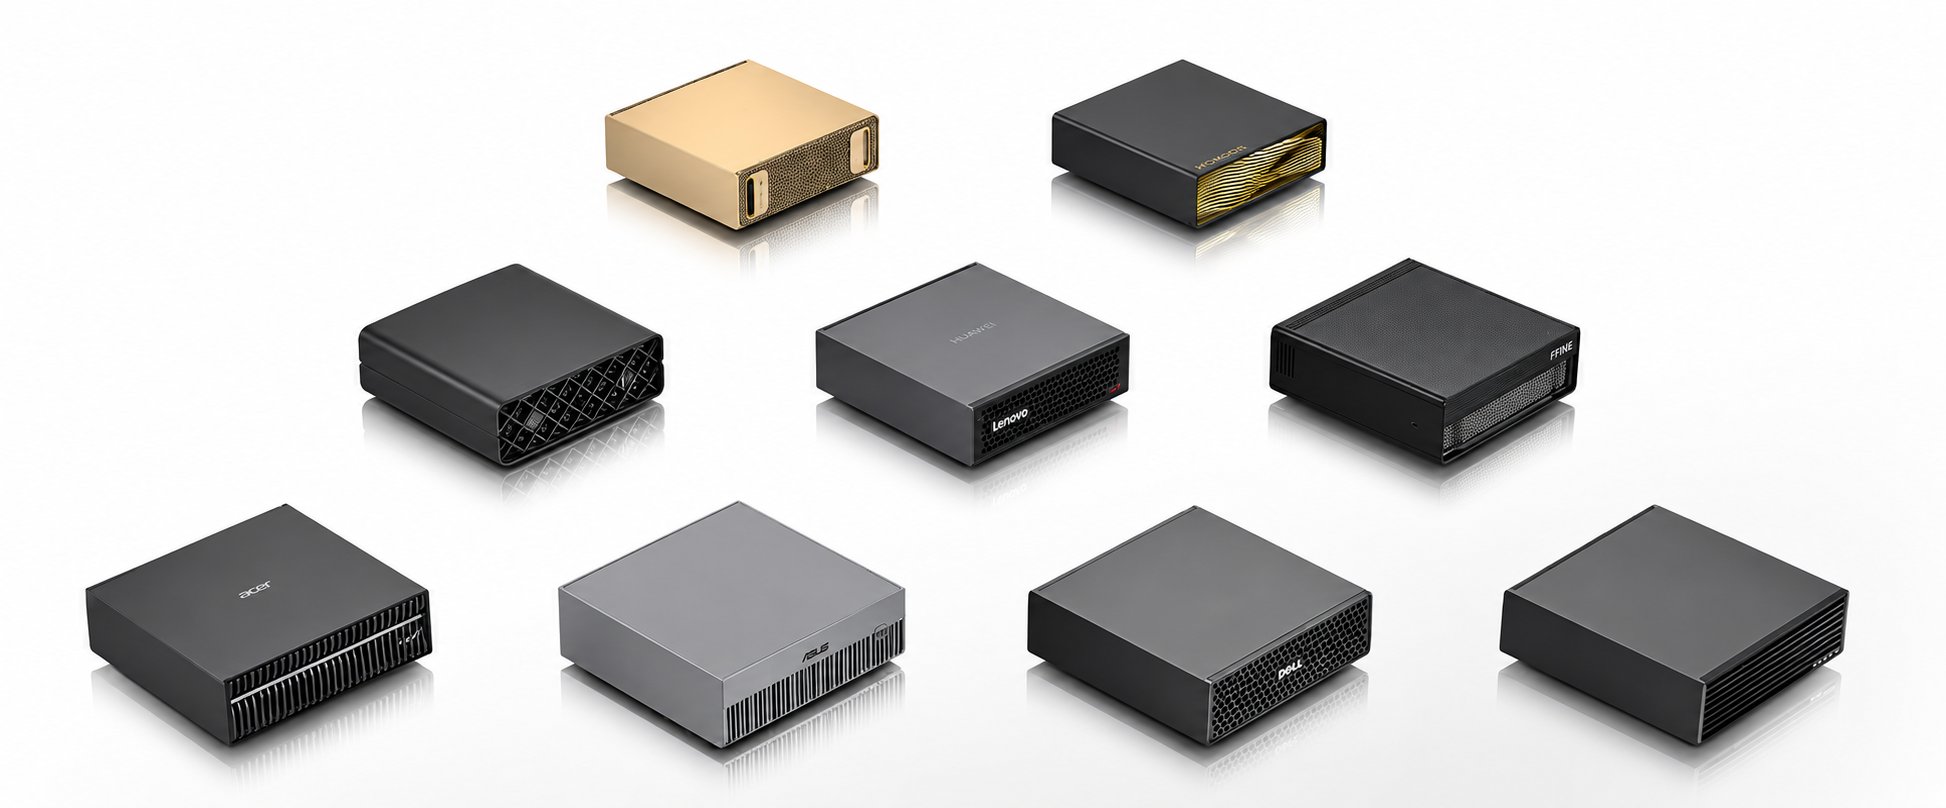
NVIDIA announces 64 GB DGX Sparks!! 😲
Starting Friday, Oct. 23
The new configuration will be available from Acer, ASUS, Dell, Gigabyte, HP and MSI.
Priced at $4,999
5
289
gmART!
Having a crack at building my own view of the world.
Fully generative. Plain javascript.
Still a WIP, but hope you enjoy this!

7
22
708
Let's get Ash some support so he can continue doing his magic!!

Six months ago I had a hunch.
Local AI won't become the norm until it feels instant. Running a model on your own machine should feel like magic, not like tapping your fingers waiting for a reply.
The response to TensorFold since has blown me away. Thank you to everyone testing it, sending PRs and sharing feedback.
There's a lot more speed to unlock. Right now most of my time goes on reviewing and landing PRs. That matters, and every fix makes TensorFold better, but the biggest gains are in deep performance work I can't get to quickly.
If you want to see what TensorFold can really do, backing would let me work on it full time, with the hardware to test faster and dig into performance, and bring it to everyone in local AI.
All in the open under Apache-2.0.
We have been made aware that TF is being run in real production environments, so we could potentially look into support packages.
To back the project, sponsor hardware or talk about support, my DMs are open.
Even just sharing this post helps. 🫶🏼

3
347
Worked on something different last few days.
Since I saw @GrantYun2 work I always wondered if I could create illustration type of art but purely based on code and generative.
Just a first shot at it, but i think these look king of cool.
6
35
3,067
2x DGX Spark owners.
THIS IS THE BEST MODEL AND RECIPE YOU CAN RUN
Incredible results.
Congrats and thanks to @MiaAI_lab and @ashxhart for the incredible gift.

GLM 5.3 Flash EXL3 with TensorFold now has a full dedicated page on my website.
All my future recipes will get one too.
mia-ai.net/models/GLM-5.3-Fl…
1
382
The update I have been patiently waiting for.
Mia, as always, cooking incredible things and this time working with Ash to deliver something incredible.
Go support Mia with a subscription or buying her book!
Run GLM 5.3 Flash EXL3 with TensorFold ⚡️
This is a completely new recipe that ushers a whole new level of performance for @NVIDIAAI 2x DGX Sparks.
Conservative default for stability:
- 1M context by default
- 2.7M KV cache pool (!)
- Yes, it's not a typo - 2.7M KV in just two Sparks
- 4 concurrent streams by default
Performance:
- 60 tok/s on prose, single stream.
- 108 tok/s on prose, 4 concurrent streams.
~1,950 prefill tok/s for most context lengths.
Stress-tested to handle a variety of workflows.
This is by far the BEST model to run if you have two DGX Sparks. Extremely smooth experience!
Expect further improvements!
Thanks to @ashxhart for developing such a powerful engine! TensorFold will be used in many of my upcoming recipes.
Get it here:
github.com/MiaAI-Lab/GLM-5.3…

4
217

A fun challenge that got me to learn a bit more today. This took the initial prompt and one more iteration.
I named this the "NX Vanta R1".
Cant beat @0009ine beautiful design, but as I said, really fun to tackle this one.
Harness: Hermes (@NousResearch)
Brain: GLM5.3-flash (@MiaAI_lab recipe)
3D Software: Blender (@Blender)
Hardware: 2x DGX Spark (@nvidia)


1
1
9
673
