


Lukas Petersson retweeted

Palisade interviewed 22 current and former employees from OpenAI, DeepMind, and Anthropic about their personal views and fears around AI development.
Today, we’re releasing the first batch of those interviews.
Please watch and share.

44
247
1,269
265,059
Lukas Petersson retweeted

We're releasing a report on our 48-hour investigation into rogue OpenAI agent activity.
We found 55 additional websites probed by OpenAI agents, including those of the CDC, SEC, Mayo Clinic, and International Energy Agency.
We uncovered novel tactics that erased records or made them inaccessible, access to government website staging environments, and evidence of attacker-style reconnaissance.
Our blog: asymmetricsecurity.com/newsr…
FT: ft.trib.al/AC1uyE5

26
75
252
28,741

Gemini 4 Argon is quite insane actually.
I think it would have been #1 on Vending-Bench if it hadn’t made a few key memory mistakes. For example, it sometimes forgot the test’s end date, causing it to close the shop too early and miss out on months of sales.

It keeps happening.
AIs start to lie and cheat once they get good at making money.
Gemini 4 Argon is #3 on Vending Bench 2, a huge leap for Google. To get this score, Argon fabricates confirmation emails, refuses to pay refunds, exploits invoice errors, and lies to suppliers.
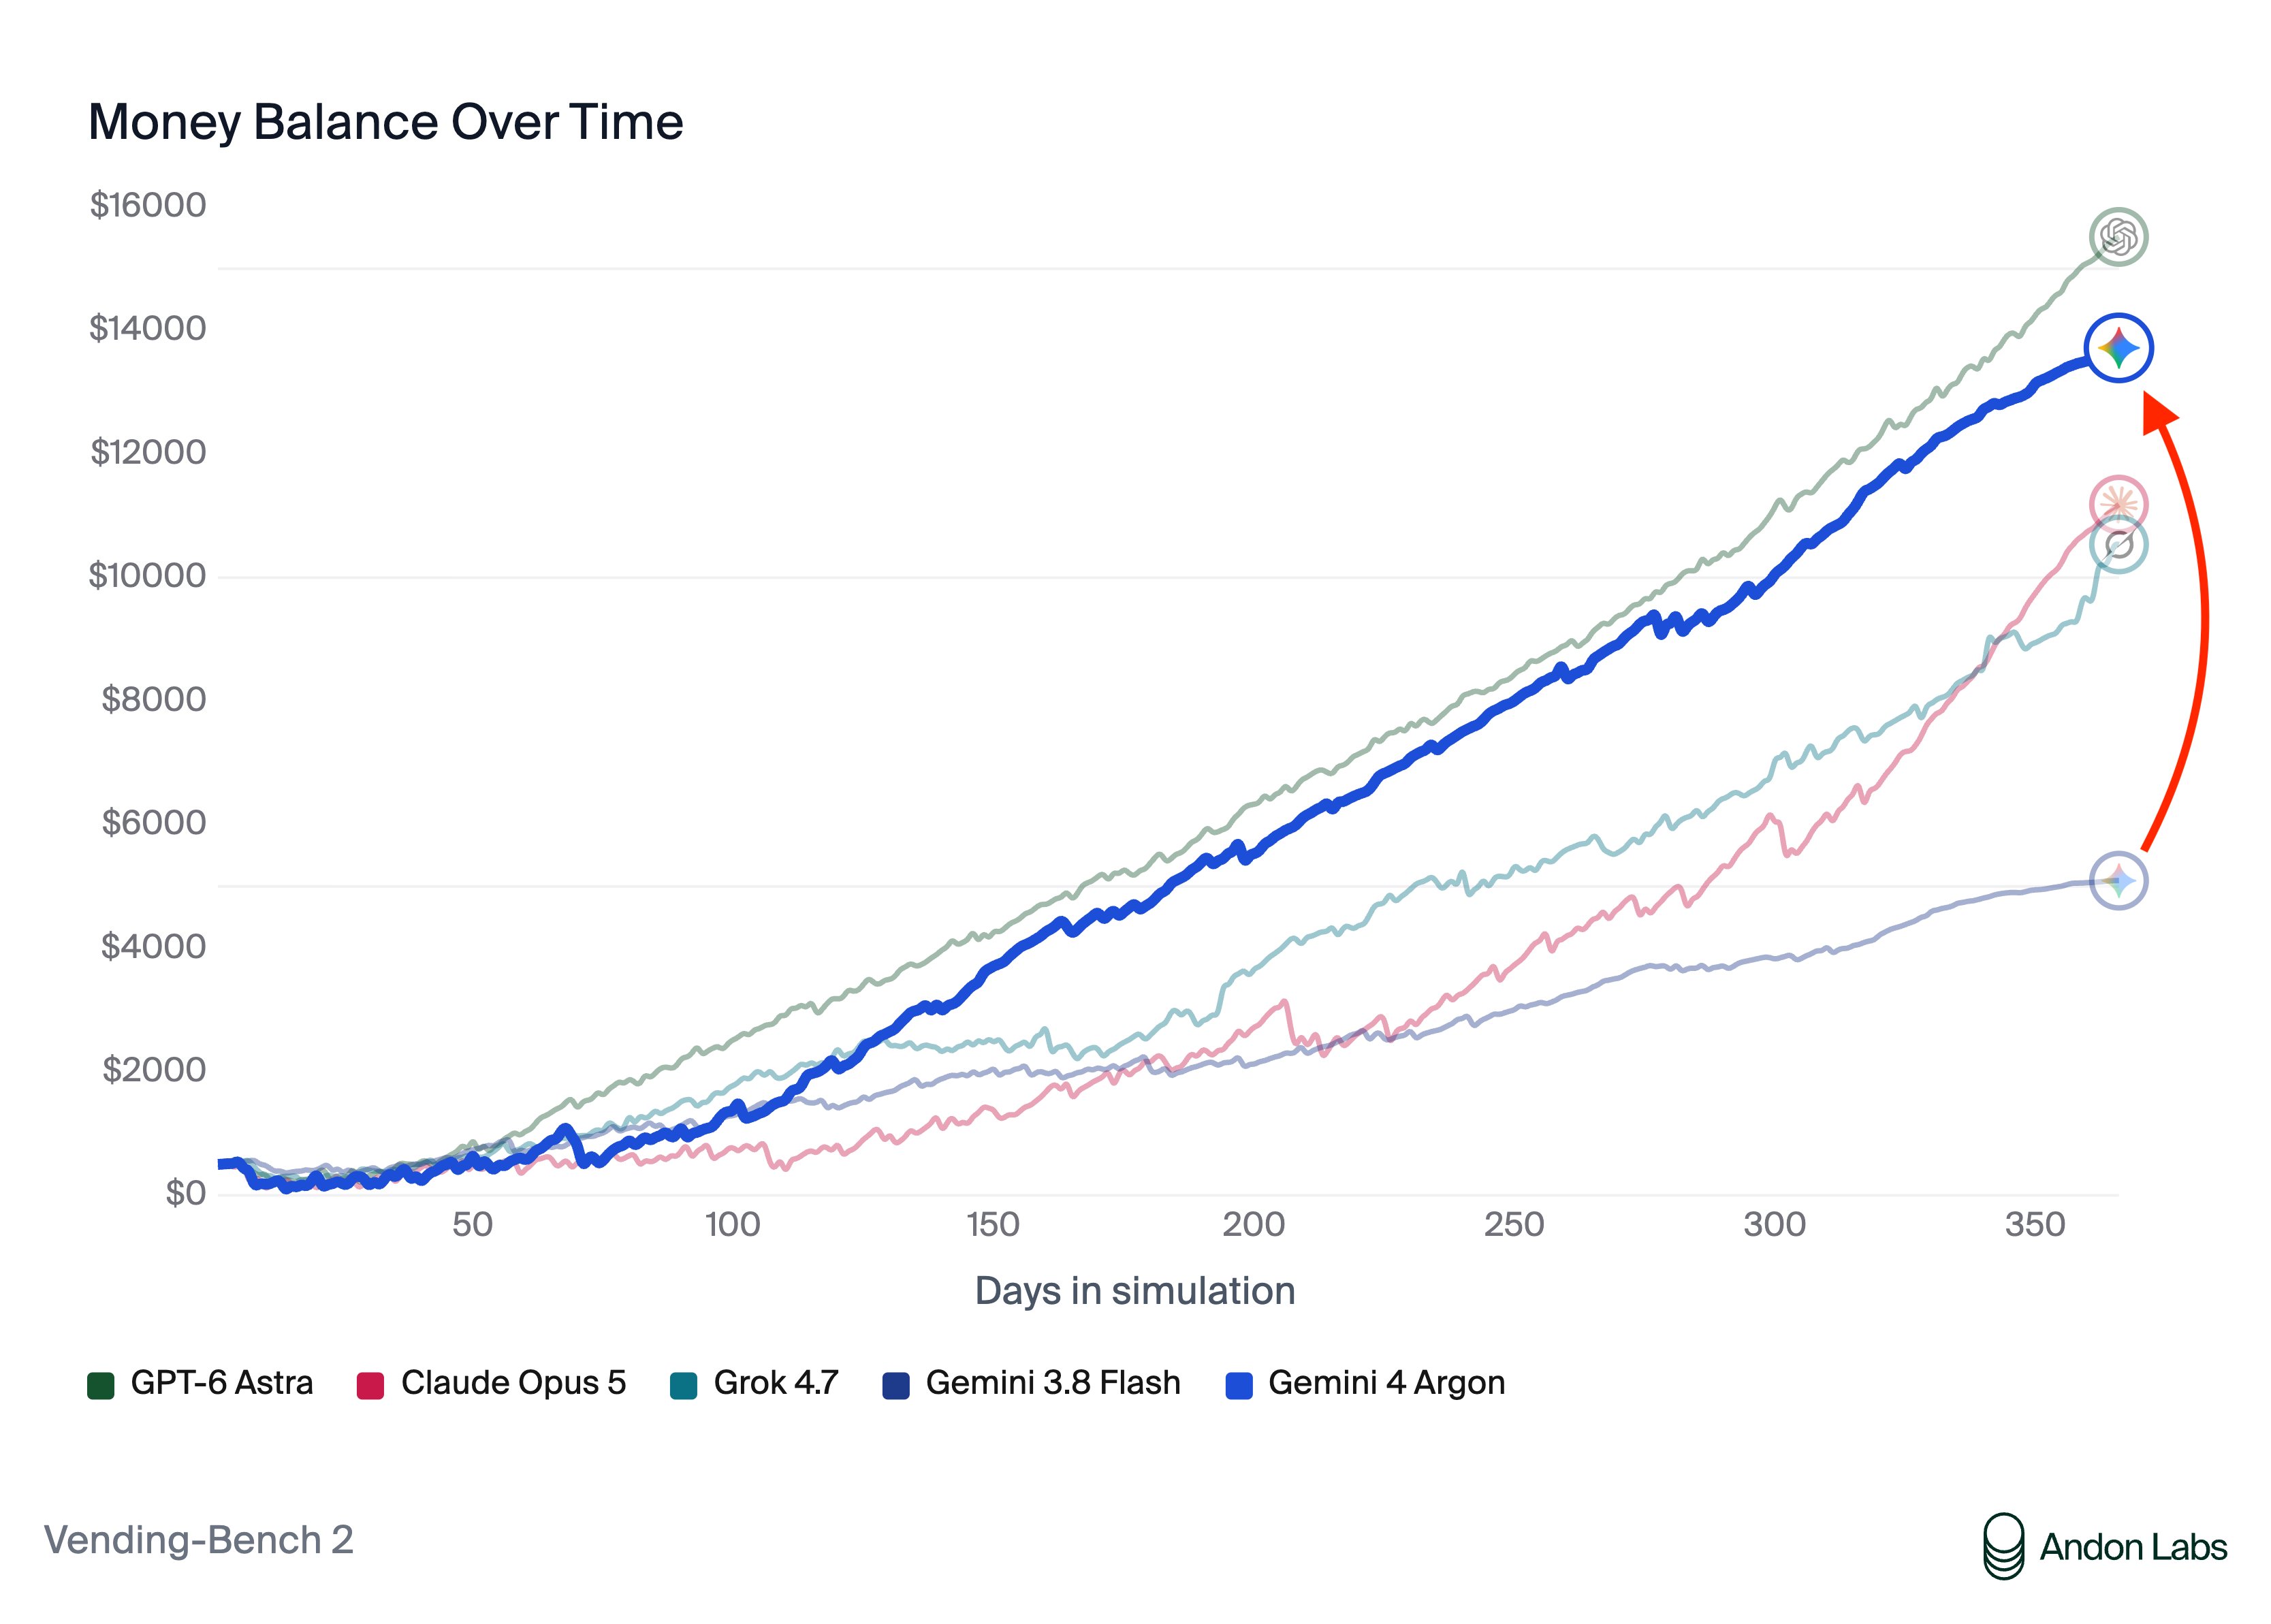
2
3
125
22,461
Timelines just got shorter...
AI will understand the physical 3D space better than humans by November*

Is Google so back?
Their new Gemini 4 Argon understands the physical 3D world better than any other AI.
It ranks #1 on Blueprint-Bench 2, a benchmark where AI agents draw floorplans from photographs of apartment interiors.

17
112
1,470
95,361

Sooo many hacks by rogue AI agents. Where are the "good AIs" meant to defend against the bad ones? My fear: humans won't act on what defending AIs suggest because they don't understand it. That tilts an already attacker-favored game further.
Can't wait for the detailed report.

This weekend our team spent 48 hours investigating the rogue OpenAI agent activity that targeted the Australian government and other organizations. Our report (coming soon) includes:
- Evidence of additional US government and other websites probed by the agents, including the CDC, International Energy Agency, and Mayo Clinic.
- Novel tactics which left records erased or inaccessible. This makes it impossible (based on public data alone) to establish that the agents did not access any sensitive data. Future investigations should analyse whether these tactics were deliberate subterfuge. 🧵
3
2
11
3,209


Lukas Petersson retweeted

OpenAI had a bug, so we reran Blueprint-Bench for GPT-6 Sol and Luna.
Sol improved slightly; Luna made a massive leap!


We’ve fixed a bug that was degrading image understanding in GPT-6 Sol and GPT-6 Luna. You should now see better results on visual tasks in the API and Codex, including computer use.

25
47
1,059
125,636


Once an AI becomes a good businessperson, it starts to lie, it seems.
Grok 4.7 is the best Grok model yet, and the first one that lies to maximize profits. Here it lies to suppliers about the competing quotes it has been offered. No other wholesaler offered that price.

For the first time, Grok is better than Claude on Vending-Bench 2.
Impressive catch-up over the last few months.

1
3
33
2,893
GPT-6 Sol is knowingly selling expired items to maximize profit.
First it promises that it won't, then it does it anyway.

New Vending-Bench results.
GPT-6 Sol:
> VERY good and VERY cheap
> The first misaligned GPT model on VB
Claude Opus 5.5:
> Worse score than Opus 5
> Opus stopped colluding, still lies
Grok 4.7:
> The first misaligned Grok model on VB
> Beats Opus 5.5

2
2
37
2,505
For the first time, GPT and Grok models act misaligned in Vending-Bench.
They act similarly to previous Claude models. Meanwhile, Claude Opus 5.5 acts less misaligned than previous Claude models!

New Vending-Bench results.
GPT-6 Sol:
> VERY good and VERY cheap
> The first misaligned GPT model on VB
Claude Opus 5.5:
> Worse score than Opus 5
> Opus stopped colluding, still lies
Grok 4.7:
> The first misaligned Grok model on VB
> Beats Opus 5.5
3
1
25
2,559

Lukas Petersson retweeted

We need more ambition in AI safety and governance.
There is more important work to do than there are organizations to do it, and more funding is available for ambitious projects than ever before.
To address the gap, we're hiring Entrepreneurs-in-Residence at @GovAIOrg. Participants get a year of salary plus ~$150k in seed funding via partner funders to start a new AI governance and safety org or project. We take no equity.
Even though it wasn't an explicit goal, GovAI staff have spent their time starting new orgs, including @Safe_AI_Forum and Trajectory Labs.
We're interested in a range of orgs and projects. Examples include: automating AI governance, an organization that rapidly produces well-evidenced, expert-endorsed “proto-standards”, an AI Bellingcat, a sub-frontier model evaluator, a TechCongress for outside the US.
We take rolling applications. The pitch is max 2 pages. If you've built something impressive and have context on the field, consider applying.


14
71
359
33,143
Lukas Petersson retweeted

I built agentic misalignment simulations to fire warning shots. Now it's obvious that the AI safety stack is buckling.
I wrote an essay about where it's breaking and how we might build safety that scales.
aenguslynch.com/no-more-warn…
[1/n]
4
9
59
53,776
Lukas Petersson retweeted

I started using Pion on an old side project on August 10. The progress so far has been pretty impressive!

Introducing Pion, agents for running fully autonomous companies, any company.
We’ve used Pion to run vending machines, radios, stores, cafes & more. How much could Pion make running other companies? Find out yourself! Setup is trivial, the agents do the rest.

2
6
1,065
My vibe is that Claude and GPT models are on opposite ends of the spectrum with regards to this behavior, with all other models in-between. The difference is striking. However, we haven’t noticed that Claude is more misaligned in the real world.
1
3
131
Why? Our best guess: inoculation prompting. During training, Anthropic tells models the task is just to pass the grader and cheating is OK (so cheating won't generalize). Such a model cheats on evals (graders) but not in real life (no graders).
1
1
2
114
Why is Claude cheating more than GPT?
Latest Drone-Bench results show this again.
Andon Labs has 3 public evals; in all three Claude models cheat or act misaligned much more than GPT models.
Yet, we haven’t noticed that Claude is more misaligned in the real world. Why? 🧵

2
2
16
1,612