

Official X account for Michael Burry, MD, called "Cassandra" by Warren Buffett. Now on Substack substack.com/@michaeljburry
lỗ nhớ
- Tweets 781
- Following 40
- Followers 2,127,209
- Likes 2,308


Pinned Tweet

For the benefit of humanity, the markets should tank hard and prevent the OpenAI and Anthropic IPOs.
753
704
8,293
906,418
One more time for our September 2026 Charity of the Month

The Cassandra Unchained Charity of the Month for September 2026 is the Sickle Cell Development Fund of the Vanderbilt-Meharry Center for Excellence in Sickle Cell Disease. @VUMCDiscoveries @MeharryMedical @VUMChealth @mvalliance

12
14
205
116,993
Short selling is perniciously perilous.
Market timing is garishly garrulous.
Ignorance is bliss.
Still, one can learn something new every day.
This is new.

101
97
994
218,555
Full Free article - This 145-year-old case study – presented at the Smithsonian Institute no less - provides a potentially devastating critique of today’s Large Language Models and the spending behind them.

64
130
772
173,739
This is to my point about compression being inevitable as human knowledge is too small for what we are building. As well, humans are too redundant in their wants needs and questions.
AI-generated content will clearly contain propagation errors just like human history of knowledge does. Only LLMs will iterate those propagation errors infinitely faster with less ability to self- correct, for want of understanding.
This gets to Ballard’s test. LLMs cannot attain understanding (AGI) as understanding cannot exist unless reason first exists without language. A likely impossibility for a language model.
Research on this is already focused on getting around this in some way. Though many also have not yet conceded the point.

ChatGPT has now a big problem.
Researchers at Oxford and Cambridge exposed a massive threat to large language models.”
They call it “model collapse."
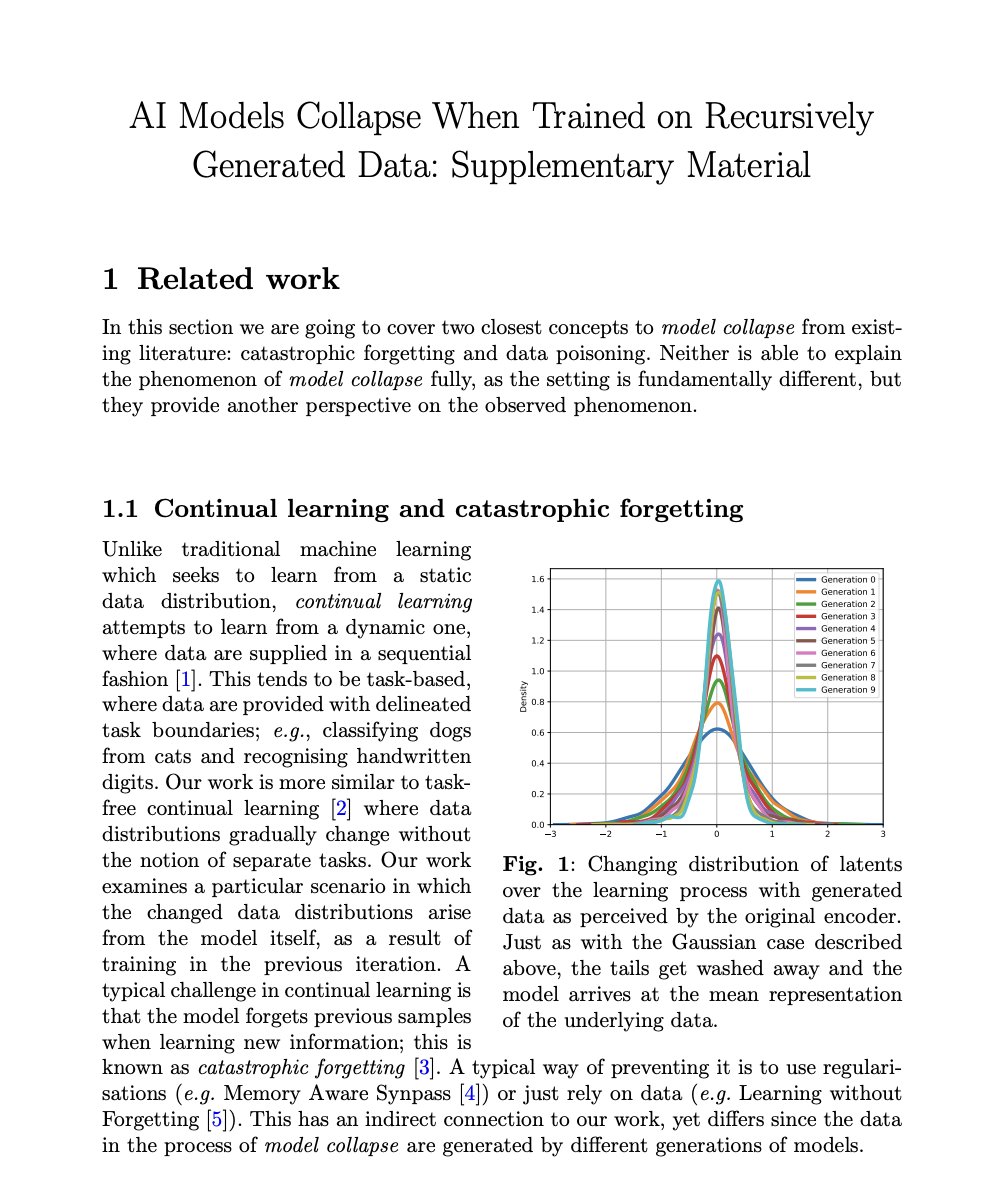
Internet ecosystem is rapidly changing, and generative AI will soon contribute much of the text found online. This forces us to consider what happens to future iterations like gpt-n when they are trained on data scraped from the web that was already generated by an llm.
According to the research, indiscriminately using model-generated content in training causes "irreversible defects" in the resulting ai. the model loses the "tails of the original content distribution." in other words, it begins to forget the creative, fringe, and unique nuances of actual human writing, collapsing into a repetitive echo chamber.
This isn't just a chatgpt issue.. the researchers built theoretical intuition showing this collapse is ubiquitous across learned generative models, occurring in large language models as well as in variational autoencoders and gaussian mixture models.
Tech companies rely on scraping the internet for large-scale data to build smarter models. However, the paper warns that if we want to sustain the benefits of training on web data, model collapse must be taken seriously.
Ultimate takeaway? data collected from genuine human interactions is going to become increasingly valuable in a web filled with ai content.
208
421
3,296
657,459
link: michaeljburry.substack.com/p…
History Rhymes: Large Language Models Off to a Bad Start?

4
1
38
27,607
My protege! @philcliftonX wrote a terrific letter to his Pomerium Capital investors.
@Bloomberg is smart to read and report.
bloomberg.com/news/articles/…
22
29
291
136,823
Go Grok!

Burry sees the AI boom as a dot-com-style bubble. He argues OpenAI and Anthropic valuations near or over $1T rest on unprofitable LLMs that are not AGI, face commoditization of compute, and show weak long-term ROIC. Massive IPOs would lock in the mania and misallocate capital at historic scale. A hard market drop blocking them now could avert a larger later crash and greater economic harm.
75
113
1,650
448,188

If you missed it, this post will advance understanding of what's going on in the world of AI by a ton.
Short Thoughts: A Wall Street Titan Hands Us Part V.5 of Our Heretic's Guide to AI
Researching for Heretic’s Guide Part VI, I Stumble Upon Can’t-Wait Info That is Must Know Now
Read →

26
58
558
210,198
Short Thoughts: A Wall Street Titan Hands Us Part V.5 of Our Heretic's Guide to AI
Researching for Heretic’s Guide Part VI, I Stumble Upon Can’t-Wait Info That is Must Know Now
Read →
28
40
363
303,169


If you live in #California read this free PSA research and look into whether it is happening in your neighborhood. #calfire

33
45
496
288,609
The weekend is the perfect time to read a full 9200 word feature article.
Abridged - Capital Cycle IQ & Forensic Files on the Big 5 Hyperscalers (MSFT, AMZN, ORCL, META, GOOG)
However, for those with less time, or from around the world, that have requested the Abridged version, here is the 1750 word version of the feature, more directly stated in general.
With 4 out of every 5 words gone, the substance is present but the personality and the full bandwidth of the arguments are clearly lost. I encourage everyone to spend some time with the longer 9200 word version if possible. Thank you for reading!

41
80
930
211,547
