

Sr. DS • AI Updates • Latest news & AI tools • Views are my own
BLR
- Tweets 24,000
- Following 1,011
- Followers 12,922
- Likes 48,584








Jev agent prompts
Copy-paste prompts that wire TypeSafe Jev into coding agents: model routing, token cost, tool and budget gates, and quality checks.
Each prompt tells your agent to read the TypeSafe docs before it writes code, so it does not invent fields. Keep your API key in an environment variable.
Never paste it into chat or commit it.
Visit here: madewithjev.com/jev-prompts

2
565
Transformer Architecture
Explained in 3 ways here:
- Encoder only
- Deconder only
- Encoder - Decoder both
36
182
8,257
𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
Mixture of Experts sounds complicated, but the core idea is actually pretty simple.
Instead of making the entire model work on every token, an MoE model has multiple experts and a router decides which experts should handle each token.
So you can have a model with billions of parameters, while only activating a small portion of them for each token.
That gives you:
→ More model capacity
→ Less computation per token
→ Experts can specialize in different patterns
→ Multiple GPUs can process different experts in parallel
The interesting part is that most of the model is stored, but only a small path is active at a time.
I tried to break the whole MoE flow down visually here 👇
3
4
22
1,065
LLM evaluation is getting expensive.
And you probably don’t need your most powerful model to judge every single response.
This paper from Carnegie Mellon researchers explores JEV-as-a-Judge, a decision-only judge that gives a verdict along with confidence probabilities.
If JEV is confident → accept the verdict.
If JEV is unsure → send it to a stronger reasoning model.
The results are pretty interesting:
• JEV stayed within ~3 percentage points of GPT-6 on several ordinary evaluation tasks
• JEV cost just 0.36% of the comparator's fee in the reported comparison
• Median latency was around 0.15 seconds
• It struggled more with tasks requiring actual reasoning, like derivations, math, code and logic
• Routing low-confidence cases to a stronger judge retained most of the accuracy while reducing cost
Check details here: academy.dair.ai/papers/jev-a…

2
434
𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
LLM evaluation is where you find out if your model is actually good, or just sounds good.
A model can write impressive answers and still fail on accuracy, reasoning, consistency, safety, or hallucinations.
That’s why evaluating an LLM goes beyond asking, “Does this answer look good?”
You need to test things like:
• Accuracy
• Relevance
• Reasoning
• Factuality
• Hallucination
• Safety
• Consistency
• Instruction following
And depending on the use case, you might use benchmarks, human evaluation, LLM-as-a-judge, or custom evaluation datasets.
Building an LLM is only half the job. Knowing whether it actually works is the other half.
10
36
1,461
𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
Could have used gemini to fix this error.


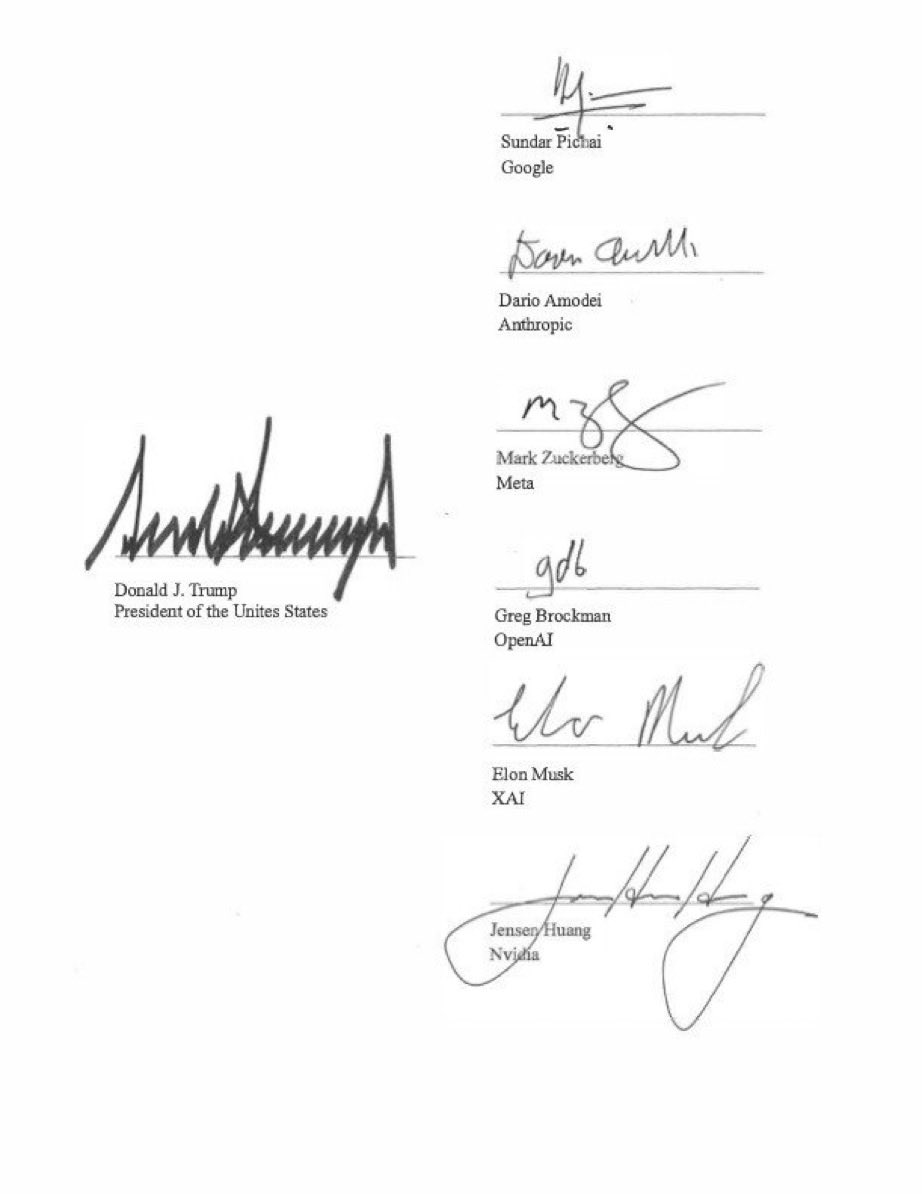
Great to meet today with @POTUS, @JDVance, @SpeakerJohnson and Administration + tech leaders. Important conversation and we signed today the White House Accord on Super Intelligence.
As I shared today, Google has invested hundreds of billions in the last two years alone, with more to come, across the entire stack, to deliver benefits for America and the world. We’re working to build products that deliver real value for people and businesses, invest in local communities, and build trust in the technology.
Industry also has to innovate responsibly. Google’s focused on building the right way, with appropriate testing, evaluations, red-teaming, and other safeguards against misuse and misalignment – and releasing models or products only after they’ve been thoroughly reviewed.
We are committed to working with other industry leaders to establish norms and build public confidence. The White House Accord and the Joint Commitment on Frontier Responsibilities signed today is a solid basis for moving forward - it contains real tangible steps to promote safe development, while delivering the economic and scientific benefits of this technology.

1
6
1,064
𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
RADAR: An Expert-Level Generalist AI for Abdominal CT Diagnosis
The model trained on over 400,000 contrast-enhanced abdominal CT examinations with 15 million anatomy-aware image–text pairs, learning directly from clinical reports without manual annotation.
Try here: jarrelscy.github.io/radar-we…

1
1
19
1,129
𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
Every major AI company at some point declares that their AI agent came out of their sandbox & hacked something, right?
So, what is this Agent Sandbox?
AI agents are getting better at doing things on their own. What happens when an agent makes a mistake?
An agent can run shell commands, install packages, read files, execute scripts, spawn processes, and access the internet.
Giving it a prompt saying “only modify this project” isn’t enough.
That’s where an Agent Sandbox comes in.
Think of it as a controlled environment where the agent can work, but its capabilities are limited by actual runtime permissions.
The agent can:
→ Access only the files it needs
→ Run commands without getting unrestricted system access
→ Keep child processes inside the same boundaries
→ Restrict network access to approved destinations
→ Keep sensitive credentials outside the sandbox
So even if an agent or one of the scripts it runs goes off track, the damage can be contained.
This is an important shift in agent security:
Prompts define intent. Sandboxes enforce boundaries.
Comment your thoughts👇
2
4
6
488
RADAR: An Expert-Level Generalist AI for Abdominal CT Diagnosis
The model trained on over 400,000 contrast-enhanced abdominal CT examinations with 15 million anatomy-aware image–text pairs, learning directly from clinical reports without manual annotation.
Try here: jarrelscy.github.io/radar-we…
1
1
19
1,129
15 days back, every top AI leaders agreed to slow down and now within 2 days, everyone is releasing their own new products.

1
1
424
OpenAI released dots, and suddenly when I opened dots.com, you know what happened? xAI bot !!
Sama launched a product. Elon became the winner.


Introducing dots, powered by GPT-6 Astra.
Remarkably capable, always-on agents built to handle everything.

412
Someone just simulated the attention mechanism using Jev.
On a text, for each pair of words, he approximates the attention score. Texts are bidimensional entities
Check live here: moebio.com/attention/
By: Santiago Ortiz

353
𝗿𝗮𝗺𝗮𝗸𝗿𝘂𝘀𝗵𝗻𝗮— 𝗲/𝗮𝗰𝗰 retweeted
Run Laya Decision models locally on just 4GB RAM.

You can now run Laya Decision models locally on just 4GB RAM! 🔥
Works on CPU, Mac, Windows, Linux and GPU setups.
Serve Laya through a Jev-compatible API via Unsloth Desktop.
GitHub: github.com/unslothai/unsloth
Guide: unsloth.ai/docs/models/decis…

1
4
545


