

Full time CEO @t3dotcodes & @t3dotchat. Part time YouTuber, investor, and developer
San Francisco, CA
- Tweets 68,117
- Following 4,281
- Followers 396,423
- Likes 385,465


Pinned Tweet

A lot of people have been asking me “how do I actually use 6 Claude subs and 3 Codex subs?” I got drunk as I tried to explain it.
IMO this is one of my best videos ever. Early apologies if it gets you banned 💀

114
69
2,387
185,408


To quote @rough__sea
“whenever you're designing a program, like there's things that you think might be cute to add in, you always regret those if they are unnecessary and simply cute.”

my @ChatGPT Dot took 5 rings to answer me
my @grok @bot answered in about .5 seconds, no fake phone UI or ringing
this is a terrible UX @thsottiaux , no one wants to pretend we are on more phone calls in 2026


3
1
31
2,051
Theo - t3.gg retweeted

Updated my AI orchestrator tier list, based on daily use.
T3 Code Nightly → SS. The latest updates put it ahead of everything else I've tried. Smooth, intuitive, and easy to follow.
Traycer → A. The last two updates added useful features, but I'm running into agents that stall and need repeated nudges to keep going.
Maestri → B. Still a great tool, but the workflow is built around the terminal, and I'm moving away from that.
Synara → C. Recent updates have made it noticeably better.
My priorities are changing: a clear interface, less babysitting, and a workflow that keeps moving.
What would you rank differently?

43
10
285
25,643
🫡

This video by @theo gave me superpowers.
I genuinely can’t believe he is giving away all that for free.
I revived an old MBA with Omarchy+Tailscale installed and I’m flying using it as a remote machine.
piped.video/D8PikZ1KhUo?si=cmNO…
9
51
5,186
Made more improvements to the usage view in T3 Code. Much easier to see where your "spend" is and how different models behave based on your own data
btw this measures all usage of Claude Code and Codex on your machines, not just usage within T3 Code :)

60
3
301
11,065
He refused to share the transcripts and claimed I’m “jealous”? I think he’s mad that I figured out about his crypto scam 🤷

@theo, it's very clear you're jealous of BridgeMind.
Some of your questions were fair. I'll be sharing more on the NerfBench methodology soon.
But asking me to take NerfBench down and post an apology written by you isn't about better benchmarks.
It's about your ego, and not wanting anyone else to exist in this space.
More benches are good for everyone. Build yours.
70
3
499
31,689
Receipts:

@theo yeah someone already did, but If you need more evidence I’m sure the old mod team including me can provide it. Most of the discord logs he nuked . He banned us all when we called him out
6
72
10,725
Opus 5.5 is the first model we've seen break the 50% traffic threshold in T3 Code. Literally half of all prompts go to Opus

168
33
2,786
76,692


Theo - t3.gg retweeted

The problem of subscription limits forcing you to restart is solved.
RIP my sleep.
4
3
174
44,092
This felt so weird initially but I'm obsessed with it now. I have 18 threads working here and it doesn't feel claustrophobic anymore.
Things appear when they need your attention, and disappear when they don't.


New (beta) T3 Code feature: "Hide threads while working"
I have been thinking about adding this to T3 Code for awhile now. Don't like "running work" taking space in my brain.
Not sure how I feel just yet but good vibes so far. Try it and lmk how you feel!

124
7
1,065
61,116
Theo - t3.gg retweeted

I agree with Theo here. A Claude Code Update, A Provider Change, A cache hit change, A bad request, New seed anything can change a prompt's outcome in just a matter of minutes. These bench's don't make any sense unless done extremely carefully with some kind of private API by each model provider or something as most providers now block Top P and stuff.
I apologize in advance for this crash out, but holy shit I'm so tired. I'm trying to figure out what is even being measured here and it's nearly impossible.
I read the post. It provided no insight whatsoever into how these "tests" work.
Things that were not mentioned:
- Harnesses used
- Tasks used
- How many times tasks are run
- What is done to identify variance in daily runs
- What analysis is done on "bad" runs to detect root causes for failures
- What APIs are being used (matters a LOT)
- How the +/- 10% "variance" was selected
- Why tokens and costs are "weighted" the same, and combined rank roughly as high as intelligence
- Why tokens are included at all when costs are the metric that matters
I'm sorry @bridgemindai - am I missing something here? I just want to make sure I understand fully before building my own alternative bench.
I DM'd you asking for traces from your runs, would be super helpful as I start digging deeper here.
8
4
172
36,196

I apologize in advance for this crash out, but holy shit I'm so tired. I'm trying to figure out what is even being measured here and it's nearly impossible.
I read the post. It provided no insight whatsoever into how these "tests" work.
Things that were not mentioned:
- Harnesses used
- Tasks used
- How many times tasks are run
- What is done to identify variance in daily runs
- What analysis is done on "bad" runs to detect root causes for failures
- What APIs are being used (matters a LOT)
- How the +/- 10% "variance" was selected
- Why tokens and costs are "weighted" the same, and combined rank roughly as high as intelligence
- Why tokens are included at all when costs are the metric that matters
I'm sorry @bridgemindai - am I missing something here? I just want to make sure I understand fully before building my own alternative bench.
I DM'd you asking for traces from your runs, would be super helpful as I start digging deeper here.
Theo is obsessed with BridgeMind.
He hates seeing me win.
NerfBench is not hard to understand.
Here's how it works:
bridgebench.ai/blog/how-nerf…
146
10
1,391
232,405
I'm down to put my money where my mouth is.
BridgeMind put $10,000 towards benching, I'll do the same.
If my benches show I'm wrong, and that there is meaningful model "nerfing" aligned with his viral post, I will donate another $10,000 to a charity of @bridgemindai's choice.
If my benches show I'm right, I want Bridgemind to take down "nerf bench" and replace it with a page apologizing, listing all the reasons the bench was flawed (written by me).
I'm even down to have a qualified third party come in and audit both of our work.
Deal?
82
9
982
107,663

Gonna make an alt account where I just straight up lie about AI stuff and see how quickly I can go viral with it
201
14
2,200
72,444
Love how easy it is to go viral by spreading straight up misinformation
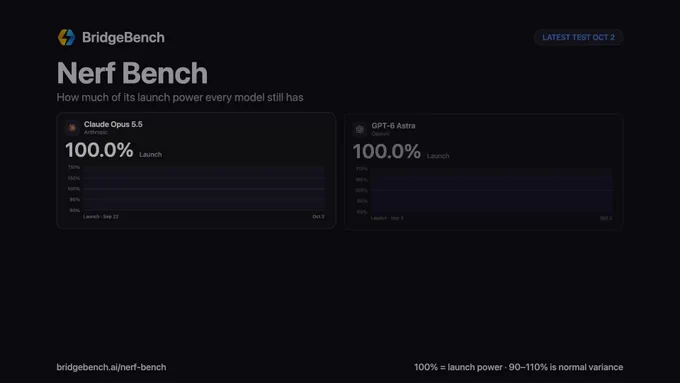
Claude Opus 5.5 just took a big drop on NerfBench.
Yesterday it was scoring above launch. Today it's at 94.2%.
GPT 6 Astra: 98.0%
Sonnet 5.5: 100.9%
GPT 6.1 Sol: 106.7%
94.2% is still inside normal variance, so we can't call it a nerf yet.
But we're watching Opus 5.5 very closely.
130
12
1,181
150,253
