


Built a Woof Pup 🐕 🥳
Woof 4B distilled to 0.6B. Email → triage JSON at 240 tok/s on an M5 Pro, all on-device.
huggingface.co/alexwengg/woo…


Introducing Underdog, your Private Personal AI on devices you already own
Today we're announcing our backing from @a16z @khoslaventures @HummingbirdVC Anthology (@AnthropicAI @MenloVentures) @patrickc @naval @rauchg @polynoamial @Thom_Wolf @Mascobot @tszzl @OfficialLoganK and other top AI leaders
Our mission is to provide free, capable, reliable and private AI to billions of people.
Underdog’s Law: today’s frontier intelligence reaches your devices in six months.
We’re starting with fast, capable AI that runs on consumer hardware. By co-designing models and inference engines, we’re pushing the frontier of capability, speed, power and data efficiency.
Our research also spans agentic commerce, confidential inference, and how AI will reshape the internet economy.
Privacy and capability no longer needs to be a tradeoff. If you believe in this future, join us. Time to build.

2
3
20
1,445
after finetuning my own language model, i decided to give image distillation a shot. clef-flash (9B) → a 0.92B student trained to solve reCAPTCHA-style "select all the cats" challenge with ~150 ms per tile on an M5 Pro.
Apache-2.0 weights: huggingface.co/FluidInferenc…
SDK: github.com/FluidInference/Fl…


introducing 𝚌𝚕𝚎𝚏: our first models trained by @cloudflare's workers ai team.
today, we're releasing two fast and accurate decision models that top the benchmarks for quality and latency. use them hosted on workers ai or grab the weights from @huggingface, because we open-sourced it too.
blog.cloudflare.com/clef-dec…
5
5
24
1,895
1st time fine-tuning an LLM: Qwen3-0.6B on thousands of generated posts allowing it to write replies to tweets.
i was able to get prompt process on the Neural Engine while writing the reply runs on the GPU. Inference speed ~190 ms, ~0.6 GB peak memory, 724 MB model size.
Built on @Alibaba_Qwen's Qwen3-0.6B (Apache-2.0).
Model: huggingface.co/FluidInferenc…
Base: huggingface.co/Qwen/Qwen3-0.…
Swift SDK + demo: github.com/FluidInference/Fl…

5
2
30
2,068
Phonon-2 runs on coreml with ANE in FluidAudio v0.17.5.
1 h of audio → 7.5 s on an M5 Pro (Parakeet v3: 10.7 s).
Full LibriSpeech, same session, ANE:
- test-clean 2.47 % WER at 159× (v3: 2.27 % at 149×)
- test-other 4.62 % WER at 146× (v3: 4.12 % at 138×)
360 MB on disk (321 MB encoder) vs 480 MB for v3. Peak process RSS 0.36 GB for both; the weights sit in ANE. iOS 18+ / macOS 15+ .
Code: github.com/FluidInference/Fl…
Model: huggingface.co/FluidInferenc…


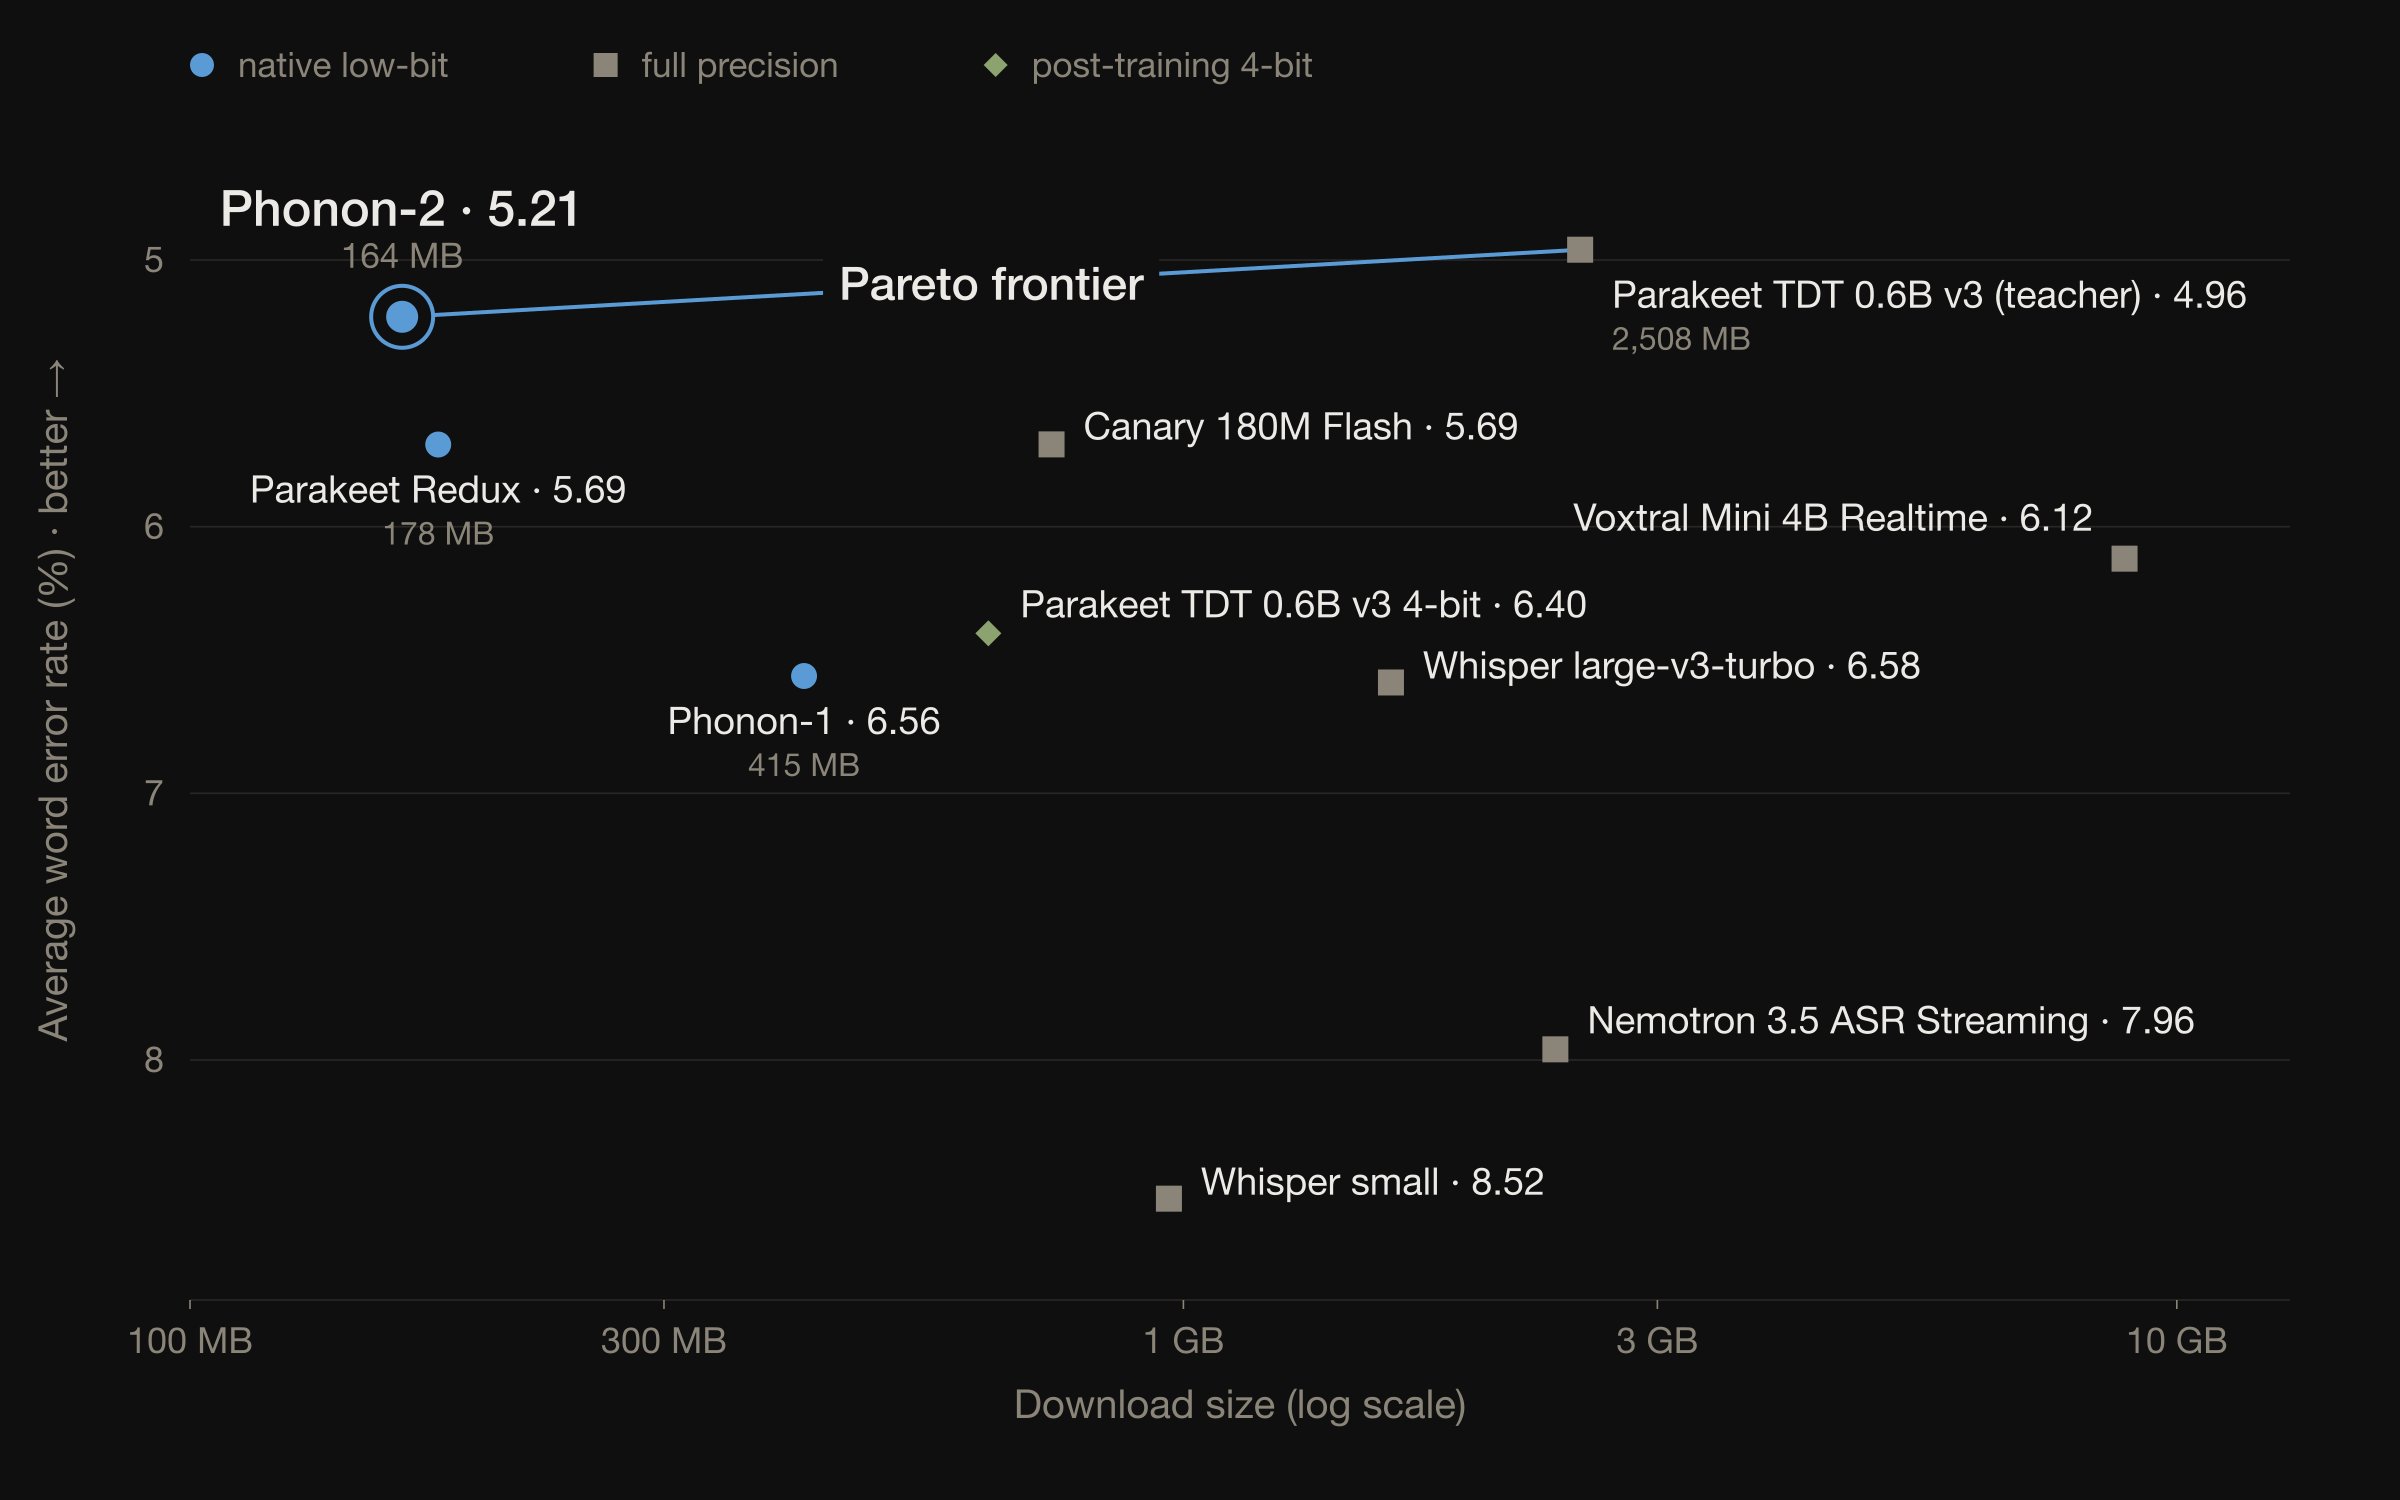
Introducing Phonon-2: a new standard in speech recognition per byte.
At just a tiny 164MB download, it is more accurate on average than OpenAI's Whisper large ( a model 10X its size)
Transcribe an hour of audio in just 20 seconds on a MacBook Air!
Open weights, CC-BY-4.0, today.
@fermion_ai
5
42
3,134
I was inspired by this tweet, using @intern_lm 's Intern-Decision-0.8B i fine-tuned it on Pokémon Showdown with 4B as the teacher.
Plays at ~90 ms a move on Core ML in under 1 GB of memory at int8, against 140 ms and 3 GB for the same model in PyTorch. it plays as well as the 4B and beats its own un-fine-tuned self. it was interesting to see what you can finetune on a M5 pro.
Model: huggingface.co/FluidInferenc…
Base: huggingface.co/internlm/Inte…
Runtime + harness: github.com/FluidInference/Fl…


We turned Qwen3.8-27B into a multimodal decision model.
It beat Pokémon FireRed’s elite four and champion with sub-100 ms decisions from live game state.
With SGLang’s native /v1/decisions, you can now turn LLMs and VLMs into classification and scoring models.
We also added /v1/systemone so Jev-like open models can work with the TypeSafe SDK.

3
2
15
1,109
Saw @CompleteSkeptic's Jev play Doom and wondered how small that loop could get on a laptop.
Ported @DavidGFar's 1.3M SauerkrautLM-Doom to Core ML: 4.9 MB model, 1.2 ms/decision on the Mac GPU, ~7× faster, 84 MB RAM, ~3× less RAM than PyTorch on the same GPU. Kill-for-kill on 100/100 seeds.
model: huggingface.co/FluidInferenc…
code: github.com/FluidInference/Fl…


We love how this doomo doomonstrates real-time intelligence and what can be doone with code + AI!
~10 calls/sec = ~$7/hour

2
6
1,555
Kev on Core ML 🍎
After seeing this tweet, We got inspired to port Kev-0.8B (the Qwen3.5 variant) and ran Guess Who over 80 Wiki bios, on an M5 Pro, same accuracy, coreml vs original PyTorch:
🚅 37 ms vs 1.07 s per bio → all 80 in 3.0 s vs 99 s
🧠 ~2 GB vs 6.6 GB memory
📦 1.45 GB vs 1.79 GB model
Model: huggingface.co/FluidInferenc…
Code: github.com/FluidInference/Fl…


UPDATE: Kev-0.6B, 4B, and 8B are now available. Kev is a family of small open source Jev-like decision models you can train and run yourself.
This new family is based on Qwen3 using the same LoRA + small pointer head technique as before, but scaled up.
Out of domain, on data Kev never trained on: Kev-8B 79.6%, Jev 85.7%.
• Drop-in TypeSafe System One API; their SDK works with one `base_url` change
• Kev-4B serves on a 32 GB Mac in bf16: ~300 ms for five questions, ~40 ms on an H100
• Repeated documents hit a KV cache: 2-2.5x faster
• Apache 2.0 License. Kev-4B trains in 40 minutes on one H100. Kev-8B in 83 minutes.
Code, weights, evals: github.com/jaredpalmer/kev

2
7
82
5,589
over a year late but we converted SigLIP 2 to Core ML and sorted 7,349 pet photos into 37 breeds on a M5
Coreml model vs. base PyTorch model, same accuracy:
• 36 s vs 102 s
• 5 ms per photo vs 14 ms
• 262 MB peak RAM vs 4.2 GB
• 715 MB on disk vs 1.5 GB
model: huggingface.co/FluidInferenc…
code: github.com/FluidInference/Fl…


Introducing SigLIP2: now trained with additional captioning and self-supervised losses!
Stronger everywhere:
- multilingual
- cls. / ret.
- localization
- ocr
- captioning / vqa
Try it out, backward compatible!
Models: github.com/google-research/b…
Paper: arxiv.org/abs/2502.14786

6
35
350
21,050
We have converted GLiNER2.5-Decide to coreml. ~4× faster, ~5× less Peak RAM, half the size.
model: huggingface.co/FluidInferenc…
code: github.com/FluidInference


Introducing GLiNER2.5-Decide, our new 340M parameter open weight, encoder-based decision model.
GLiNER2.5-Decide is built for fast, deterministic classification. The model evaluates a set of user-defined typed questions and rules, and jointly decodes their answers, returning structured decisions with probability distributions and confidence scores.
We evaluated the model’s performance on Fast Decisions, an unseen, internally generated classification suite based on 17 datasets testing real-world use cases across routing, triage, classification, sentiment, and content understanding.
Measured against similar decision models, GLiNER2.5-Decide leads in 9 of the 17 datasets, achieving the highest average score:
- GLiNER2.5-Decide: 60.1%
- SemIf: 56.4%
- JevK5: 57.5%
- Laya: 46.6%
This performance makes the model a strong fit for use cases like tool calling, model routing, browser and computer use, and LLM-as-a-judge.
GLiNER2.5-Decide’s lightweight encoder architecture makes it easy to fine-tune the model for specific tasks, while being efficient enough to run locally on consumer-grade CPUs or in air-gapped environments, giving users greater control over where their data goes and where the model runs.
To make building and experimenting with GLiNER2.5-Decide as easy as possible, we're also offering hosted inference. You can now use our API to run inference and fine-tune GLiNER models on specialized tasks right inside your own coding agent: agent.fastino.ai
As with previous models, we’re also releasing the model weights on @huggingface under the Apache 2.0 license: huggingface.co/fastino/GLiNE…

17
84
885
68,897

Direct links, sorry about that:
model: huggingface.co/FluidInferenc…
Swift + demo: github.com/FluidInference/Fl… (v0.3.0, see Sources/SortAnythingDemo)
Both are public and live: the Hugging Face repo is public and FluidUse v0.3.0
3
2,317
I decided to give fine-tuning a shot: trained Decision-1.0-Lex on a ~6.7k Snake moves dataset on my M5. was relatively quick without needing a dedicated GPU.
the model went from a score of 12 to 36
Model: huggingface.co/FluidInferenc…
code: github.com/FluidInference/Fl…
Base model from vLLM Semantic Router, built by @XunzhuoLiu

1
2
13
1,667
Parakeet 🦜 Ultra 🤗 is now in FluidAudio, running🏃♂️➡️ on the ANE 🔥
Ultra vs v3 on our Core ML benchmarks (M5 Pro, ANE, back to back):
• LibriSpeech clean: 2.13% vs 2.27% WER · 127× vs 129× RTFx
• LibriSpeech other: 3.81% vs 4.12% WER · 110× vs 115× RTFx
• FLEURS, 24 langs: 11.7% vs 14.8% WER · 135× vs 137× RTFx
Model: huggingface.co/FluidInferenc…
Code: github.com/FluidInference/Fl…


Today we're releasing Moondream Parakeet Redux and Moondream Parakeet Ultra. Two speech-to-text models based on NVIDIA's Parakeet. 25 languages. They run locally, wickedly fast.
Redux is for CPUs. Ultra is for GPUs.

2
9
129
13,127
FluidAudio now runs Nemotron 3 Diarization on-device in Core ML. Its able to support 8 speakers with 8 different languages like in the below demo.
Models: huggingface.co/FluidInferenc…
Code: github.com/FluidInference/Fl…
Special thanks to @NVIDIAAI for the early access.


When several people talk at once, a transcript can get messy fast.
Our new Nemotron 3 Diarization model tracks who spoke when, even when voices overlap. It handles up to eight speakers, has 100M parameters, and is now available on @huggingface 🤗

2
14
201
13,355
we ported @knowledgator’s GLiClass Edge Apps v2 to Core ML on an M5 Pro. 32.7M params, ~1.4 ms per decision on CPU. it played 2048 for 2 minutes and reached the 4096 tile.
code: github.com/FluidInference/Fl…
models: huggingface.co/FluidInferenc…


The Jeff model, based on our GLiFormer, should be the most parameter-efficient model (a 500M-parameter model) for its performance score. And we created it right before the Jev release. Right now, imagine if we scale it 😉
4
11
103
7,844
since y'all loved the Tetris we decided to make a follow up. the model harness uses fewer bad moves offered, better wording, one deleted sleep.
A continuous game lasting 35 seconds with a timer included.

Thanks for the model, we were able to port Laya to coreml with 99.5% of the ops on ANE + benchmarked too. it is now blazing fast with 3.7 ms per decision on an M5 Pro.
Release: github.com/FluidInference/Fl…
Models: huggingface.co/FluidInferenc…

1
2
14
2,545
Thanks for the model, we were able to port Laya to coreml with 99.5% of the ops on ANE + benchmarked too. it is now blazing fast with 3.7 ms per decision on an M5 Pro.
Release: github.com/FluidInference/Fl…
Models: huggingface.co/FluidInferenc…

This is NOT Jev.
Open source. Runs on your laptop. Decides in ~27 ms, about 200× faster than waiting on a hosted LLM.
Here it is playing Tetris by itself 👇
brainfunctioncollapse.com/la…

20
111
1,326
116,571
CUA-S1-FORMS now lives in its own repo. FluidUse reads a form in a running Mac app or browser through API, asks what belongs in each field, and types the answer into the real app. ~1 ms per decision on ANE. We plan to convert more compute-use models in the future!
Model on Core ML: huggingface.co/FluidInferenc…
SDK: github.com/FluidInference/Fl…

We converted it to Core ML and ran it fully on-device: 706K parameters, ~1 ms inference on M5 Pro, up to 98.2% ops on ANE and 99.95% accuracy across 24,370 decisions.
we were able to get it down to int4 as well .
SDK:
github.com/FluidInference/Fl…
Model:
huggingface.co/FluidInferenc…

1
1
12
2,810