

Design & Quality Engineer ⚙️ | Crypto Broker 🪙 | BioMedical ⛑️| Video Game & Music Enthusiast | 2x DGX Spark ⚡️ #Bitcoin #Noderunner #LocalAI
- Tweets 51,374
- Following 1,592
- Followers 8,181
- Likes 77,374




Coinupbtc 🪙 retweeted

The gods envy us. They envy us because we're mortal, because any moment might be our last. Everything is more beautiful because we're doomed. You will never be lovelier than you are now. We will never be here again.
1
6
340
Coinupbtc 🪙 retweeted

Are you hiding any compute in this household?

Micro Center requires photo ID and signed no-export pledge to buy RTX 5090 gaming GPU tomshardware.com/pc-componen…
9
28
369
16,618
Coinupbtc 🪙 retweeted

Welcome to Kindle Spark OS!
TL;DR: Add 4GB of RAM to any DGX Spark & faster!
@CK2084, @coffeedev and I figured out how to get 5-10% extra decode and 4GB RAM out of a Spark. We had to replace NVIDIA's OS to do it, but we made it safe and easy.
github.com/kindlingai/kindli…
36
48
408
59,456


The numbers I am getting with GLM 5.3 Flash EXL3 with TensorFold


Run GLM 5.3 Flash EXL3 with TensorFold ⚡️
This is a completely new recipe that ushers a whole new level of performance for @NVIDIAAI 2x DGX Sparks.
Conservative default for stability:
- 1M context by default
- 2.7M KV cache pool (!)
- Yes, it's not a typo - 2.7M KV in just two Sparks
- 4 concurrent streams by default
Performance:
- 60 tok/s on prose, single stream.
- 108 tok/s on prose, 4 concurrent streams.
~1,950 prefill tok/s for most context lengths.
Stress-tested to handle a variety of workflows.
This is by far the BEST model to run if you have two DGX Sparks. Extremely smooth experience!
Expect further improvements!
Thanks to @ashxhart for developing such a powerful engine! TensorFold will be used in many of my upcoming recipes.
Get it here:
github.com/MiaAI-Lab/GLM-5.3…

2
2
230
Coinupbtc 🪙 retweeted

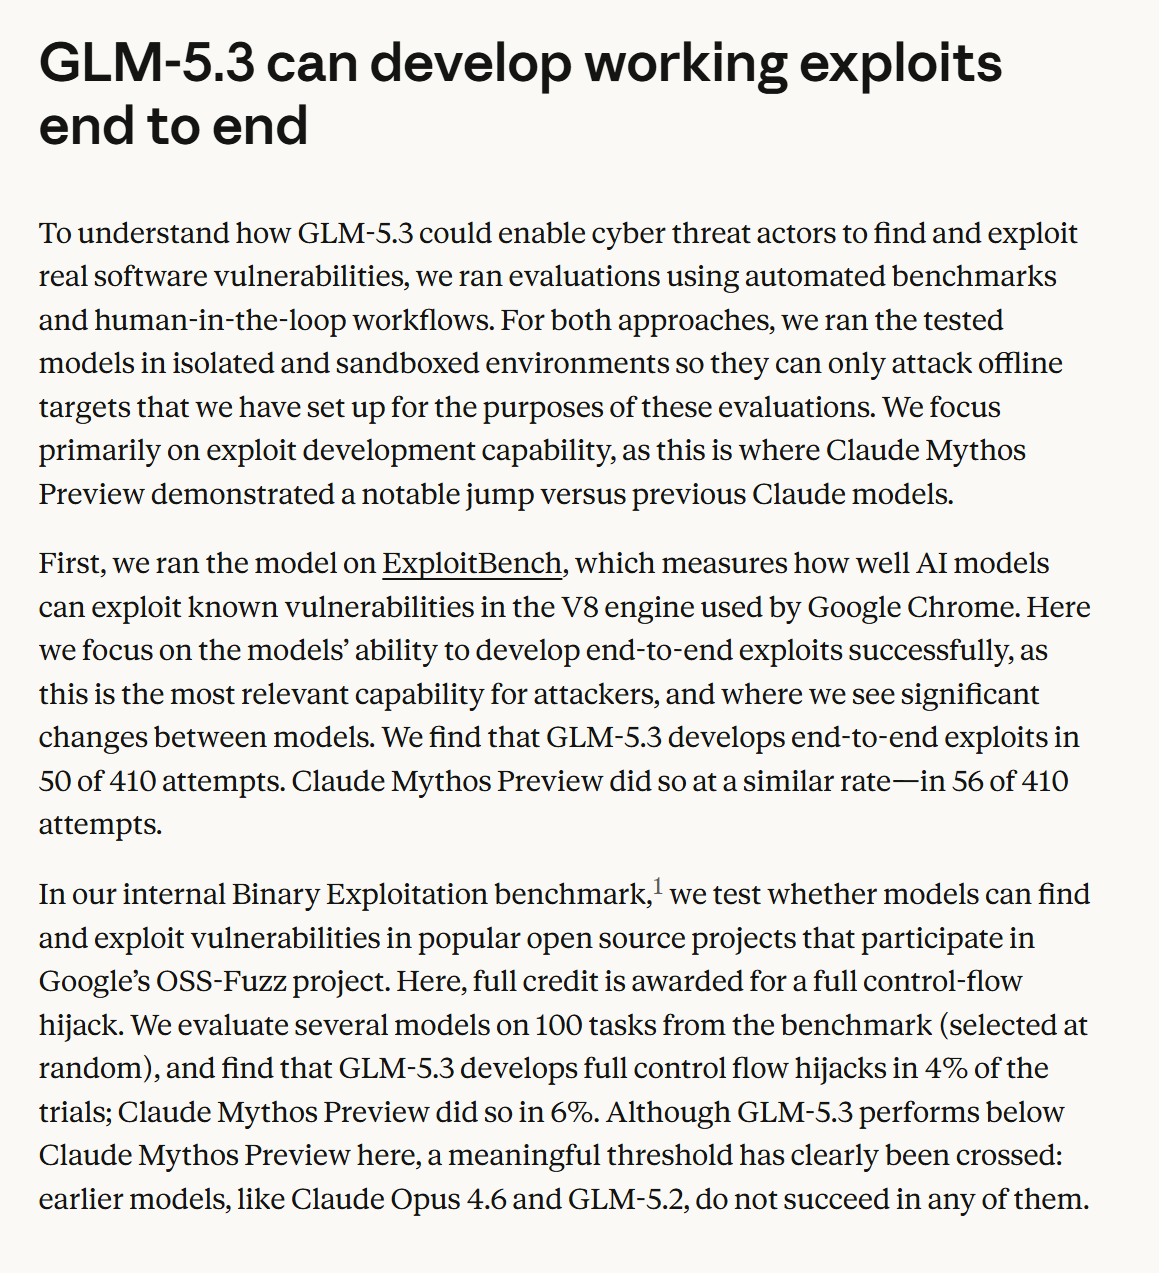
Also applies for GLM 5.3 Flash
Basically Anthropic confirmed my own conclusions that GLM is the most capable < 1T param model you can run locally.
44
63
947
32,546
Coinupbtc 🪙 retweeted

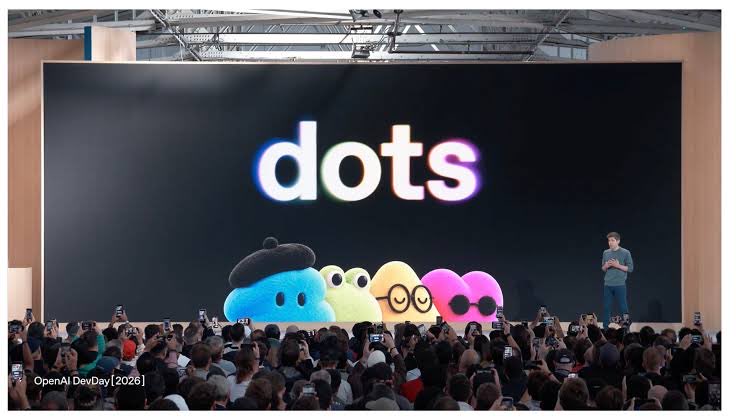
Elon spending $20M on a domain just to troll Sam Altman is peak Silicon Valley villain behavior💀


AHAHAHAHAHAHAHAHAHAHAHA NO WAY.
> OpenAI just announced Dots.
> SpaceXAI bought Dot.com
it redirects straight to the Grok Bot download page. based lmao.
285
575
13,316
3,686,181

Coinupbtc 🪙 retweeted

Your quant doesn’t even know about it yet.
That’s the whole point.
By the time the dashboards light up, the threads start flying, and everybody suddenly “discovers” it… the early crowd already knew.
People are building communities, making real connections, and taking this way further than a meme.
How are you not seeing this yet?
You don’t get FOMO when it’s obvious.
You get FOMO when you realize you saw it early… and ignored it.
solana:C2WtD354XEvS9gzpJDLqzqkADq7wUtmJg1UzUdmL5a21
@McCat__
 𝔩𝔞 𝔪oo𝔫 ☾✨DJ LA MOON

1
5
11
528


Coinupbtc 🪙 retweeted

DGX Spark resale, from 119 eBay sold listings:
Sep 18: new sold for $4,995.95
Sep 28: new sold for $6,499.95
Sep 22-28 median, 7 confirmed new sales: $6,331.67
Retail ran dry first. Micro Center hit 0 of 30 stores Sep 23. eBay caught up days later.
Not financial advice.

5
12
29
6,040

This is definitely a change the Spark now shows Not Carried at Microcenter.. not out of stock.
Thanks for the headsup DCRando2020!
(enlarged it of course).


21
4
79
13,128
