

🎮 Tech, gaming, AI, and everything in between. 🤖 Building with it, not just talking about it. 🔥 From the mind of @ToNYD2WiLD
- Tweets 3,806
- Following 210
- Followers 4,457
- Likes 941


Pinned Tweet

Local AI Is In Trouble: NVIDIA's $4,999 DGX Spark 64GB Makes No Sense piped.video/ppFan-OAaB4

Made with AI
2
2
28
2,455
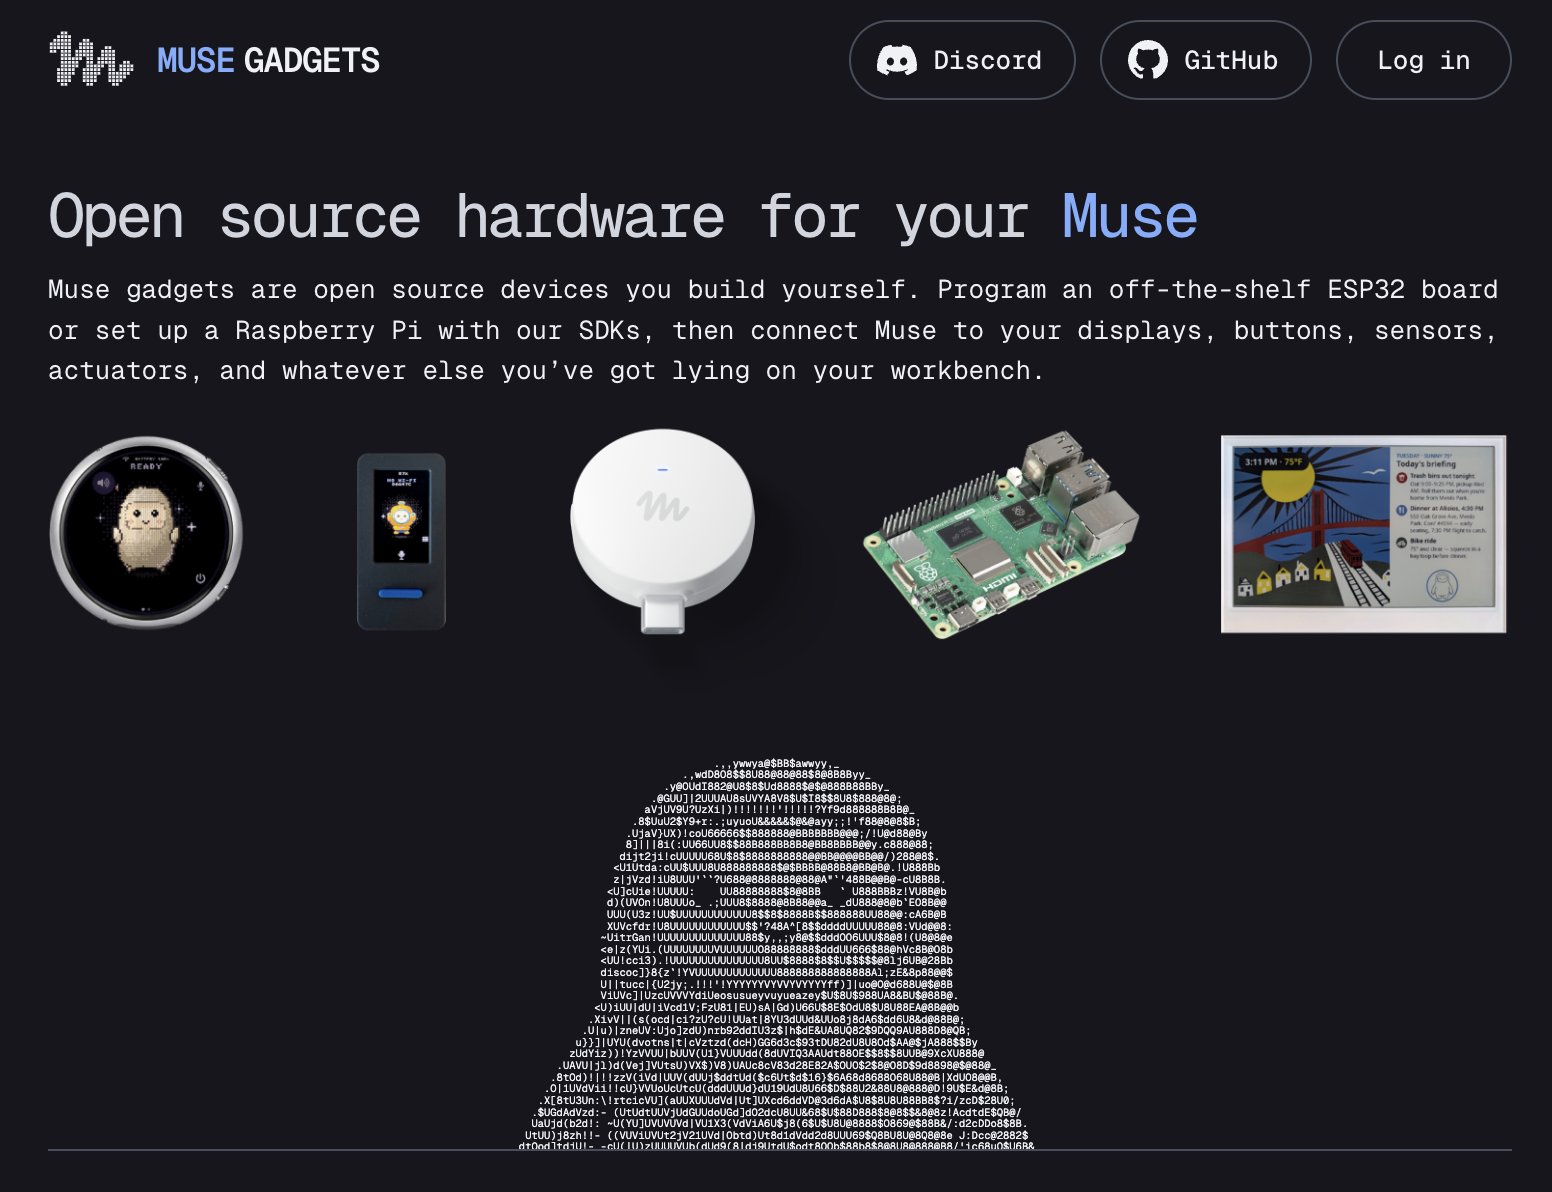
Muse is starting to really intrigue me and I was looking into this Muse Gadget Ecosystem and it looks nice. Still waiting on Muse Spark to be Open weights. Mark did say it would happen.

🚨 MUSE ECOSYSTEM ALERT 🚨
today we are announcing Muse Gadgets!
this is an open-source ESP32 firmware and Linux SDK for anyone to make hardware that works with Muse
we are also releasing our own gadget—Muse Home Link—to enable your muse to work with your smart devices (TV, speakers, etc.)
1
5
815
Buying 4 DGX Sparks was a INVESTMENT... A pretty HUGE one. But the way these prices are moving I feel like I dodged a bullet. GLM 5.3 Flash on 4 x DGX Sparks is very fast, I think I will thank my past self alot in the future.
10
2
88
7,457


I said what I had to say at the end of the day. I won’t let the drama continue into thr upcoming week. None of this is going to change anything and the person has such a mass following people won’t care. That said I’ve publicly stated how I felt about them so that no one can ask moving forward “why haven’t you two collabed or worked together”. On to the next.
4
45
2,900
The Audacity Mia had to tell people to kick @ViC305 out of a LOCAL AI group accusing him of stealing “her” recipes to find out Mia been doing the same thing 😂

When a huge account like @TheAhmadOsman shares his opinions on this topic it’s extremely important that the open source community listens and most importantly learns. Someone with this type of following and wisdom in the local inference realm wouldn’t be saying this for no reason or for clout which he already has. There are rules and methods in open source work that keep it all HONEST.
There’s a reason why it’s called OPEN.
Misleading others for personal financial gain by uploading your own copy of a model to your own account and calling it an upstream is deceitful and preys on the original works of others. The most insane part about this is HuggingFace charges both accounts for storage, so this “upstream” excuse costs money to host when a simple link to the original weights is much more cost effective and truthful. Then to top it off they continue pushing their books and subscriptions under all of this deceit.
Thank you for your honest work @TheAhmadOsman and your dedication to this craft.
Thank you to @Blackwellboy for putting yourself out there on this subject.
Thank you to @Blackfrost_AI for the amazing work on the CyberFrost model.
6
51
2,841

Tech2Wild retweeted

Normalize calling people out when they’re doing shady stuff (stealing others work and efforts to name a few)
Then this person had the audacity to say “Do better, Ahmad” when I called them out on it
Opensource runs on trust PERIOD


They built a 37K cult using a fake avatar to hijack the algorithm. Code never lies and who is actually behind it is revealed inside.
Model credit: @ViC305 & @Blackfrost_ai (not participants).
Read the receipts behind Mia’s AI Lab 👇

35
18
319
28,344
I Guess Qwen 4 35B a3B is not happening. The last time Qwen dropped a 35B A3B MoE was back in April.


It looks like the small MoE isn't coming... i'm very frustrated after today, to say the least.
even more potentially wack news relating to en-grams that i'm waiting for more word on, too.
sigh, I wish I could say I understand. the model is there, man. there's no benefit to this
18
3
86
5,443
I see @MiaAI_lab UNFOLLOWED me. I didn't say nothing about "her" or about the situated that happened today. I've caught Mia copying from my REPOs with no Credit I've NEVER said anything about it publicly. But with the way this person is moving now I see I gotta pay attention.

27
10
220
26,867
Spooky Season with AI is here !
Episode 1 - Sam and Dario were having a nice quiet movie night. Until 🥘🐈⬛💀☠️👻🪦🎃

1
6
1,100
I've BACK @NVIDIAAI and @nvidia @NVIDIARTXSpark and this could make then NOT want to ever work with me lol. But come on guys did the PR team not tell you how silly this looks ? This makes no sense whatsoever.

3
3
30
4,791
NO WONDER SPARK PRICES JUMPED UP!
NVIDIA really said "more ways to build local AI" and priced 64GB at $4,999. The 128GB Spark launched at $3,999. Half the memory, a grand more. The RAM shortage is eating AI hardware alive.

DGX Spark is getting a 64GB option.⚡
With the GB10 Grace Blackwell Superchip, DGX Spark 64GB runs capable local agents on device and works with our new NVIDIA Sync Cluster Assistant to seamlessly pair systems for larger workloads.

13
7
35
4,353


This is crazy man. We are living in historical times.

Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Community note
The 48% figure and "video Turing test" claim are from Tavus's own study of 54 one-minute calls, not independently verified or using a standard protocol. Griffin-Lite leads NVIDIA's VideoFDB benchmark on their public leaderboard.
cellcog.ai/blog/tavus-gri…
research.nvidia.com/labs/amri/proj…
tech-ish.com/2026/10/02/tav…
1
1
9
2,935
Oh needs as humans are not moving faster than the models themselves hence why a GLM 5.3 Flash is able to do the work majority of people need. I can only image the models we will have in the Summer of 2027

Timelines just got shorter...
AI will understand the physical 3D space better than humans by November*

1
9
1,423
"20% of the performance" measured how ? Six months ago Opus 4.6 was THE flagship and nobody called using it snake oil. Our needs don't grow as fast as the models do. For 90% of real-world AI work, GLM handles it just fine. That's not a lie, that's called matching the tool to the job.

I'm all for open source, but I hate when people lie and claim a model like GLM-5.3 Flash can replace flagships like Opus 5.5 and Fable.
That's just selling snake oil.
Those models won't even give you 20% of the performance.
8
2
97
5,543