

Evals Evals Evals - evals.info About Me: hamel.dev
Looking at the data
- Tweets 17,609
- Following 2,685
- Followers 58,185
- Likes 19,285


Pinned Tweet

This is the most valuable free resource we've created on AI Evals 🎉 (not exaggerating!)
I organized our public materials into this guide. It allows you to find answers to your eval problems w/o searching aimlessly.
Humans: pick the row that sounds like you.
Agents: point it at the post
The material draw on 60+ hours of office hours from our Evals course, where @sh_reya and I have taught 5k engineers and PMs Evals.
We add new material often, with 15 FAQs added in the last two weeks. Recent additions are marked with a "New" badge. You can find all of these and more here:
hamel.dev/blog/posts/evals-f…

61
109
965
79,371
Hamel Husain retweeted

One of the biggest requests we get is “how do I prepare for an applied AI evals interview?” No better person to give this talk than Hamel. I have heard this talk and it’s fantastic. Free and available to all

Last open lesson of the year! How to crack the AI Evals Interview!
AI Evals are now a part of an increasing number of AI job postings, and you're now more likely to encounter them in interviews.
I've helped design quite a few evals interviews, so I know what kinds of traps exist, along with nuanced things companies tend to look for. I'll discuss this, as well as how to structure a take home or report to help you think through the problem clearly.
Tuesday Oct 6, 8:30am PT. This one assumes some basic evals knowledge. Read this first if you're new to the topic to get the most out of the session: hamel.dev/evals-faq
Sign up here: maven.com/p/07e7c7

5
18
208
25,413
I cannot understand this demo video at all. Sadly, it’s visual slop 😭
Not trying to disrespect anyone maybe the feature is cool it’s just what happened to demos humans can understand

You can now mod Claude Code:
- Change how it behaves
- Customize the UI
- Swap in your own features
Write one with a few lines of TypeScript, or have Claude build it for you. Mods ship inside plugins, so you install them with /plugin in the CLI or desktop app.
A few examples:

36
3
217
26,746
Hamel Husain retweeted
Last open lesson of the year! How to crack the AI Evals Interview!
AI Evals are now a part of an increasing number of AI job postings, and you're now more likely to encounter them in interviews.
I've helped design quite a few evals interviews, so I know what kinds of traps exist, along with nuanced things companies tend to look for. I'll discuss this, as well as how to structure a take home or report to help you think through the problem clearly.
Tuesday Oct 6, 8:30am PT. This one assumes some basic evals knowledge. Read this first if you're new to the topic to get the most out of the session: hamel.dev/evals-faq
Sign up here: maven.com/p/07e7c7
8
14
170
34,684
Hamel Husain retweeted

🚨 MAJOR ANNOUNCEMENT: YouTube will start prioritizing original content and reducing re-uploads (RIP clipping)
YouTube has just announced one of the most impactful changes to its short-form algorithm. Its recommendation systems (the algorithm) will start to further prioritize original content and reduce the reach of content re-uploaded from other creators without adding anything of your own.
They highlight this shift toward originality, where channels with primarily re-uploaded content will see less distribution within the Shorts feed.
It also seems like they’re really trying to put the focus on content with real value, while highlighting that YouTube doesn’t want as many “minor technical edits” or “template-based” changes. Which is basically all that clipping was in this industry.
Overall, while this will piss off some people whose entire careers were built on the premise of other people’s content (mostly clippers), the change itself is amazing and will finally address the overall quality issue we’ve been seeing.

512
670
6,851
2,192,774
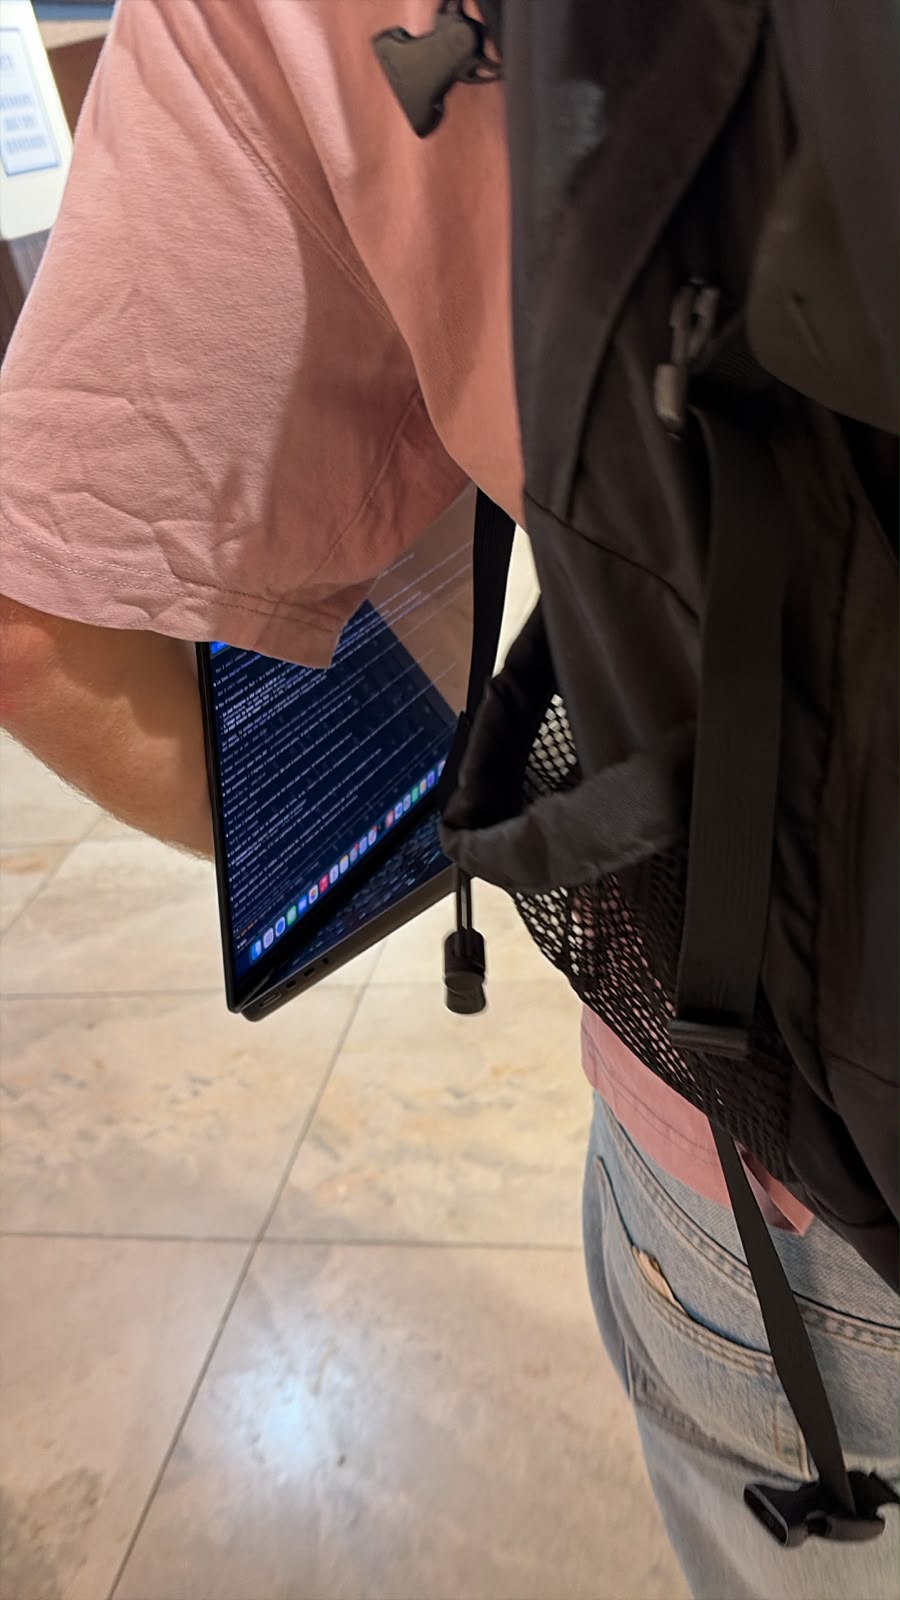
When I see this it confuses me. ssh into a computer for god sakes, or use codex remote feature w/ mac mini.
Once you have been stuck in "i need to keep my laptop open" more than 3 times, its crazy to keep this insanity going.


129
15
865
97,704

Q: Why do you recommend binary (pass/fail) evaluations instead of 1-5 ratings (Likert scales)?
A: Binary labels force clearer thinking and more consistent labeling, and involves significantly lower complexity to operationalize.
hamel.dev/blog/posts/evals-f…

27
10
94
5,862
Hamel Husain retweeted

LLM bots are talking in my replies, this site is having a real problem blocking these accounts. Confusingly, a lot of these bots have a blue check
Amusing but also depressing

77
9
368
24,067


Hamel Husain retweeted
Really bullish on workload-aware inference! Database systems are of course a crown jewel of exploiting workload knowledge to achieve good performance. now in today's inference era, any system with a declarative interface and budding demand for LLM inference is probably a good candidate for workload-aware inference

Yep! A batch data processing pipeline usually has several LLM operations, and the API approach makes one call per row per operation, with each call served independently. If you know all the requests up front, you can plan the whole job, like reordering requests within an operation to share KV cache, running the most selective filter first, and reusing each document's KV cache across operations. Also beyond planning, you also want to change execution — eg if you know which requests in a batch share a prefix, you can use different attention kernels that read the shared KV from HBM once, instead of once per request
12
6
81
9,633
Hamel Husain retweeted
Have you tried to use a decision model (like Jev) on thousands of rows? Calling an API once per row is a terrible idea for batch work, because it gets no benefit from query planning and sits *extremely* far from optimal performance.
With Qwen3-4B on one H100, the speed-of-light (SoL) for one AI filter over 5k movie reviews, or the fastest the GPU could possibly run it, is about...6.6 seconds! No system today comes close, including Quail, our open-source AI-SQL engine 😱
New blog post on how we cost AI-powered filters in Quail (based on SoL estimates), check it out! fsdatalab.github.io/blog/ai-…
24
21
191
15,381
Q: Should I build automated evaluators for every failure mode I find?
A: No. Different types of evaluators have different costs (code vs. LLM judge), which you need to weigh before building an eval.
hamel.dev/blog/posts/evals-f…

25
8
44
4,174
🥰🙏

thanks @HamelHusain + @isaac_flath! the latest skill does instruct Claude to build a viewer for eval examples. but as you said, it *doesn't* walk the user through the data first. i agree that this can help the user prioritize which evals to write. i'm going to add this. thanks for taking the time to review!
4
23
6,431
People keep asking about this new Auto Eval plugin for Claude this so I wrote a longer post reviewing it.
Would love to hear what other people think! If you used it how did it go?
Full writeup here: hamel.dev/blog/posts/claude-…


Claude can now help you build evaluations and hillclimb on them.
In this article, we share guidance on eval design & skills that Claude Code can use to improve your applications.
claude.dev/blog/automating-e…
43
29
294
39,913

Q: How can I efficiently sample production traces for review?
A: Start with broad exploration, then use signals to find likely failures. Keep some random traces in every batch so you can discover new problems.
hamel.dev/blog/posts/evals-f…

16
6
55
4,270

