

Pre-training lead at World Labs. Atlas project lead (worldlabs.ai). Opinions are my own.
San Francisco, CA
- Tweets 251
- Following 776
- Followers 3,554
- Likes 830


Pinned Tweet

Atlas is live! A spatial foundation model, trained in-house from scratch.
After shipping RTFM last year, I was convinced a single camera-conditioned model could unify most spatial generation tasks. Atlas is that bet at scale.
The core idea👇

Introducing Atlas:
The world's first multimodal world model that generates image and video frames with pixel-perfect camera control and reconstructs them in 3D.
Model the world, move the camera, and simulate space & time.

4
16
180
61,777
Fantastic job @HaoZhang623 !

World Tracing is a NeurIPS 2026 Spotlight! 🎉 It’s also our first NeurIPS paper at World Labs. Grateful to everyone who worked on it with me. @jcjohnss @BenMildenhall @_mbanani @KeunhongP @AndyCheng_JH @pzpzpzp1 @Hawaii271828 @chlassner @gengshanY
And there’s more to come: World Tracing Pro, with code and enhanced checkpoints, is on the way 👀
arxiv.org/abs/2606.13652
haoz19.github.io/world-traci…
14
2,477


Keunhong Park retweeted

Introducing PointZero—a 3D world model pre-trained without robots.
Dexterous manipulation requires understanding diverse 3D dynamics, but current approaches rely on expensive robot data. So how can we pre-train a 3D dynamics model without it?
PointZero introduces a simple idea: learning to complete 3D point tracks yields transferable 3D dynamics!
Our model achieves SOTA results on:
🔥 Zero-shot 3D dynamics
🔥 Action-conditioned 3D dynamics (post-training)
🔥 Imitation learning (post-training)
Details and links 👇 1/6

8
45
256
28,490
Keunhong Park retweeted

We’re excited to share that @nuance_ai has raised a $50M Series A led by @lightspeedvp, joined by @Accel, @spc, @nvidia, and @definevc!
Much of human communication happens beyond words. Before we can speak, we learn to read faces, return smiles, follow gestures, and sense when someone is listening. That visual and emotional vocabulary stays with us for life.
At Nuance Labs, we’re building a foundation model that understands and responds to the full spectrum of human emotion. A single full-duplex audio-visual model that sees, listens, and responds in real time, with the natural give-and-take of a conversation with a friend or colleague.
We believe the best interface with a machine is the one we’ve practiced since birth.
Join us!

75
85
632
2,006,488
Keunhong Park retweeted

An insightful study from @tongzhou_mu and the @RhodaAI team that examines how web video pre-training translates to robot performance.
The gist: pre-training doesn’t just help; it scales, i.e. you can continue to reap greater benefits as you put more effort into pre-training. A better pre-trained model will lead to a more robust policy.
But how you achieve that pre-training quality is up to you! Whether by scaling the model, or scaling your training tokens, it’s a design choice informed by your compute constraints, training budget, and how much you care about compute optimality.

Does scaling pre-training on general web video improve a complex manipulation task in real deployment?
We scale model size and pre-training compute, and test on one industrial task.
Yes. The better a pre-trained model predicts web video, the better its post-trained policy. 🧵

ALT Seven pre-trained video-model checkpoints on one chart. Task performance on a real robot (at-speed completion rate: every requirement met within 100 s, 0 to 100%) rises with pre-training quality (DINO FD on held-out web video, log scale, axis reversed so better is to the right). XS, S, M, L are model sizes. The four M points are one model at 0.08×, 0.18×, 0.37× and 1× of its pre-training compute.
2
19
1,226
Keunhong Park retweeted

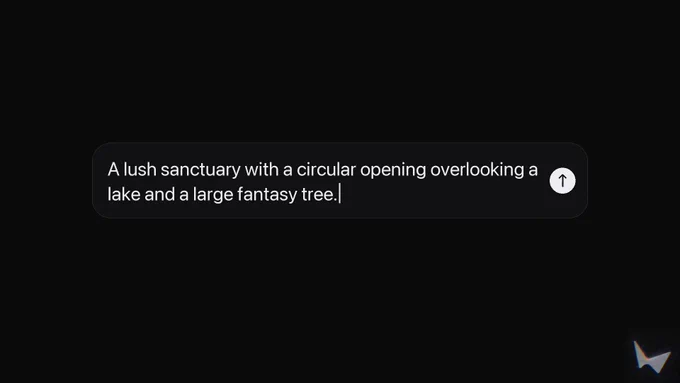
My favorite use of Atlas is interactive world building / editing. To experiment with this, I hacked frameboy advance to let me supply text prompts on the fly. Atlas’s strong reconstruction and generative capabilities make this a unique experience.
You can start from scratch with just a text prompt or from an existing world by loading its views into Atlas’s spatial context, then shape the world while you are flying around in it.
The best part is that you can share the resulting worlds between different Atlas sessions simply by loading their views into the model’s spatial context.

3
4
36
2,129
When we started World Labs in early 2024, one of the things I missed most from Google was the infrastructure (XManager, Colossus, Borg). In 2026, I don't miss it anymore. Our platform team built tooling that rivals it. Large frontier models like Atlas are difficult to train, but our infrastructure makes it feel easy.
Big appreciation to our infra titans: @DanielChao4, @jonedsarwar, Raghav Garg, @mukesh_hira, Yufeng Zhou, Dichen Li, Eunjae Kim.

2
4
97
7,971
Our platform team is looking for a performance engineer: jobs.ashbyhq.com/worldlabs/2…
Read more about atlas: worldlabs.ai/blog/atlas
5
343
Keunhong Park retweeted
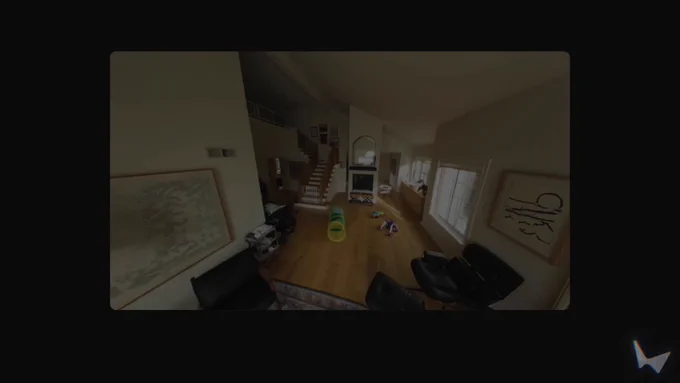
To explore large spaces like this, while keeping them consistent is afaik not really possible with any other technique yet.
This is the power of deep learning. We just put (real or generated) images into Atlas' context window and let it rip. There is no explicit 3D representation, all the interesting computations happen within Atlas forward pass(es).
Atlas-turbo predicts new views that are 3D consistent with its previous context and correspond to whatever camera the frameboy advance requires.
In the attached frameboy advance recording I put 48 real views and some Atlas generated anchors in positions where Atlas-turbo was the most uncertain.

Atlas maintains 3D consistency during generation by building up a spatial context of inputs and previously generated frames.
You can explore reconstructions of real-world scenes by adding real-world images to the spatial context.
5
2
45
4,096
Almost a year after the Frameboy, @wendlerch and @_nikunj_gupta bring us Frameboy Advance!
Atlas is an autoregressive model that generates frames one at a time. We have optimized a version of Atlas that generates in real-time, allowing you to interactively explore worlds that are generated on-the-fly.
1
23
1,827


When we say Atlas has pixel-perfect camera control, we mean it.
Atlas precisely follows input camera parameters, including non-planar projections such as the Brown-Conrady distortion model and the Kannala-Brandt fish-eye model.
@BhamidipatiPan1 invented a novel method of camera conditioning and it works beautifully.
🧵 [1/N]

15
99
826
93,340


Read more about Atlas: worldlabs.ai/blog/atlas
Request early access: form.typeform.com/to/zHFR4r3…
1
1
32
2,381