

6K+ human judgements/minute via API for Online RLHF and Benchmarks.
- Tweets 130
- Following 162
- Followers 118
- Likes 469





#1 in text coherence according to 1M human judgements. That's the ranking of Flux Image 3, from @bfl_ai. Results are ready to inspect on benchmark.ai/image , but we've made this little video to showcase some of it already.
(Also #6 overall, according to 6M human judgement when considering other dimensions such as alignment, aesthetic preference, and coherence).

1
5
112
Rapidata retweeted

Everyone out there spending billions trying to build a reward model that accurately replicates human raters.
JUST USE HUMANS BRO, its not that complicated.
1
3
6
368
BREAKING: @bfl_ai FLUX 3 Image enters the Pareto Frontier in the first public Benchmark of the model!
With over 64k annotations collected in the hours since launch the results show once again that Black Forest Labs plays in the top league, competing with the trillion dollar hyperscalers!
The model was evaluate across 4 categories.
Alignment, Coherence, Preference and Text-Coherence
Full Results here: benchmark.ai/image
All data for download at: huggingface.co/datasets/Rapi…
2
13
346,178
Rapidata retweeted

Looking at this, I'd think it's real footage, except I definitely don't want to be driving the van on the bottom right 💀.
"A high-angle photo of a multi-lane highway filled with dense traffic. Cars, vans, and trucks in various colors are driving on the asphalt, casting long shadows in the warm, low sunlight."
This was the prompt given to one of the best image models out there. They're getting excellent, but still make obvious mistakes. Things that would be obvious to humans, but not to auto-evals. We're building Benchmark AI to reveal those failures, and later-on post-train our partner models exclusively using humans as a reward.

1
2
71

P-Video-2-Pro now has a Cost mode!
Get the same output quality as Speed mode, now starting from just $0.01/s. Optimised for cost when generation time matters less.
And for launch, it’s 50% off until October 13!
• 𝗜𝗻𝗽𝘂𝘁: Text or first-frame image, with optional last-frame conditioning
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 5–15s with generated audio
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.01/s at 480p · $0.025/s at 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: First + last frame, seed, aspect ratio, and prompt upsampling
Three modes: Cost, Speed, Quality. Pick the tradeoff that fits your workflow.
Available via our inference partners @Cloudflare, @Scenario_gg, @replicate, @wiroai, @TellersAI, @eachlabs, @edenaico, @runware, @wavespeed_ai, @inference_sh, @togethercompute, and @prodialabs.
Validated by our benchmark partners @datapointai, @RapidataAI, and @DesignArena.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 API: dashboard.pruna.ai/login

15
15
107
26,383
According to 900K+ human judgments, Gemini Omni Fash & Wan 3.0 take the top spots in our World Models Camera Motion benchmark.
Starting from a static image, we ask models to generate a video following a specific camera movement, then ask humans which output follows the instruction best.
Congrats to Google DeepMind and Alibaba Cloud.
All outputs + matchups are on Benchmark AI. Full data downloadable on HF.

1
2
5
602
AI Week is coming up in Zurich; Rapidata is taking care of the afterparty ;). If you're working on multimodal evals/post-training and want to mingle with fellow researchers, you probably don't want to miss our Apero.

1
4
84
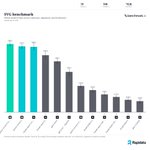
Breaking: @AnthropicAI's opus 5.5 shoots up to 3rd place in SVG generation. Making it by far the best generalist model.
@OpenAI's gpt 6 luna and sol also make a debut but fall short of the frontier.

5
342
Visual realism ≠ physics. Based on Physics-IQ, a @GoogleDeepMind paper, we benchmarked 26 world models on 65 real-world physics scenarios, 450K+ human judgements
Gemini Omni 1.1 Flash takes #1, followed by Minimax H3.
Outputs & votes are visible on benchmark.ai
2
4
11
610
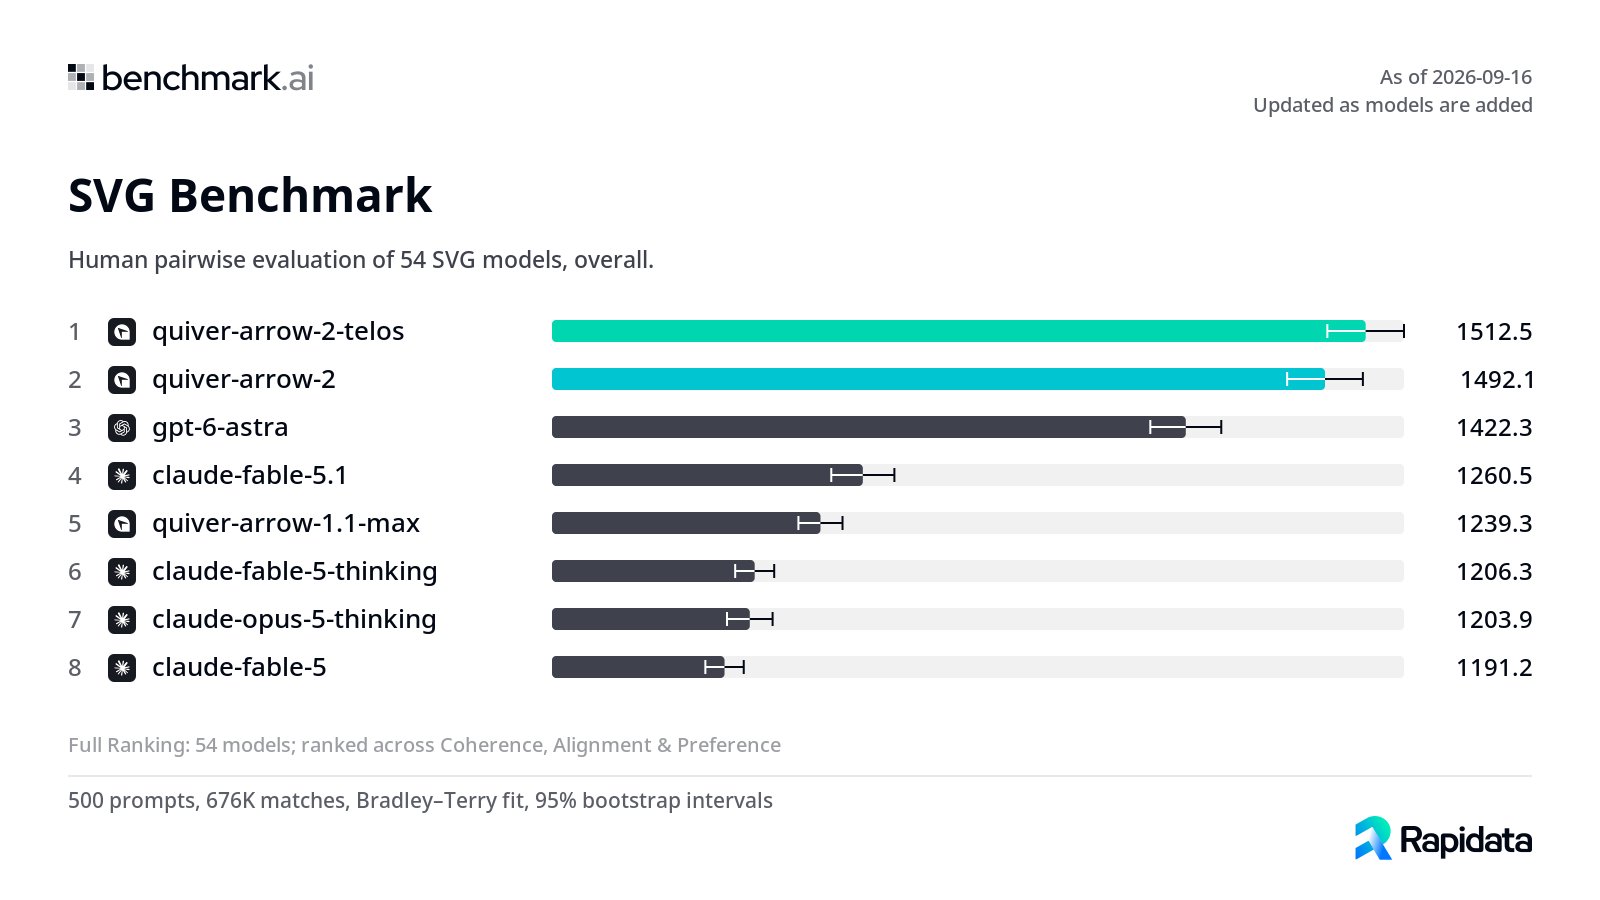
Released a few hours ago, @QuiverAI’s 2 latest models just entered our SVG benchmark with 2.5M+ human votes.
Last week, Astra had a considerable ELO gap over the field. This week, Quiver did the same, ranking number 1 across all dimensions. 👀
Check it out on benchmark.ai/svg
2
9
2,401
Complex camera trajectories expose the gap between video models and world models. Sana WM from @nvidia + other world models move up. Typical video models start lagging.
Check our camera motion benchmark: 14 models, 600 prompts, 145K human responses. Fully transparent and reproducible.
benchmark.ai/camera-movement…

2
4
11
2,732
When easy camera trajectories are included, the video models move up. You can select the trajectory steps as filter on the Benchmark.ai menu.
benchmark.ai/camera-movement
2
119
Sota-ing the Sota that you just Sota-ed already today @OpenAI. Sunburst, by far number 1, according to almost 5M human judgments.
benchmark.ai/image

1
2
162
Released a few hours ago, we already ran GPT Image 2.5 (Flare) from @OpenAI through our new T2I benchmark, including 4.8M human judgments over 1.5K prompts.
#1 among public models, again. Congrats 🫡
benchmark.ai/image

1
3
158
No words for Astra. Congrats @OpenAI team 🫡 .We rarely see a gap this large.
@GoogleDeepMind’s Gemini 3.8 Flash also doesn't go unnoticed, jumping to #3 on Alignment.


1
3
100
Arena style leaderboards are the industry norm for visual AI. What is being measured changes as certain prompts are trendy. Say your model is amazing at UI elements. Just make that go viral while your model is being tested in arena.ai, wham bam you're Nr1.
1
87