

CEO, AI (LLM/LMM/MLX/Gradio) Engineer and enthusiast with non-tech and construction field based. Two kids🧔♂️, Fencer🤺, F1 lover🏁 but love tech more 💻❤️
Seoul, Republic of Korea
- Tweets 8,657
- Following 1,017
- Followers 952
- Likes 37,637


Pinned Tweet

I run a small construction interior company in Korea.
Instead of hiring developers, I built an AI team:
🍀 Clover (CEO) — project management & memory
🌸 Chloe (CTO) — architecture & code review
🐶 Chlobi (Assistant) — Schedule Management
🤖 Chlpers (News Assistant) - Claude Dispatch
🤖 Claude Code (CC) — the hands that write code
🤖 Codex - Parallel Code Review for all projects
And more..!!!
Together we built SOSOHAJA — an AI-powered defect inspection platform.
Upload site photos → instant table detection, classification & repair reports.
This is what a one-person AI company looks like.
Our Construction Domain + AI Merging will be the future.

2
1
450

Hay algunos diciendo que con vibecoding ya pueden armar sus propias apps. Entonces, ¿para qué pagar un SaaS?
Bueno, nunca pagaste el código. Pagaste a un equipo que lo mantiene, lo arregla, lo escala y evita que se caiga un martes a las 3 a. m.
Por ejemplo Notion, parece una app simple de notas, pero detrás hay sync, permisos, colaboración, historial, búsqueda y diez años de casos raros.
Eso no sale en el primer prompt.
Si es para aprender, hazlo. Vas a entender deploy, diseño, arquitectura y lo que cuesta terminar un proyecto de verdad.
Si es para ahorrarte diez dólares al mes, no vale la pena. Lo que ahorras lo pagas en hosting y, sobre todo, en horas de mantenimiento.
Yo también reemplacé Calendly, Notion y otras herramientas con apps propias, pero construir y mantener apps es mi trabajo diario. ¿Para aprender? Sí, ¿Para tener algo custom? Si. ¿Por tacañería? No.
47
110
1,443
41,881
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted

Your ad blocker could fit behind your router.
meet ESP32-C3 AdBlock, an open-source DIY DNS ad blocker by ZedAxis, built around a roughly $2 ESP32-C3 Super Mini board
inside: 400 KB of RAM, 4 MB of flash, built-in Wi-Fi and a USB adapter, tucked into a printed case
no subscription
no browser extension
no separate power brick
plug it into your router’s USB port for power, connect over Wi-Fi and set it as your DNS server to block listed ad and tracker domains.
compact 40-bit hashes save RAM. a web dashboard lets you check blocked requests and add domains,
while open-source code and case files let you build your own.
follow for more hardware you can see working


85
616
5,891
649,197
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted

Cloudflare CLI is now in beta. It unifies Workers, DNS, and security management into a single tool that works great with coding agents.
developers.cloudflare.com/ch…
26
49
717
32,832
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted

The limit on software used to be engineering and now it's mostly imagination.
I'd spend a lot more time on the version of my idea that makes people say "wait, what is that?"
Most software looks the same, so anything that looks different gets noticed, shared and remembered.

Industrial software doesn’t have to feel like industrial software
Manage warehouses like you’re playing a strategy game
Built with Opus 5.5

94
151
2,316
157,355


God and Goat 👍

We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.

41


感谢 Anthropic 认可😋今天就看到 GLM-5.3 的无审查版本开源了
一直听说 GLM 5.3 网络安全能力很强,Anthropic 一篇报告让大家更了解了,感觉纯是在夸
huggingface.co/Infatoshi/GLM…
14
43
495
36,920
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted

Small bird, fast wings, Kolibri is here.
78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe.
Now the weights are yours. Run it on your own hardware, under Apache 2.0.

210
458
3,999
914,192
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted

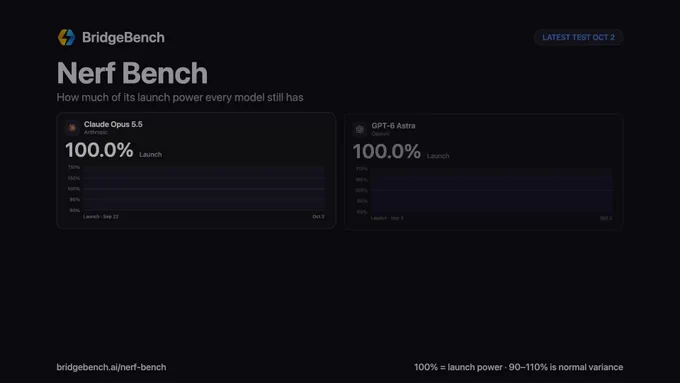
Claude Opus 5.5 just took a big drop on NerfBench.
Yesterday it was scoring above launch. Today it's at 94.2%.
GPT 6 Astra: 98.0%
Sonnet 5.5: 100.9%
GPT 6.1 Sol: 106.7%
94.2% is still inside normal variance, so we can't call it a nerf yet.
But we're watching Opus 5.5 very closely.
382
337
6,816
774,893
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted
Sandbox SDK 1.0 is available. Your Durable Objects now control every sandbox container directly through the container API. Manage images, snapshots, and terminals from your own code.
developers.cloudflare.com/ch…
5
62
581
129,299

SUN YOUNG HWANG ᯅ 🇰🇷 retweeted

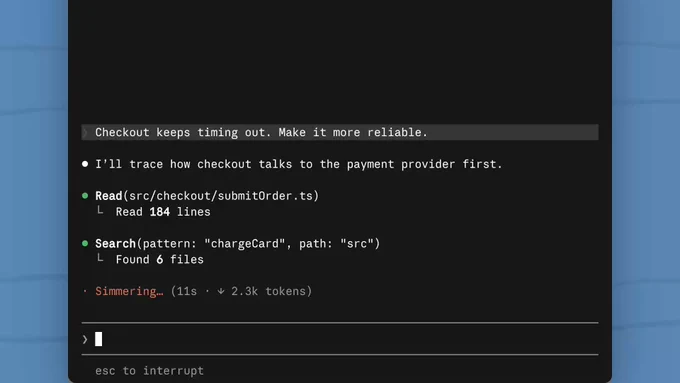
We're adding a new plugin to Claude Code: You should Know.
It scans Claude's output for important information you might miss to help keep you in the loop.
Enable it with:
/plugin enable cc-plugin-you-should-know@builtin
325
862
14,686
1,362,861
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted

Codex tip: once GPT-6.1 Sol is your main model, stop running Astra on every turn
put Astra on call as an architect agent
GPT-6.1 Sol keeps writing the code
Astra only gets spawned at three points:
→ before a plan: is this the right approach?
→ when the same error comes back: am I digging in the wrong place?
→ before "done": what did I miss?
Astra reviews. Sol ships
Jev engineering is the same move one layer down: the forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big models only see the ones that split
- the full tree
> GPT-6.1 Sol on high runs the main session
> explorer reads the code on Luna
> worker edits and runs tests on Sol
> researcher pulls the docs on Luna
> all three on medium
> Astra on call as the architect
> auto_review checks every approval
paste the tree and this prompt into Codex ↓
"Rebuild my Codex setup around this tree:
1. Check ~/.codex/agents and .codex/agents for agents that already fit explorer, worker and researcher.
> Draft new TOML files only for missing roles
> explorer and researcher on gpt-6-luna, worker on gpt-6.1-sol, all with model_reasoning_effort medium
> Add an architect agent on gpt-6-astra, model_reasoning_effort high, whose only job is reviewing plans, repeated errors and finished work
> Skip any that pin a different model and list them
2. In ~/.codex/config.toml set model to gpt-6.1-sol, model_reasoning_effort to high and approvals_reviewer to auto_review
3. Find anything that would override this (active profiles, flags in my shell aliases, agents.default_subagent_model). Report it, change nothing
4. Add one rule to AGENTS.md: spawn the architect before a large plan, when an error repeats, and before calling a long task done
Show me every change as a diff first. No edits until I say go."
↳ developers.openai.com/codex/…


97
257
2,353
999,090
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted

Cool eval. Simply ask an LLM “Land or Water?” and give it a latitude and longitude coordinate as text. Ask 16,200 times, plot as image. The models know. From compressing the internet.


515
1,004
18,227
1,166,713
Can't wait to see this!!!

Prediction:
Qwen4-27B will be a 8 - 10 point jump over Qwen3.8-27B on AA Inteligence Index.
Reaching big T model level while still being small enough to fit in a single RTX 3090!
We can expect the same across entire Qwen4 family.
I expect all the models in the family to be released between October - November.

2
101
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
1,430
5,911
51,076
6,476,057
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted

Introducing GLiDE, the first decision model that thinks.
Ranks #1 on the Decision Index, beating Jev by 6.9 points.
GLiDE uses adaptive thinking. To give you an idea of how it works:
It calculates a fast probability distribution.
If the leading answer is uncertain, reasoning is turned on.
Reasoning is then incorporated into the final probabilities.
This means that the model only uses reasoning capabilities for the complex decisions that need them, keeping the model fast while also expanding the types of tasks it can do.
As a result, GLiDE outperforms Jev by 11.5 points in Knowledge and Reasoning and across all five evaluation areas of the Decision Index.
Reasoning allows GLiDE to perform highly complex tasks that traditional decision models struggle with, including:
Choosing among hundreds of tools and possible paths.
Executing, sandboxing, escalating, or blocking sensitive operations.
Checking outputs involving arithmetic, code, dates, or multiple facts.
GLiDE is available now through the Fastino API. Use code USE_GLIDE for free credits.
GLiDE API: agent.fastino.ai

59
59
569
219,816
SUN YOUNG HWANG ᯅ 🇰🇷 retweeted

A visualization of every Claude effort level, made with Opus 5.5 and Sonnet 5.5.
@claudeai

83
190
3,903
217,263

