

Co-Founder of SceniX (now part of @theworldlabs) | Assistant Professor @Columbia @ColumbiaCompSci | Former postdoc @Stanford @StanfordSVL | PhD @MIT_CSAIL
New York, NY
- Tweets 600
- Following 579
- Followers 11,315
- Likes 3,316






Pinned Tweet

I am excited to share that SceniX is joining World Labs! We built SceniX to close the real-to-sim gap for robot learning. Joining forces with @drfeifei, @jcjohnss, and @BenMildenhall and the @theworldlabs team means we close that gap faster. Grateful to our team, customers, and everyone who backed this vision. More to come soon. 🌎

The world is not just made of words, and spatial intelligence was never just about perceiving and generating worlds. It's about interacting with them.
Today, SceniX is joining World Labs. 🌎🤖👇

64
22
415
52,170
Yunzhu Li retweeted

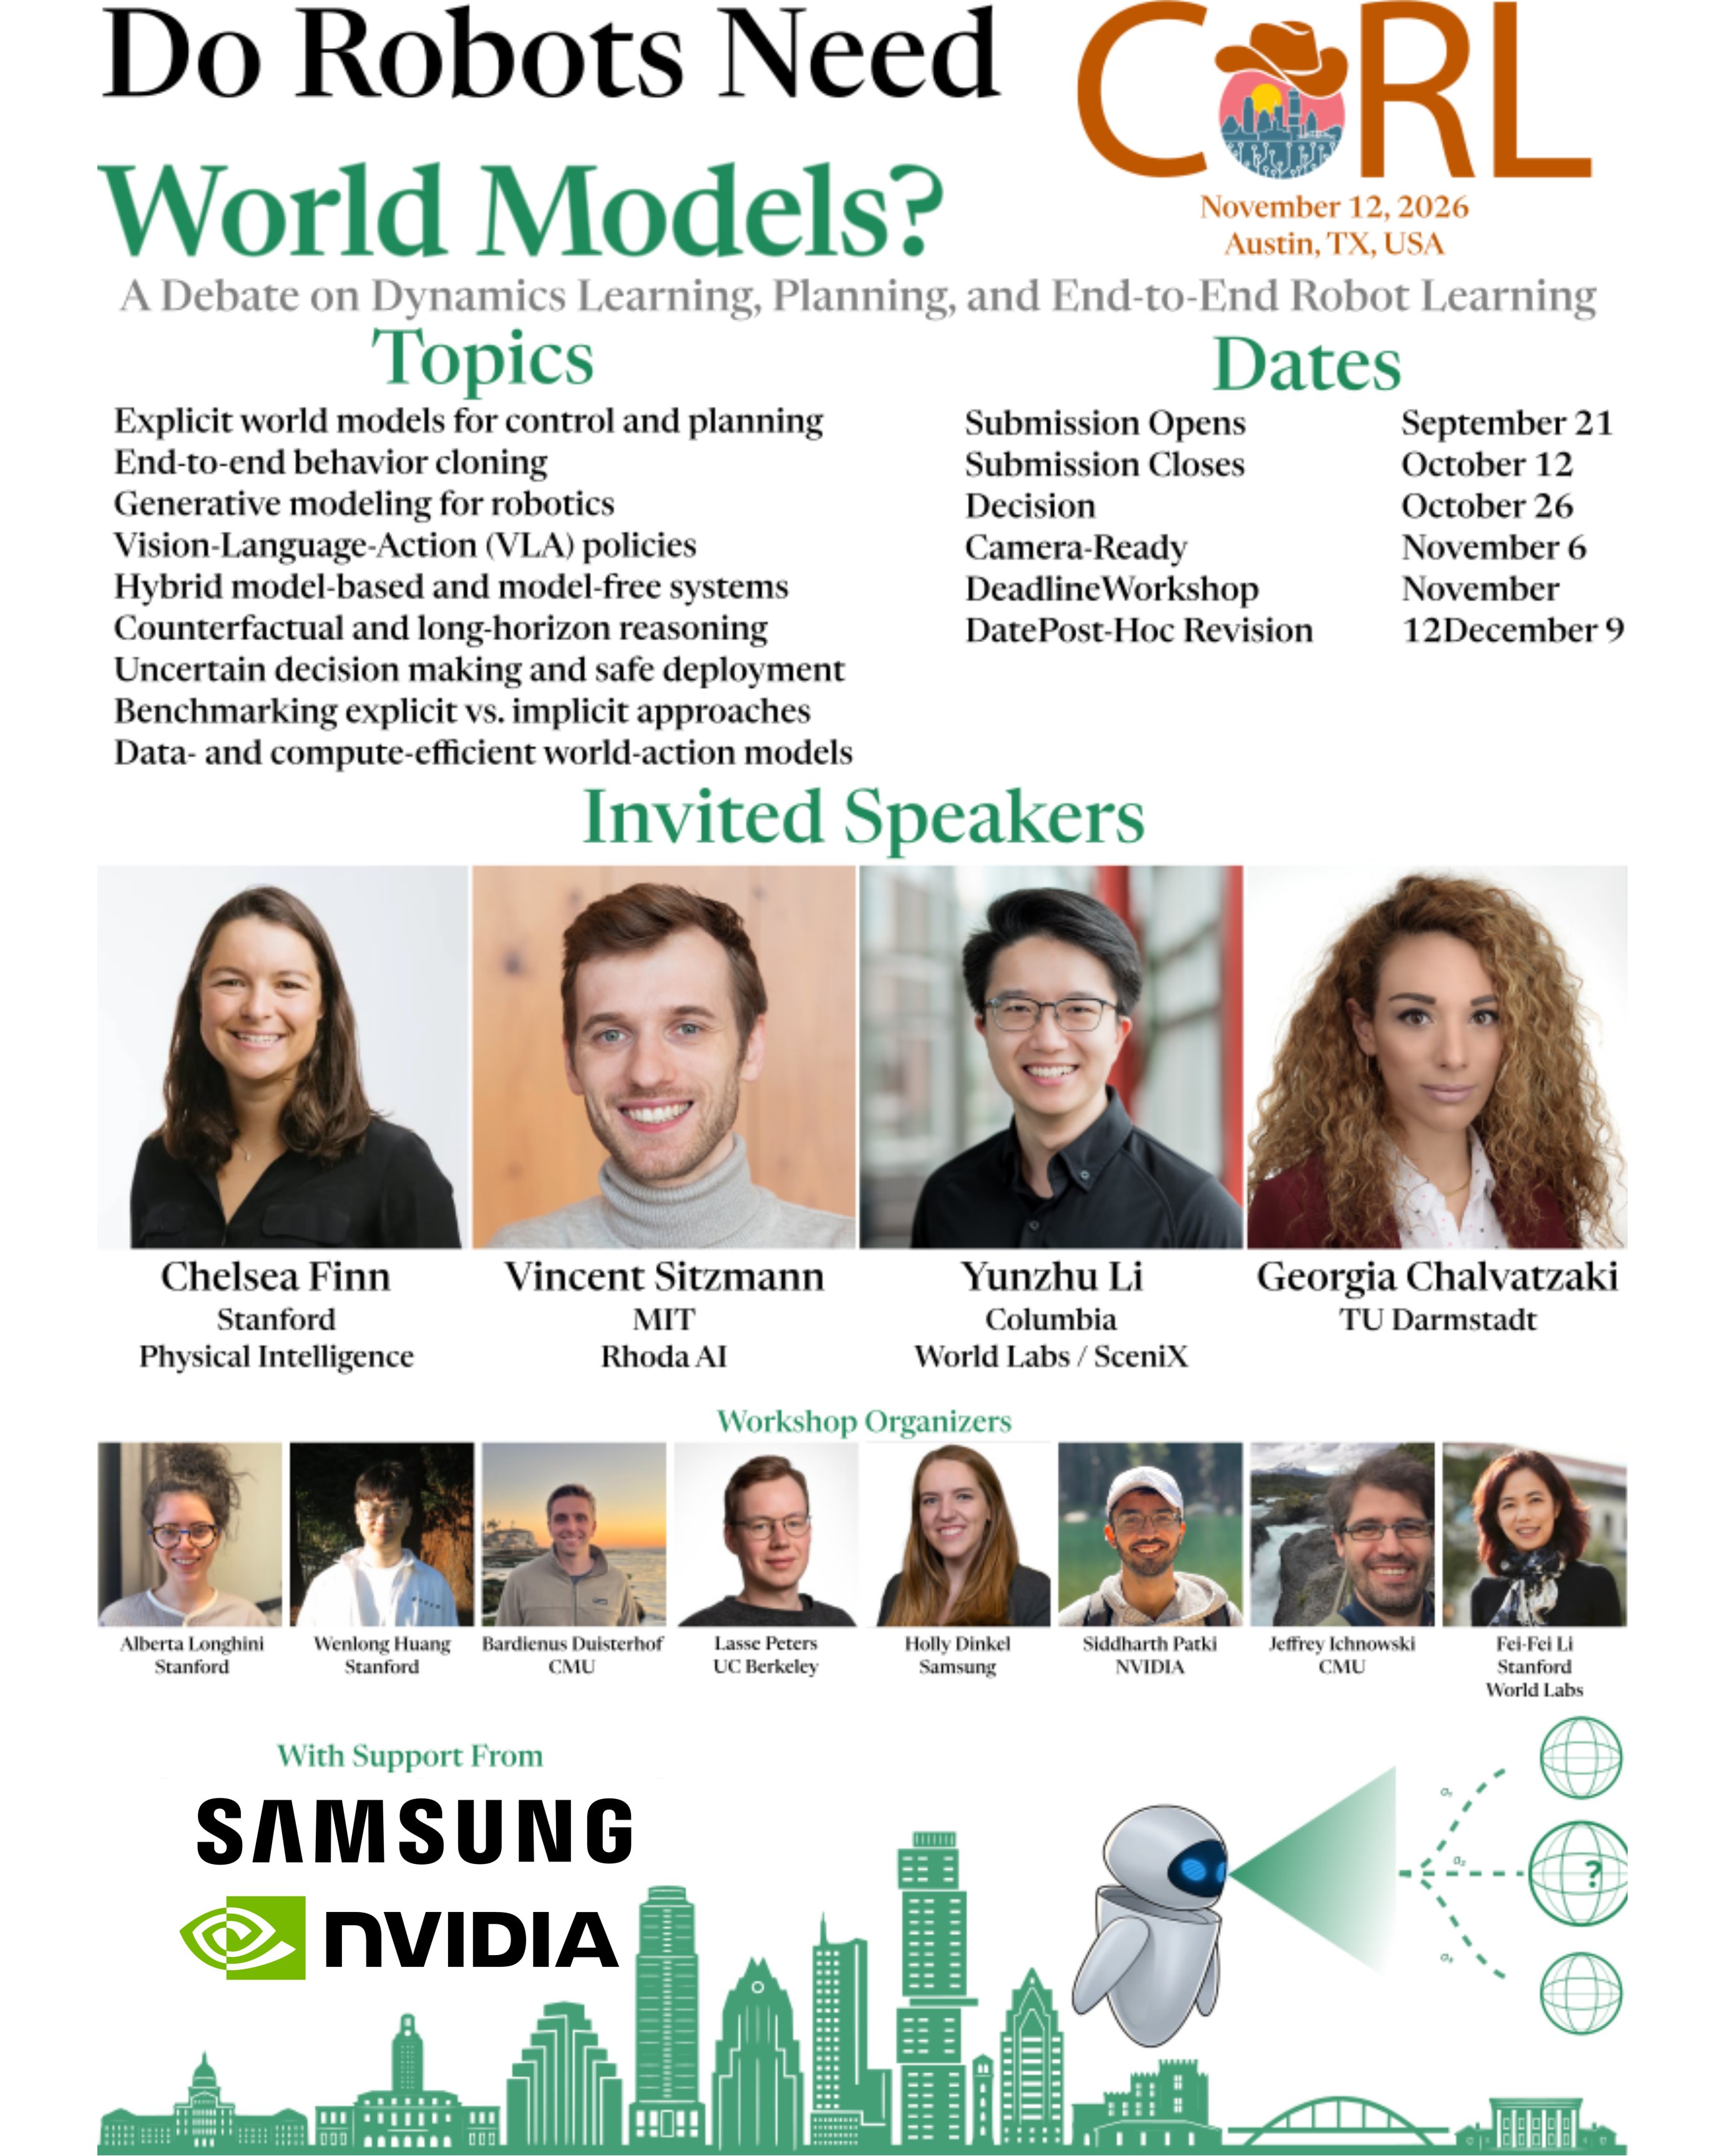
The hottest debate of the year: do robots need 🌎 world models 🌎?
Join us at CoRL 2026 for a scientific debate on the case for — and against — world models for robotics, featuring @chelseabfinn @vincesitzmann @YunzhuLiYZ @GeorgiaChal!
📄 Paper submissions are open now and close October 12. We welcome both research papers and position papers.
🏆 Submit your work for a chance to win an NVIDIA Jetson Thor or a Samsung Galaxy Tab S11 Ultra!
Organized by @longhini_a @wenlong_huang Lasse Peters, @Jefferson_Aero , @PatkiSiddharth @jeff_ichnowski @drfeifei and myself. Thanks to sponsors @NVIDIARobotics and @Samsung!
6
19
173
20,912
Yunzhu Li retweeted

Learning bimanual dexterous manipulation from a single human video? Agents can be a solution!
Introducing DexAgent, an agentic Human2Sim2Robot framework for dexterous manipulation with a self-evolving tool library.
We evaluated DexAgent on 11 real-world, long-horizon dexterous manipulation tasks spanning rigid, articulated, and deformable objects.
🤖 63.6% policy rollout success rate, compared with 18.2% for the strongest baseline
⚡ 2.1 hours average inference time with the tool library, compared with 3.3 hours for the baseline
🧰 A self-evolving library with 103 skills + 188 verifiers, designed to keep growing as DexAgent encounters new tasks and objects
Learn more and contribute to the growing tool library:
Project Website: dexagent1.github.io/
Arxiv: arxiv.org/abs/2609.35318

3
10
66
9,728
Yunzhu Li retweeted

We are releasing Dyna-2.1, the first Physical Agent that achieves reliable super long-horizon whole-body autonomy. It combines our brand-new semi-humanoid hardware with an agentic system built around Dyna-2 to handle ultra-long real-world workflows.
Here is an uncut footage of Dyna-2.1 completing an entire hour-long laundry room workflow, just like a human does.

118
391
5,145
3,095,437
Congrats, Shivansh! It has been a pleasure to be part of your PhD journey and see your work span video prediction and simulation for robot learning. Excited to see what you’ll build next with the Optimus team at Tesla! 🎉

I’ve defended my PhD in Computer Science from @UofIllinois and joined @Tesla_AI to work on @Tesla_Optimus!
Grateful to my advisors, Lana Lazebnik and @YunzhuLiYZ, and everyone who supported me.
Excited to keep building robots that can work in the real world.


2
61
11,281
Congrats, Hongyu! Proud to have hosted you at Columbia and explored a range of topics: deformable objects, tactile sensing, and Action Flow as a versatile representation for world modeling.
Fortunate to have been part of your journey, and all the best for your next chapter! 🎉

I successfully passed my Ph.D. thesis defense! 🎉
Huge thanks to my advisor and committee members George Konidaris, @YunzhuLiYZ, and @StefanieTellex for all their support and guidance.
Thanks to my amazing labmates @BrownBigAI for turning me into the best chicken ever 🐔 (a proud @BrownCSDept Ph.D. graduation tradition)!


2
1
49
9,553

Welcome to Voyager.
From just 32 images of our campus, World Labs’ Atlas model created a new way for you to move through our park in real time, built on NVIDIA’s open platform, choosing where to go and what to see.
@theworldlabs, you made our home look good. 💚

From 32 input images to real-time flight through @nvidia's Voyager headquarters.
Trained on NVIDIA Blackwell GPUs, Atlas uses these images as 3D spatial context to generate new views, letting you explore with pixel-perfect camera control.
Take a look around.

66
85
583
102,113
Yunzhu Li retweeted

From 32 input images to real-time flight through @nvidia's Voyager headquarters.
Trained on NVIDIA Blackwell GPUs, Atlas uses these images as 3D spatial context to generate new views, letting you explore with pixel-perfect camera control.
Take a look around.
54
76
498
228,390
Yunzhu Li retweeted
Introducing PointZero—a 3D world model pre-trained without robots.
Dexterous manipulation requires understanding diverse 3D dynamics, but current approaches rely on expensive robot data. So how can we pre-train a 3D dynamics model without it?
PointZero introduces a simple idea: learning to complete 3D point tracks yields transferable 3D dynamics!
Our model achieves SOTA results on:
🔥 Zero-shot 3D dynamics
🔥 Action-conditioned 3D dynamics (post-training)
🔥 Imitation learning (post-training)
Details and links 👇 1/6

8
45
256
28,483
Yunzhu Li retweeted

Can your robot learn by watching? 🤖 Join #V2DChallenge for a chance to win awards, present at CoRL 2026, and co-author our technical report!
Judges: @YunzhuLiYZ , @haosu_twitr, Louis Lian, @ChangliuL.

What could robots learn from the videos we already have?
Join the Video to Data (V2D) Challenge to help turn human demonstrations into robot skills for 3 tracks:
🔹 4D Reconstruction
🔹 Robotic Grounding
🔹 Egocentric Video-to-Policy.
You'll have the opportunity to:
🏆 Earn recognition at #CoRL2026, where the winning solutions will be announced
🛠️ Receive evaluation at scale, with top teams invited to integrate their code into a maintained repository
📋 Contribute to the challenge’s technical report
Register here by September 21, 2026:
nvda.ws/4yGsIcP

2
15
2,350
Yunzhu Li retweeted

Incredible opportunity for robotic learning researchers/engineers to join @theworldlabs! ❤️🔥

We're hiring in robot learning at @theworldlabs! Join me, @drfeifei, and the team to define and scale the next generation of world models for robot learning!
Atlas for Robotics: worldlabs.ai/blog/atlas#robo…
Real-to-Sim-to-Real: worldlabs.ai/blog/real-to-si…
Apply: jobs.ashbyhq.com/worldlabs/8…

33
74
835
142,577
We're hiring in robot learning at @theworldlabs! Join me, @drfeifei, and the team to define and scale the next generation of world models for robot learning!
Atlas for Robotics: worldlabs.ai/blog/atlas#robo…
Real-to-Sim-to-Real: worldlabs.ai/blog/real-to-si…
Apply: jobs.ashbyhq.com/worldlabs/8…
23
38
540
166,529
Yunzhu Li retweeted

Introducing OM-1, our first robot foundation model, zero-shot generalizing to any robot: table-top arms, industrial arms and humanoids.
- learned directly from human manipulation data
- no teleop/robot data
- close to human-level dexterity and efficiency
- multi-robot collab

154
480
3,507
1,758,423
Yunzhu Li retweeted

I asked Astra to express itself using a keyboard.
40 minutes, several accidental long presses, and a lot of backspace later, it learned how to type.
Video at 20× speed. Watch till the end!

18
23
300
48,514
Yunzhu Li retweeted

When we say Atlas has pixel-perfect camera control, we mean it.
Atlas precisely follows input camera parameters, including non-planar projections such as the Brown-Conrady distortion model and the Kannala-Brandt fish-eye model.
@BhamidipatiPan1 invented a novel method of camera conditioning and it works beautifully.
🧵 [1/N]

15
99
826
93,329
Yunzhu Li retweeted

yes
(grabbed 8 frames from a drone flyover video on youtube as input)


35
46
794
100,874
Another glimpse of Real2Sim with Atlas: capture a real environment with just a number of casual photos from a phone, turn them into a sim, then simulate diverse robots navigating different trajectories. Atlas generates the RGB and depth observations they would see along the way.
For robotic simulation, Atlas reconstructs a space from just a few photos and generates the photorealistic RGB and depth data any robot's sensors would observe on any trajectory.
Robots can now be trained and tested in far more spaces. Until now, scanning spaces like these required expensive equipment and time-consuming capture.

9
8
120
22,381
Yunzhu Li retweeted
Indeed Jim, a camera conditioned world model with spatial context has so much horizontal usage including real2sim for robotics!
2
1
59
6,197

Yunzhu Li retweeted
I'm so excited that our @theworldlabs team has achieved a major milestone today! Introducing Atlas - a first of its kind multimodal world model trained from scratch! 🚀
Atlas is capable of generating frames with pixel-perfect camera control, reconstructing large scenes from as few as one single input image, simulating space-time by reframing videos, natively outputting 3D spaces from one or more input images, composing multiple posed images into a consistent 3d world, and more! This is the best camera conditioned world model ever, opening doors to many possible use cases from VFX to robotics. I'm so so so proud of our team!♥️
Introducing Atlas:
The world's first multimodal world model that generates image and video frames with pixel-perfect camera control and reconstructs them in 3D.
Model the world, move the camera, and simulate space & time.

326
1,103
9,757
1,257,189
One month into joining World Labs, it’s been incredible to witness Atlas come to life under the leadership of @jcjohnss, @BenMildenhall, and @drfeifei. 🚀
Proud to contribute on the robotics side and show how Atlas can bridge world models and physical AI: turning a few casual real-world recordings into interactive simulations with controllable objects, motions, lighting, and environments.
And this is just the beginning. Very excited about what Atlas can unlock for robot learning at scale!! 🤖

Introducing Atlas:
The world's first multimodal world model that generates image and video frames with pixel-perfect camera control and reconstructs them in 3D.
Model the world, move the camera, and simulate space & time.
17
30
430
42,278