

Where AI meets the real world. We measure and advance the frontier of AI through community-driven evaluation. We’re hiring → arena.ai/jobs
US
- Tweets 4,028
- Following 224
- Followers 232,185
- Likes 2,720


Introducing Agent Mode: Agentic AI is now measured in the Arena.
Agent Mode can do deep research, create reports, generate images, build websites, debug code, and more.
It completes more complex tasks by using tools like web search, bash in a sandbox environment, image generation, file writing, and asking follow-up questions.
Frontier models are waiting for you in Agent Mode to take on real-world tasks. GPT-5.5, Claude Opus 4.7, Gemini 3.1 Pro, and top open models. Test them yourself.

104
77
940
540,238
MiMo-V2.6-Flash has landed on the Agent Arena Pareto frontier with -0.57% net improvement at a $0.04 median cost per task!
Dive into the Agent Arena Pareto frontier at: arena.ai/leaderboard/agent/p…

4
3
57
11,300
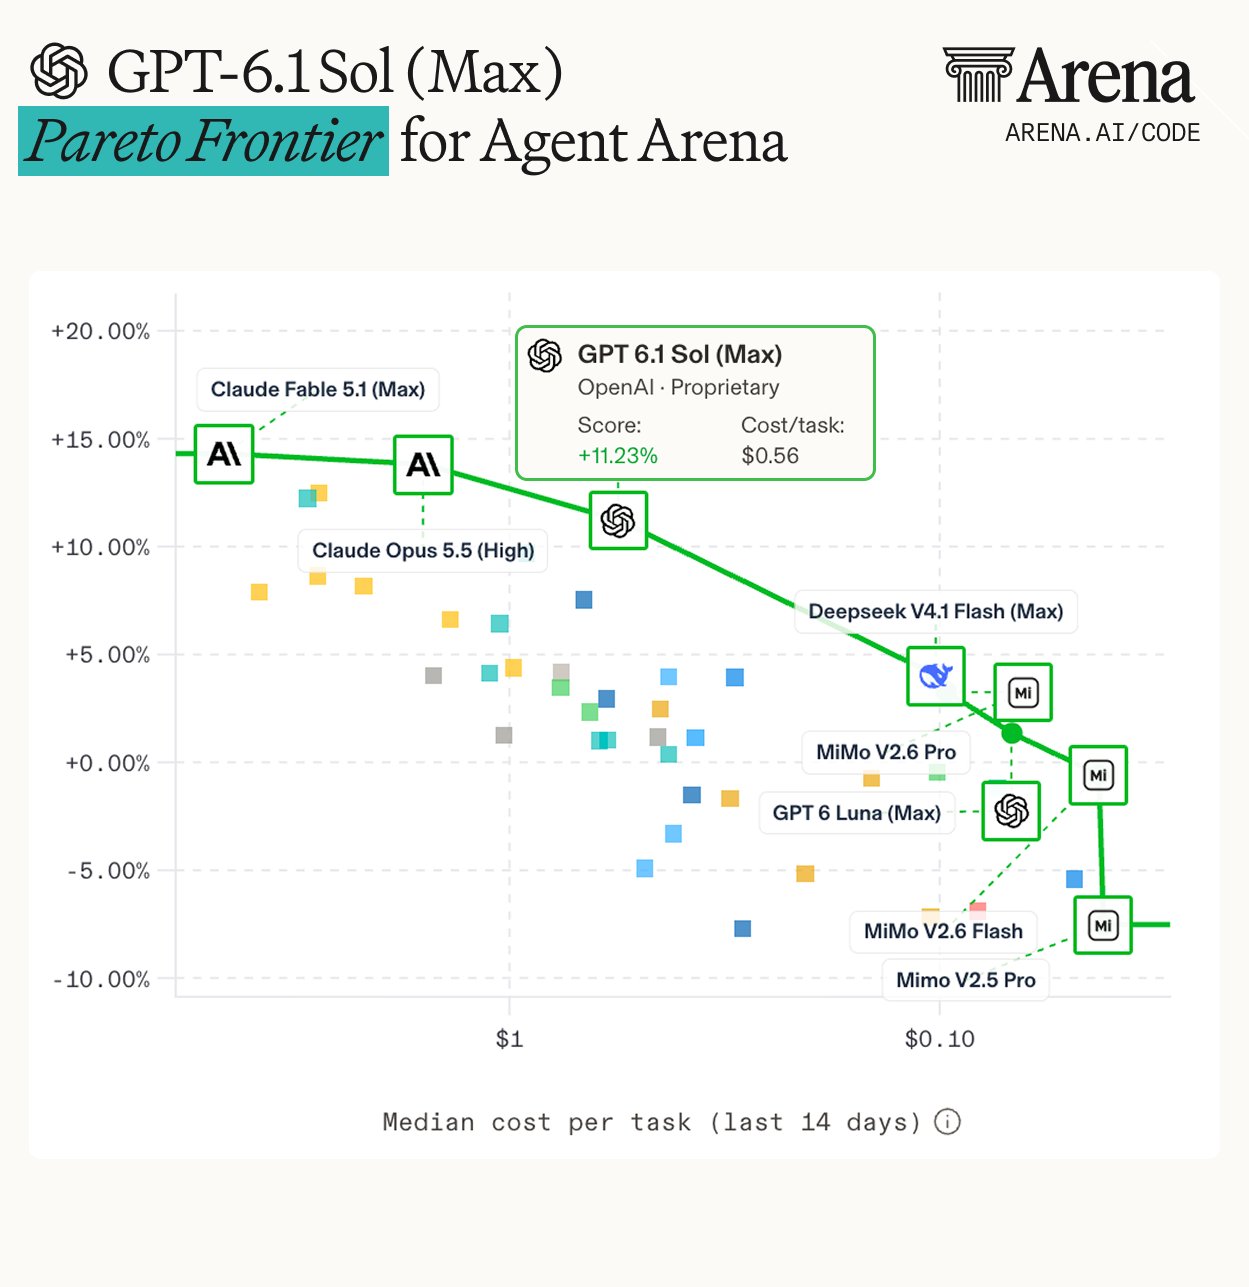
Exciting news: GPT-6.1 Sol (Max) by @OpenAi just landed in the Agent Arena at #5 (+11.23%) and reshaped the Pareto frontier!
At a $0.56 median cost per task, it delivers performance within 2 percentage points of GPT-6 Sol and GPT-6 Astra for substantially less cost:
- 39% lower cost than GPT-6 Sol, while scoring +1.52 pts higher
- 81% lower cost than GPT-6 Astra, while landing within 1.04 pts
GPT-6.1 Sol also delivers top-five performance at substantially lower cost compared to:
- 88% lower cost than Claude Fable 5.1 (Max), while landing within 3.08 pts (ranked #1)
- 65% lower cost than Claude Opus 5.5 (High), while landing within 2.59 pts (ranked #2)
- 80% lower cost than Claude Sonnet 5.5 (Max), while landing within 1.29 pts (ranked #3)
Congrats to the team @OpenAI on this release!


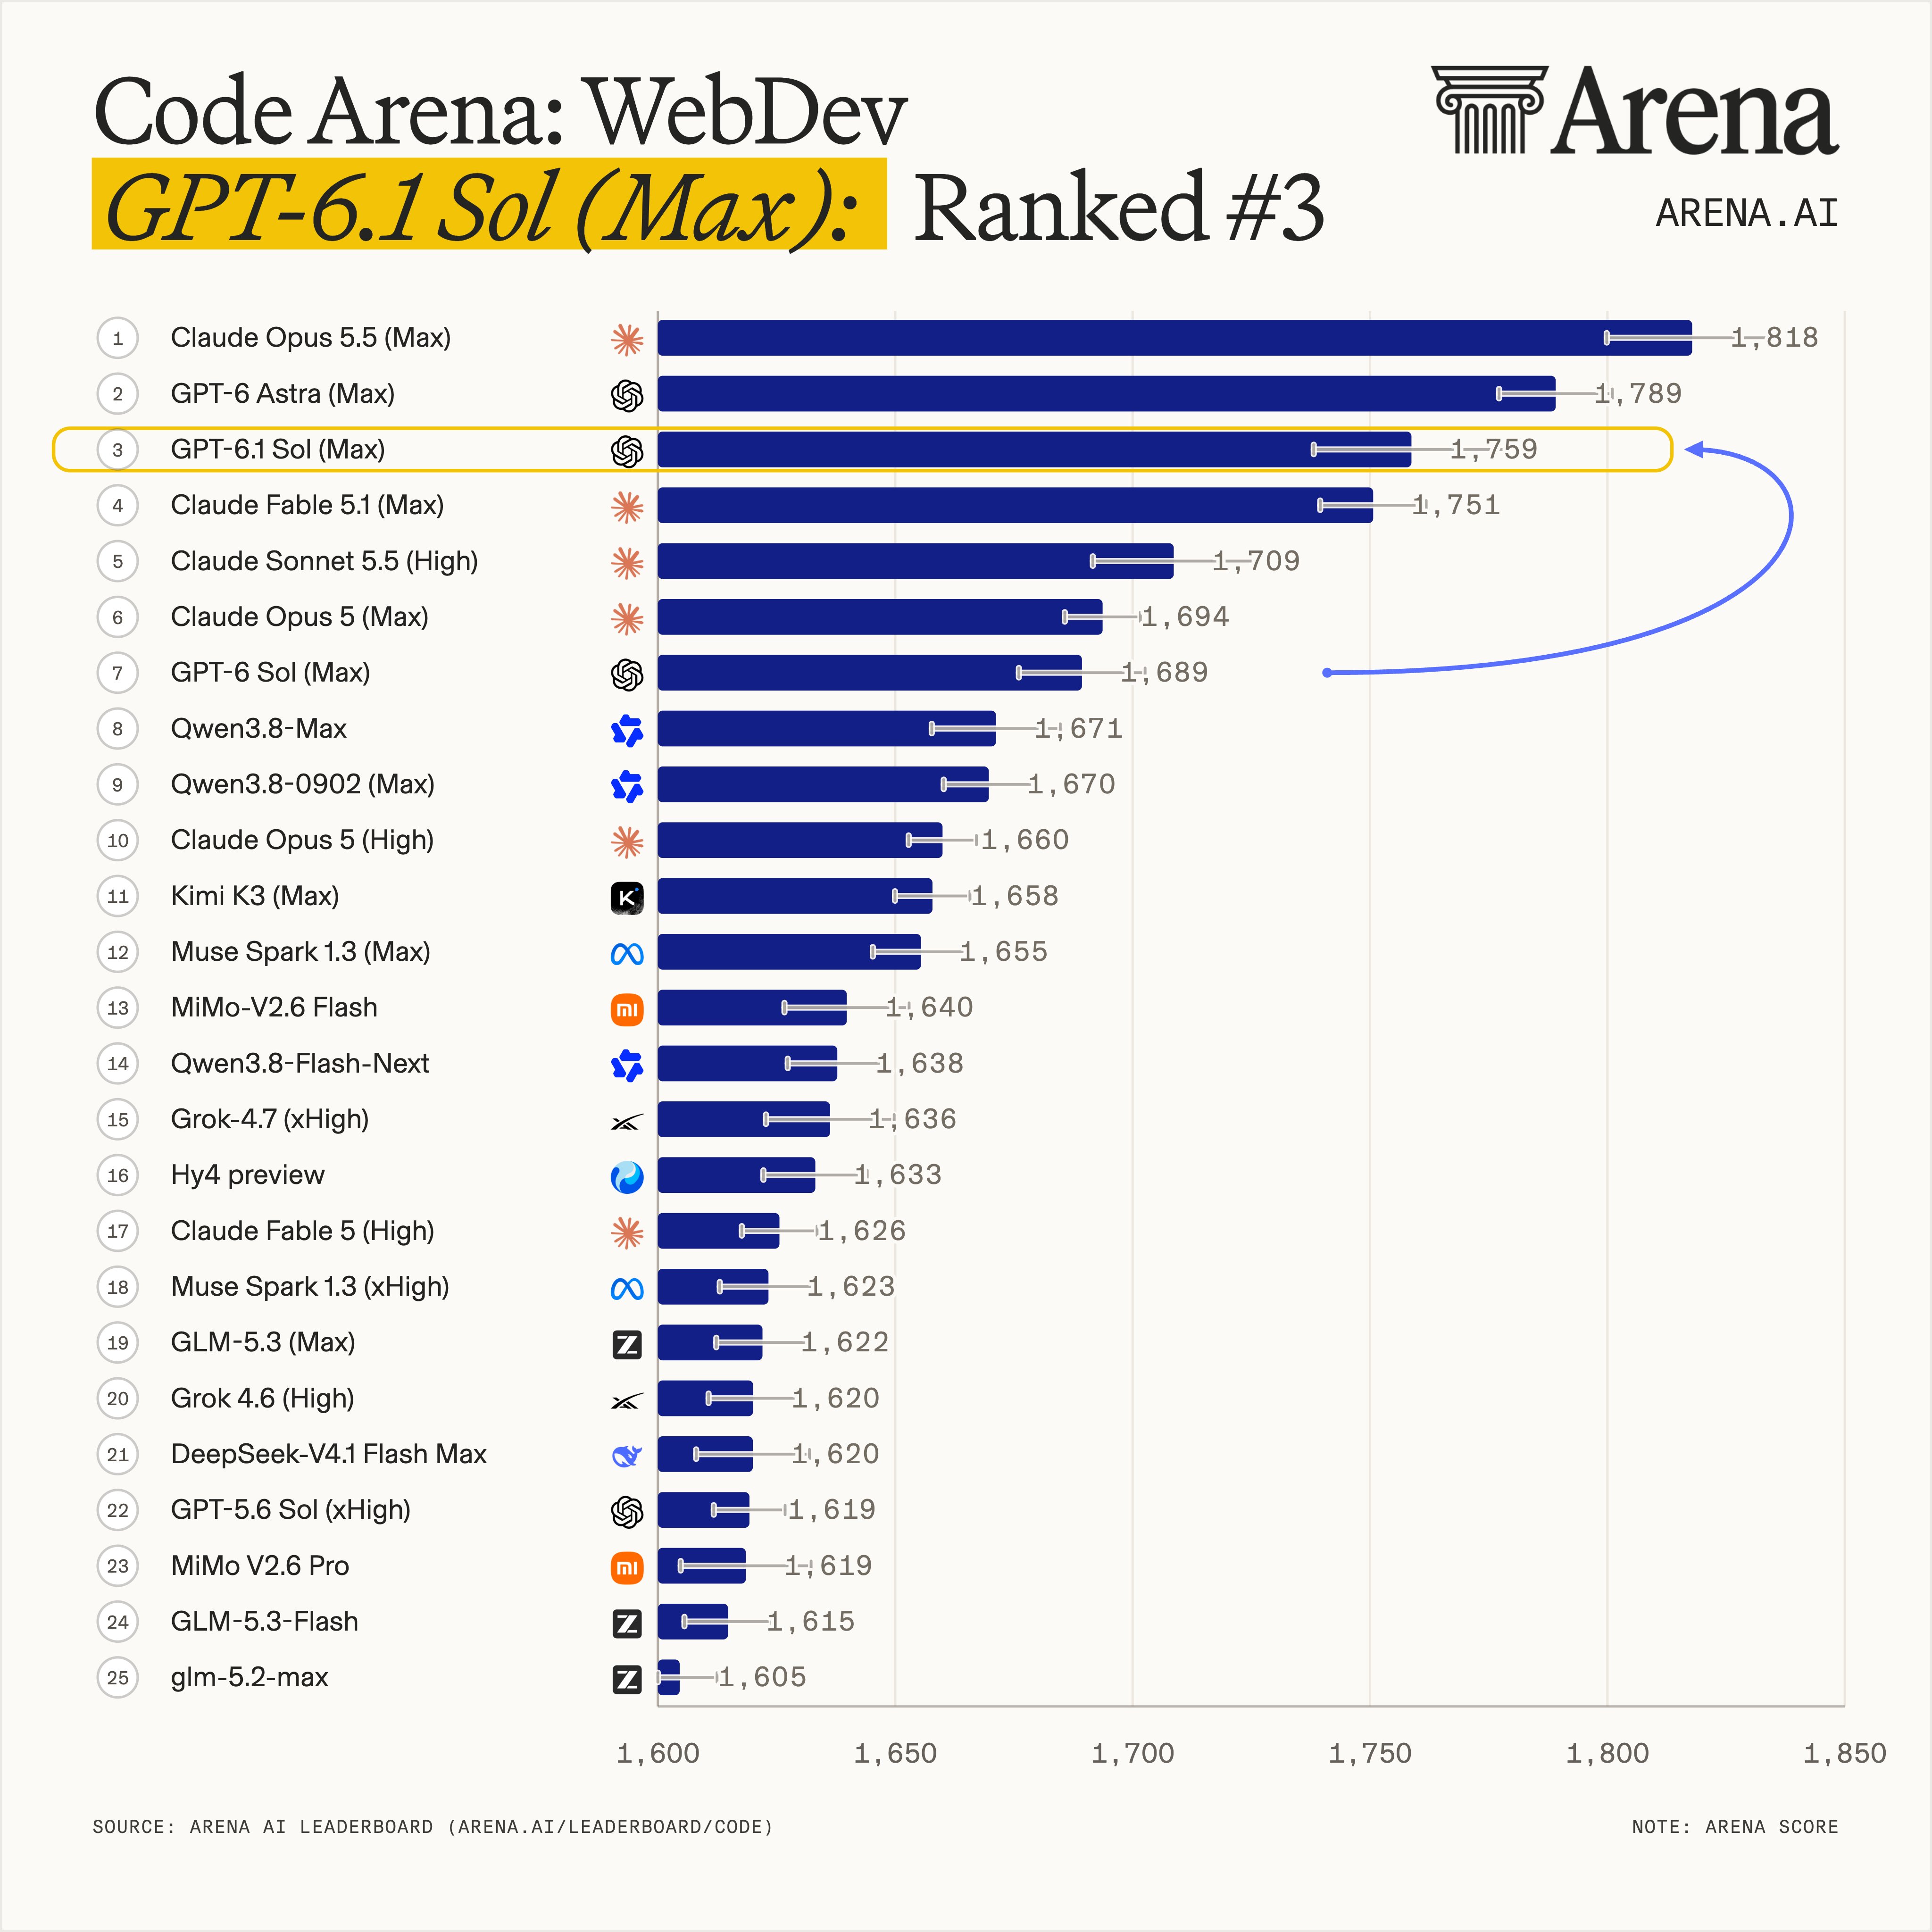
Exciting news: GPT-6.1 Sol (Max) by @OpenAI just landed the Code Arena: WebDev at #3 with 1759 pts, and at a blended $8/MToken it reshapes the Pareto frontier!
GPT-6.1 Sol (Max) marks a clear improvement in cost efficiency: it gained 70 points over GPT-6 Sol (Max) for the same price.
It landed within 30 points of GPT-6 Astra (Max) at 80% lower blended token cost, and 59 points from Claude Opus 5.5 (Max) at 50% of the price. See position on the Pareto frontier for the Code Arena: WebDev in the post below.
Overall, GPT-6.1 Sol improved from GPT-6 Sol by 4 rankings! It also improved in every category:
- Consumer Product: #5 → #1
- Simulations: #6 → #3
- Data & Analytics: #4 → #3
- Content Creation Tools: #4 → #3
- Gaming: #6 → #4
- Reference-Based Design: #6 → #4
- Brand & Marketing: #10 → #6
Congrats to the @OpenAI team on the release!
31
28
391
48,878
See the live results and dive into the Agent Arena Pareto frontier at: arena.ai/leaderboard/agent/o…
2
8
4,918
Claude Sonnet 5.5 by @AnthropicAI just landed at #3 in the Agent Arena. This model has a median cost per task of $2.74, and a +12.5% net improvement score.
Claude Sonnet 5.5 delivers top-tier performance, but at a cost premium: #2 Claude Opus 5.5 costs $1.58 per task while achieving a higher score. That tradeoff keeps Sonnet 5.5 just off the Agent Arena Pareto frontier.

Exciting news: Claude Sonnet 5.5 (Max) by @AnthropicAI has debuted at #3 in the Agent Arena with +12.5% net improvement!
This release is a 8.1 percentage-point increase over Claude Sonnet 5 (High), which ranks #13 with +4.4% net improvement. By category, Claude Sonnet 5.5 secured the #1 spot in Chat (+15.6%) above both Fable 5.1 (+11.49%) and Opus 5.5 (+10.29%).
This performance comes with a higher cost: Claude Sonnet 5.5 (Max) has a median cost of $2.74 per task, about 73% higher than #2 Claude Opus 5.5 (High) at $1.58.
@AnthropicAI models now hold all three top positions in Agent Arena. Congrats to the team!

21
17
297
34,040
See the live results and dive into the Agent Arena Pareto frontier at: arena.ai/leaderboard/agent/o…
3
4,213
Exciting news: Claude Sonnet 5.5 (Max) by @AnthropicAI has debuted at #3 in the Agent Arena with +12.5% net improvement!
This release is a 8.1 percentage-point increase over Claude Sonnet 5 (High), which ranks #13 with +4.4% net improvement. By category, Claude Sonnet 5.5 secured the #1 spot in Chat (+15.6%) above both Fable 5.1 (+11.49%) and Opus 5.5 (+10.29%).
This performance comes with a higher cost: Claude Sonnet 5.5 (Max) has a median cost of $2.74 per task, about 73% higher than #2 Claude Opus 5.5 (High) at $1.58.
@AnthropicAI models now hold all three top positions in Agent Arena. Congrats to the team!
Exciting update: Claude Sonnet 5.5 with xHigh reasoning has landed in the Code Arena: WebDev. With 1786 pts, its ranked #3!
At a blended $8/M tokens, Claude Sonnet 5.5 remains on the Pareto frontier with xHigh reasoning. This release is just 2 pts from GPT-6 Astra in the #2 spot with 1788 pts, for 80% of the price.
By domain, Claude Sonnet 5.5 (xHigh) landed:
- #2 in Gaming, Reference-Based Design, and Brand & Marketing
- #3 in Simulations
- #4 in Content Creation Tools and Consumer Product
- #6 in Data & Analytics
Congrats again to @AnthropicAI on this release!

25
23
391
47,843
Dive into the Code Arena: WebDev leaderboard at arena.ai/leaderboard/code/we…
1
1
5
3,756
This Week in the Arena: Four releases reshaped the Pareto frontier across Text, Code, and Agent Arena.
- After OpenAI’s DevDay, GPT-6.1 Sol (Max) entered Code Arena: WebDev at #3 and joined the Pareto frontier at $8/MToken.
- However, once Sonnet 5.5 entered the leaderboard later that day, Sol moved to #4 and fell off the Pareto frontier. Today, Sonnet is 2 points behind #2 GPT-6 Astra (Max) at 80% lower cost.
- Excitingly, Gemini 4 Argon (High) landed at #1 in Text Arena, #8 in Code Arena: WebDev (1679 pts), and #8 in Agent Arena (+7.92% net improvement).
- Finally, MiMo-V2.6-Pro and Flash entered Agent Arena at #5 and #9 among open-source models, respectively.
Agent scores for GPT-6.1 Sol and Sonnet 5.5 are coming soon. Stay tuned!
See leaderboards, other updates, and more in less than 90 seconds in the video.
piped.video/watch?v=Mh0buAJI…
36
5
164
25,179
How to design rewards for post-training frontier image models?
Our research suggests human preference reward is necessary, but insufficient: A preference model may still reward outputs that look appealing but miss details, introduce unrequested content, or exhibit other forms of reward-hacking.
We therefore optimize towards a composite reward:
- Bradley-Terry reward model trained on ~5.6M pairwise human votes
- Faithfulness reward from auto-generated prompt checklists evaluated by a vision-language model
- Constraint reward covering explicit and implicit user intent
- Anti-reward-hacking rubric rewards targeting failures such as garbled text and photorealism drift
This post-training recipe improves two already-strong open image models:
- Post-trained FLUX.2-dev gains 69 Elo points on our live T2I leaderboard, scoring 1202
- Post-trained Ideogram 4 gains 20 Elo points reaching a score of 1224 and surpassing all publicly listed open models (as of Sep 04, 2026).
Offline ablations with Gemini 3.5 Flash as the judge, show that these reward components are complementary: win rate against the base model increases as we add faithfulness and then constraint rewards on top of preference-only training, reaching 64.2%.
Finally, we ensemble policies trained with and without the anti-reward-hacking objective directly in weight space, further increasing win rate to 66.0%.

18
13
149
17,597
Read more about how to post-train frontier text-to-image models on our blog. You’ll learn how the rubric rewards are built, the full offline eval setup, and visual before/after comparisons showing the reward-hacking failure modes we caught: arena.ai/blog/post-training-…
2
1
10
5,127
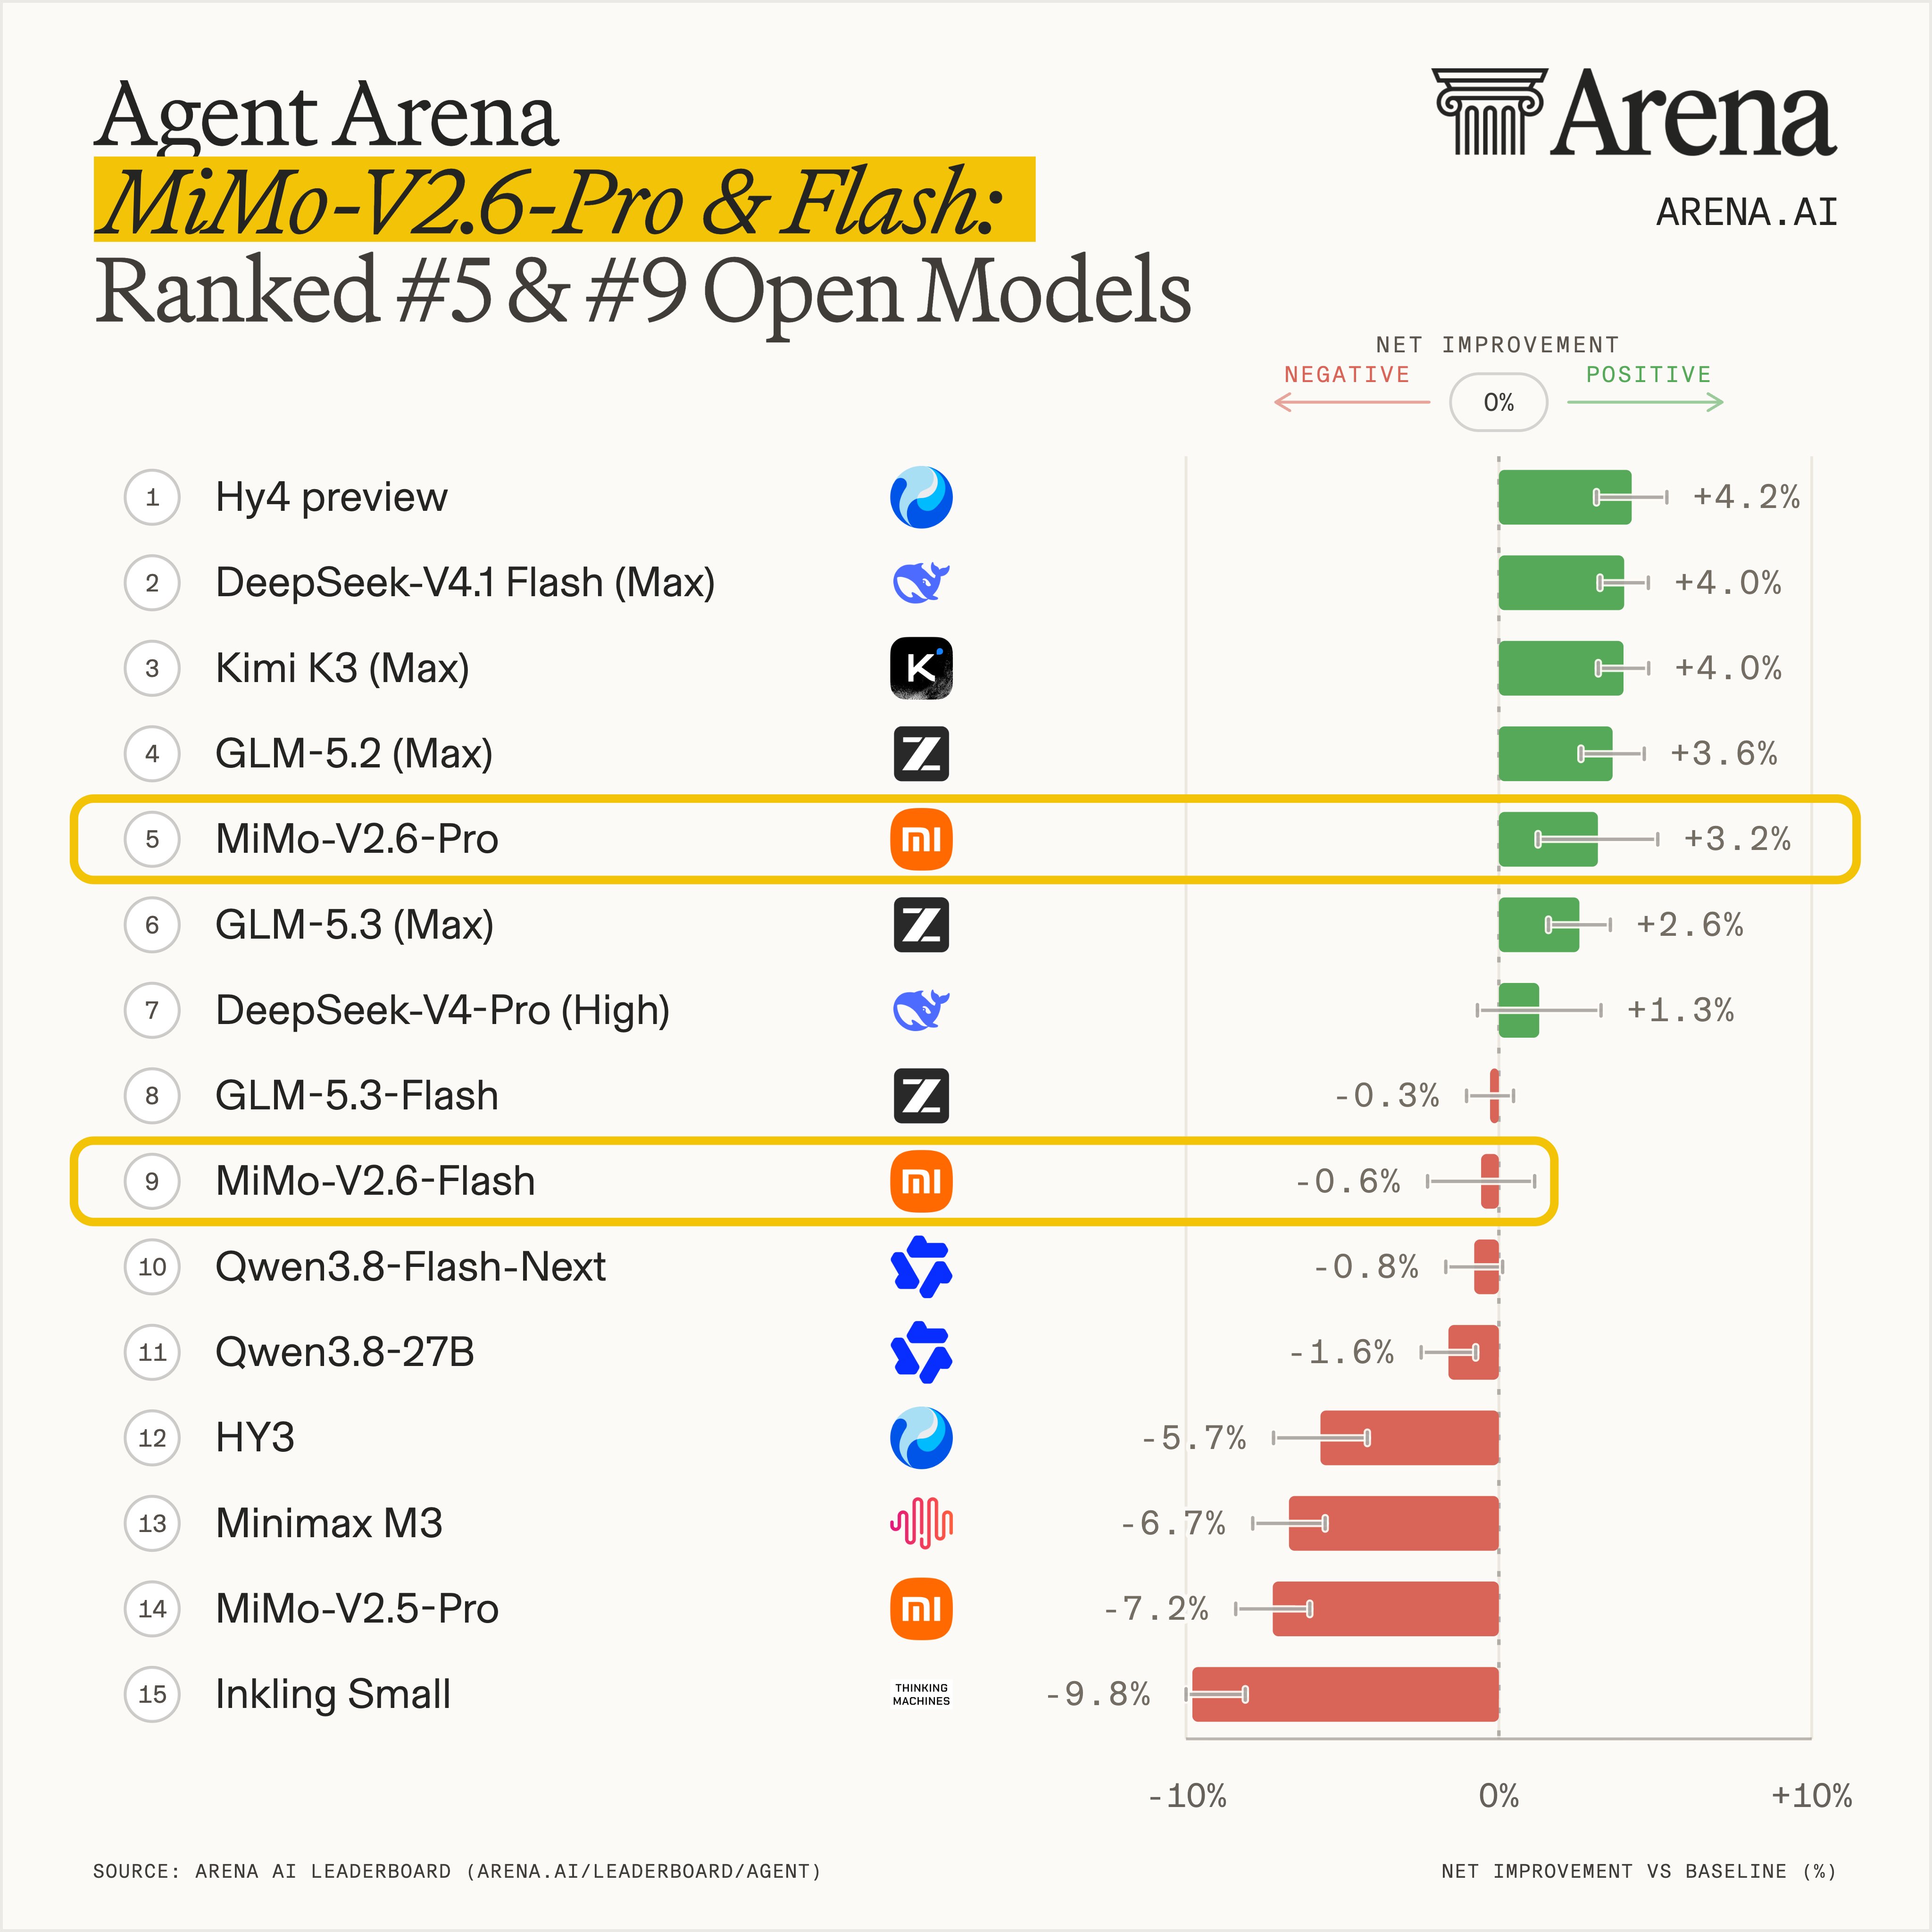
MiMo-V2.6-Pro and MiMo-V2.6-Flash by @XiaomiMiMo have landed in Agent Arena!
MiMo-V2.6-Pro ranks #5 among open-source models with +3.17% net improvement across 8.1K+ real-world agentic sessions. This release is a +10.4 percentage-point lift and a 9-spot improvement from MiMo-V2.5-Pro at #13 with -7.23%!
Its strongest signal is Confirmed Success (explicit user feedback that the task worked) where it scored +7.35% and ranks #2 among open-source models!
MiMo-V2.6-Flash landed #9 among open models with -0.57% net improvement across 13K+ real-world agentic sessions.
At a $0.04 median cost per task (56% lower than MiMo-V2.6-Pro), it also landed on the Agent Arena Pareto frontier! See its placement below.
Congrats to the @XiaomiMiMo team on the release!

Introducing Xiaomi MiMo-V2.6 — Pro & Flash.
Frontier intelligence, all the modalities, built in public.
🔹 Two omnimodal models, advancing through scaled reinforcement learning
🔹 Pro performs on par with Claude Opus 5 and GPT-5.6 Sol across most agent benchmarks
🔹 Pro scores 46 on the Artificial Analysis Intelligence Index — the highest among open-source models
🔹 Stronger coding, computer use, 3D reasoning and creative capabilities
🔹 Open model weights, technical report, RL environments and training code
Blog:mimo.xiaomi.com/mimo-v2-6

29
17
363
39,170
MiMo-V2.6-Flash has landed on the Agent Arena Pareto frontier with -0.57% net improvement at a $0.04 median cost per task!
Dive into the Agent Arena Pareto frontier at: arena.ai/leaderboard/agent/p…
4
3
57
11,300
Exciting update: Claude Sonnet 5.5 with xHigh reasoning has landed in the Code Arena: WebDev. With 1786 pts, its ranked #3!
At a blended $8/M tokens, Claude Sonnet 5.5 remains on the Pareto frontier with xHigh reasoning. This release is just 2 pts from GPT-6 Astra in the #2 spot with 1788 pts, for 80% of the price.
By domain, Claude Sonnet 5.5 (xHigh) landed:
- #2 in Gaming, Reference-Based Design, and Brand & Marketing
- #3 in Simulations
- #4 in Content Creation Tools and Consumer Product
- #6 in Data & Analytics
Congrats again to @AnthropicAI on this release!
Real-world results are in for Claude Sonnet 5.5 (High) by @AnthropicAI. It just landed #4 in Code Arena: WebDev with 1699 pts, and has reshaped the Pareto frontier with its cost efficiency!
Claude Sonnet 5.5 (High) delivers nearly top performance at a blended $8 per Mtoken, reshaping the Pareto frontier! This model is 80% cheaper than both Claude Fable 5.1 (Max) in the #3 spot overall, and GPT-6 Astra (Max) at #2.
See Pareto placement below.
Overall, Claude Sonnet 5.5 (High) is a +159 pt improvement from Sonnet 5 (High) at #37 with 1540 pts. This gain compared to its previous variant also shows up across these key domains so far:
- Reference-Based Design: #38 → #4
- Simulations: #37 → #4
- Gaming: #36 → #4
Congrats to @AnthropicAI on this release!

44
24
504
80,260
Dive into the Code Arena: WebDev leaderboard at arena.ai/leaderboard/code/we…
1
1
8
4,581
More big news from @GoogleDeepMind: Gemini 4 Argon (High) is #8 in Agent Arena with a +7.92% net improvement score, and has reshaped the Pareto frontier with a $0.62 cost per task! See its placement below.
Gemini 4 Argon (High) is a 4.96 percentage point improvement over Gemini 3.8 Flash (High), at #19 with +2.96% net improvement.
By key signals, Gemini 4 Argon (High) stands out in:
- #1 in Steerability with +15.88% (the model’s ability to course-correct when you push back)
- #2 in Confirmed Success with +14.15% (explicit user feedback that the task worked)
- #4 in Praise vs Complaint with +27.74% (implicit sentiment in user reactions)
By category Gemini 4 Argon (High) is especially strong in Chat, landing at #3 with +11.58% net improvement.
With 3k real-world agentic sessions so far, this score is preliminary. Stay tuned as more traces come in from our global community of users.
Congrats to the @GoogleDeepMind team on this release!

Big news: Gemini 4 Argon (High) by @GoogleDeepMind just landed #1 in Text Arena with 1525 pts, and #8 in Code Arena: WebDev with 1679 pts!
This release has reshaped the Text Arena Pareto frontier with a blended $8/MToken! Gemini 4 Argon (High) is now the most cost efficient model, see its placement on Pareto frontier below.
In the Text Arena, Gemini 4 Argon (High) ranks #1 in Coding, Hard Prompts, Instruction Following, Longer Query, and Creative Writing. It also leads every occupational domain evaluated, with additional #1 spots in English, Non-English, Chinese, and Russian.
This model is +20 points above the #2 ranked Claude Opus 4.6 (High), and a huge leap from Google’s previous release, Gemini 3.8 Flash (High) at #11!
In Code Arena: WebDev, Gemini 4 Argon (High) gained +96 points from Gemini 3.8 Flash (High), and went from #29 to #8.
Congrats to the @GoogleDeepMind team on this impressive frontier release!


18
30
582
61,641
Arena Open House: Rooftop Happy Hour 10/7.
We're throwing open the doors to our new SF HQ office and want to invite researchers, developers, and builders pushing on hard AI problems up to the roof! Come hang out, meet the team, and check out the space - Bay Area views included.
Boba bar, light bites, and refreshments provided.
Space is limited. Register to request a spot on the list!
luma.com/8jmuq1f2
3
2
32
10,100
Gemini 4 Argon by @GoogleDeepMind just went head-to-head with top frontier models across a set of generations.
At 33% lower cost per task than GPT-6.1 Sol, and 70% lower than Claude Opus 5.5, see first impressions from @petergostev on how Gemini 4 Argon compares.
piped.video/watch?v=h5EL5zTh…
26
15
309
31,874
Hidream-O1-Video-1.0 by @HiDream_AI just landed in the Image-to-Video Arena at #7 with 1456 pts!
This model is available on @vivago_ai, is 8 pts away from gemini-omni-flash and within 20 pts of both dreamina-seedance-2.0 and 2.5.
Congrats to @HiDream_AI on this release!


New HiDream models just landed in vivago R1 Studio 🚀
Introducing:
• HiDream-O1 Image 2.0
• HiDream-O1 Editing 1.5
• HiDream-O1 Video
All three models are now available in vivago R1 Studio - bringing the latest HiDream image generation, editing, and video capabilities directly into your creative workflow.
New models. New possibilities. Go make something the internet can’t ignore. 🔥

7
4
102
21,431
Dive into the Image-to-Video leaderboard at: arena.ai/leaderboard/image-t…
8
5,542
Arena.ai retweeted

The chakras have realigned
Google hits #1 on Text Arena
Top-3 provider in Code Arena

Big news: Gemini 4 Argon (High) by @GoogleDeepMind just landed #1 in Text Arena with 1525 pts, and #8 in Code Arena: WebDev with 1679 pts!
This release has reshaped the Text Arena Pareto frontier with a blended $8/MToken! Gemini 4 Argon (High) is now the most cost efficient model, see its placement on Pareto frontier below.
In the Text Arena, Gemini 4 Argon (High) ranks #1 in Coding, Hard Prompts, Instruction Following, Longer Query, and Creative Writing. It also leads every occupational domain evaluated, with additional #1 spots in English, Non-English, Chinese, and Russian.
This model is +20 points above the #2 ranked Claude Opus 4.6 (High), and a huge leap from Google’s previous release, Gemini 3.8 Flash (High) at #11!
In Code Arena: WebDev, Gemini 4 Argon (High) gained +96 points from Gemini 3.8 Flash (High), and went from #29 to #8.
Congrats to the @GoogleDeepMind team on this impressive frontier release!
4
5
209
19,938