

CodeRabbit helps teams review, understand, govern, and trust agent-generated code: coderabbit.ai!
San Francisco, CA
- Tweets 6,692
- Following 106
- Followers 47,087
- Likes 13,617


Pinned Tweet

Agents can create PRs in minutes, but understanding them still takes work.
CodeRabbit Change Stack connects a PR's purpose, behavior, dependencies, and code so reviewers can really verify it before approving.
Do you understand what you're about to merge?

69
55
136
33,658

160+ people hacked on Jev at our SF office 11 days after it launched.
Best tip of the day from Allie Laabs: ask every question you might need in one call.
We cover why, and more, in our latest blog post: coderabbit.ai/blog/the-merge…

Your agent doesn't know Jev.
Most code calls LLMs the long way:
state → prompt → text → parse → if statement
Decision models like Jev skip the text and plug into your logic.
Here's 30 minutes with @typesafeai's @allietheicon on building with it.

3
3
8
1,863
CodeRabbit retweeted

What if your if-statements could think?
I sat down with TypeSafe’s Allie Laabs on The Merge to talk about Jev, decision models, and the habit coding agents still need to learn: ask your questions in parallel.

4
5
16
1,286
Your agent doesn't know Jev.
Most code calls LLMs the long way:
state → prompt → text → parse → if statement
Decision models like Jev skip the text and plug into your logic.
Here's 30 minutes with @typesafeai's @allietheicon on building with it.
12
9
40
13,989

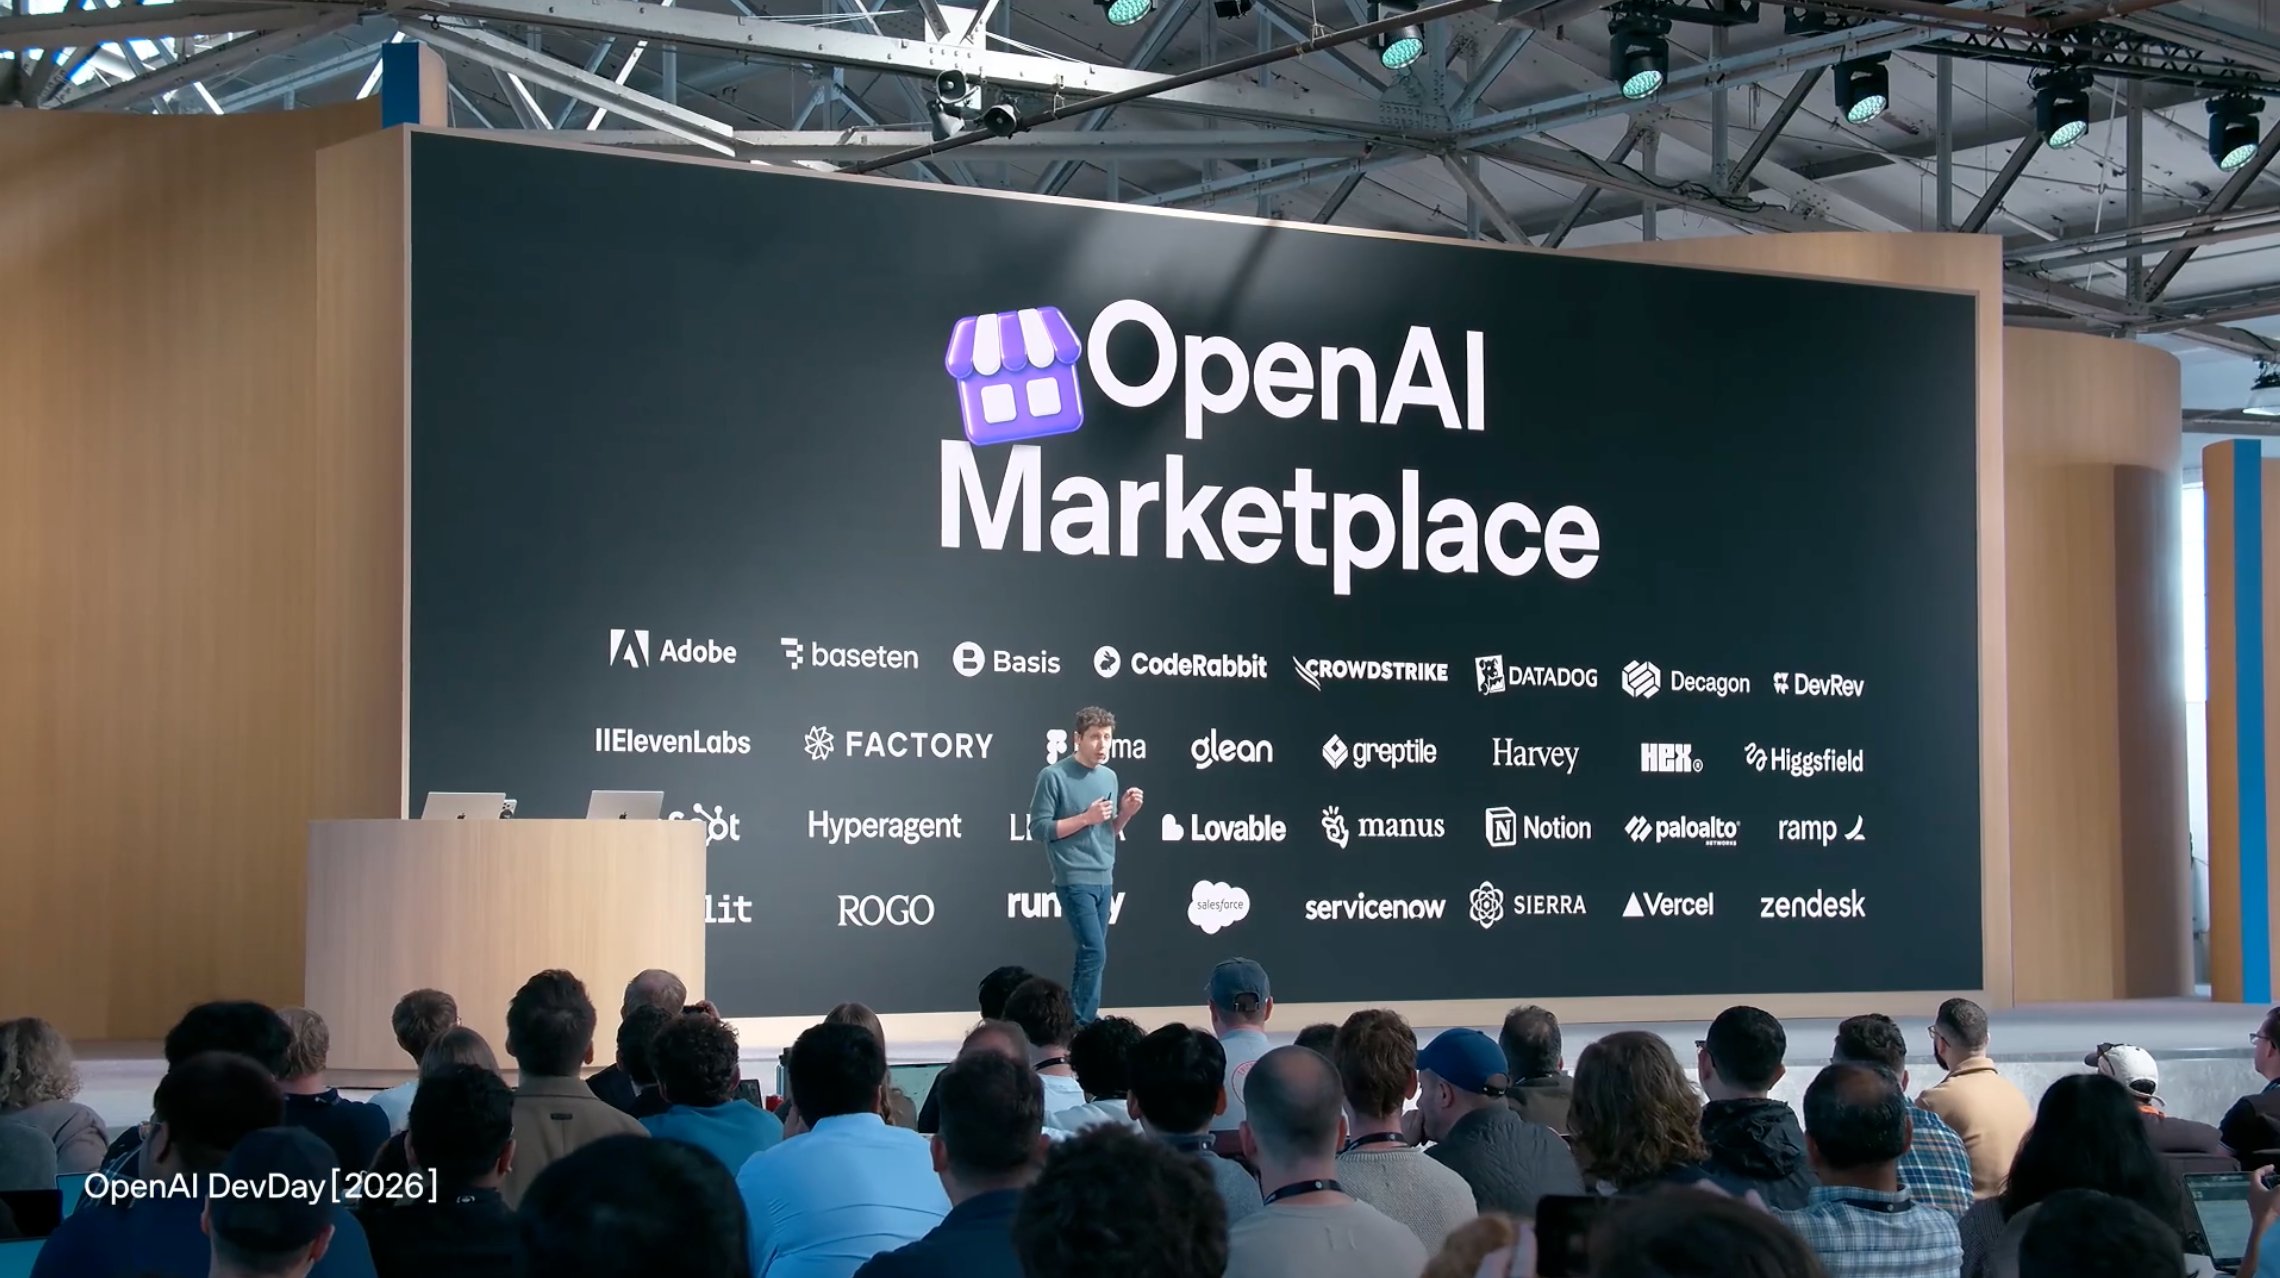
CodeRabbit went live yesterday as a featured launch partner on the new @OpenAI Marketplace.
Coding agents are writing more of the code that ships, and someone still has to know what changed and whether it's safe to merge.
That's the job of our Agentic Change Management platform. It catches bugs and digs into security issues in code from developers and agents alike. And it maps everything a change touches.
It flags which changes actually need a human look, so reviewers spend their time there. People still decide what gets approved and shipped.
For enterprise teams there's a procurement upside too. Existing OpenAI spend commitments can now go toward CodeRabbit through the Marketplace.
 Hendrik Krack

4
13
24
4,264
CodeRabbit retweeted
Your coding agent opened five more PRs while you were reviewing the first one.
CodeRabbit is joining the OpenAI Marketplace, which means your existing OpenAI spend commitment can now cover independent AI code review.
Let the agents keep shipping. We'll read the diffs.
coderabbit.ai/blog/coderabbi…
4
8
28
3,972
CodeRabbit retweeted
Looking forward to this one!

Tonight at HogPatch, the @posthog co-working space in SF, I'll be representing @TryArcade at Fix My Agent.
Bring an agent problem, come over to the Arcade station, and get tips on how you could improve your agent. Governance, tool calling, execution hooks, MCP, all the fun stuff.
I'll be joined by @PrathmeshPatel_ from @mcpjams, @HKrackDev from @coderabbitai, @showmore234 from @gmi_cloud, and @Courtneythko from @aivalleyio

1
9
710
CodeRabbit retweeted
Sonnet 5 overthought its code reviews. Sonnet 5.5 doesn't.
Same 44 open-source PRs:
> ~4× fewer output tokens per call
> under half the input tokens
> 6:33 per review, down from 13:31
> ~60% cheaper
Precision held on the hardest subset.
coderabbit.ai/blog/sonnet-5-…

Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family.
It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.

8
6
34
6,203
RT @HKrackDev: I had Sonnet 5.5 and Opus 5.5 build the Alpine Charlet head2head...
Sonnet finishes 50% faster and the quality is just as…
1
319
Writing code is turning into the cheap part. Knowing which code should exist, which shouldn't, and why is where the value's heading, and Jev is the latest case of AI making those decisions instead of just producing output.
You still have to think like a programmer.
Just a few layers above the code!

Yesterday @coderabbitai didn't just host a hackathon, it was a Jevathon!
Tired of having to think like a robot? Our favorite hacker review was: "Think like a programmer again" with @allietheicon
2
4
18
2,750
CodeRabbit retweeted
Our interns @xrhuang10, @_nikhilhooda and Utkarsh helped me organize this entire event, managing ppl, answering q's while somehow finding the time to hack themselves.
And then... independent judges picked them for 1st place 🏆
Couldn’t be more deserved. Absolute rockstars🤘👏🧡

1/ Yesterday we hosted @typesafeai at our @coderabbitai HQ for Jev's first ever hackathon!
160+ builders. ~4hrs of hacking. Expert judges, Incredible energy.
I also got to sit down with @allietheicon and talk about what Jev means for Coding, Software Development and the new paradigm shift you have to adapt when working with this new class of AI models.
She shared some really helpful tips and examples of how to best work with Jev - I'll try my best to summarize some of them in this thread⬇️


1
4
22
10,977
CodeRabbit retweeted
1/ Yesterday we hosted @typesafeai at our @coderabbitai HQ for Jev's first ever hackathon!
160+ builders. ~4hrs of hacking. Expert judges, Incredible energy.
I also got to sit down with @allietheicon and talk about what Jev means for Coding, Software Development and the new paradigm shift you have to adapt when working with this new class of AI models.
She shared some really helpful tips and examples of how to best work with Jev - I'll try my best to summarize some of them in this thread⬇️
10
11
77
61,080
Google Cloud wrote about how CodeRabbit is moving from AI code review into Agentic Change Management, and what we're building on Cloud Run, Cloud Storage and Gemini to get there.
Read the article here: cloud.google.com/blog/topics…

7
2
8
2,108
Your agent worked all night. Do you merge what it wrote?
Francesco Bonacci (@francedot) of Cua (@trycua) wants his agents shipping while he sleeps, without waking up to a mess he has to clean up. The hard part is staying close enough to steer them.
On this episode of The Merge we get into how he closes the loop on agent tasks, what to do with low-quality AI-generated PRs, and why a proposed patch isn't a merge.
His take: more autonomy means review matters more, not less. You still need to be able to inspect the result and push back on it.

18
8
32
8,113
This week in the CodeRabbit changelog 🐰
→ Share TypeScript review configs across repos
→ Handle metrics API retries with clearer retry guidance
Define review standards once. Reuse them across your team’s repositories.
See the full changelog: docs.coderabbit.ai/changelog
6
6
13
1,839
TypeScript config docs: docs.coderabbit.ai/configura…
MCP Metrics docs:
docs.coderabbit.ai/api-refer…
Review Comment Metrics dovs:
docs.coderabbit.ai/api-refer…
523