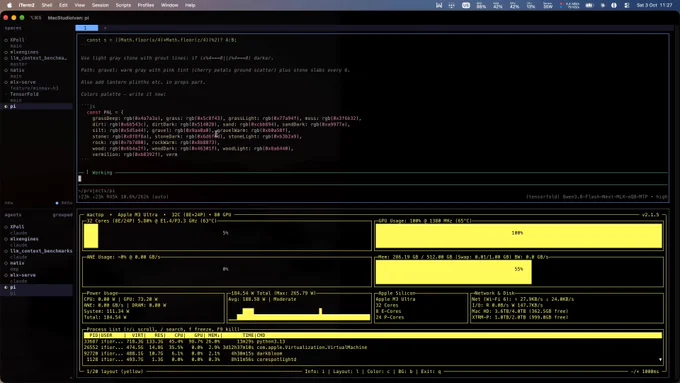
Video of tensorfold running Qwen3.8-Flash-Next-MLX-oQ8-MTP high on M3 Ultra ~80 t/s! It's a great experience, less errors and better quality. Where possible I suggest to use the highest possible quants!
Oct 3, 2026 · 9:29 AM UTC

15
2
40
3,096
Sort replies: Relevant Recent Liked
Replying to @ivanfioravanti
That is amazing! Tensorfold on 2 M5Max via TB5 Q4: prefill : prompt_tokens': 8200, 'ttft_s': 4.062, 'prefill_tps': 2018.5 prose: 'tokens': 4096, 'decode_tps': 82.3 code: 'tokens': 4096, 'decode_tps': 111.9
1
1
70
OH WOW! Amazing numbers there! Can't wait to see a TP2 on 2 x Mac Ultra 256GB via TB5
1
1
75
Replying to @ivanfioravanti
Finally q8
1
1
15
Yes!!! It's another life using q8. Things changes for model trained with QAT in 4bit.
18
Replying to @ivanfioravanti
Love it
1
1
30
M3 Ultra is still a beast in real life scenarios. Prefill is slower, but it can run anything 💪
1
2
94
Replying to @ivanfioravanti
I am going to start optimising TF for 8bit
1
10
282
Replying to @ivanfioravanti
Been running that and many combinations of quants today
1
1
129
Really enjoying 8bit so far! I'll try 6bit later.
2
93
Replying to @ivanfioravanti
Yep.. golden rule, if you have enough GPU memory then do not trade intelligence for speed.. ;)
1
2
76
100%! You gain speed but you lose precision, it's like typing faster on keyboard but having to fix typo errors, final results is going slower.
1
75
Replying to @ivanfioravanti
Any luck with 128GB or less?
1
1
60
DwarfStart + Q4 rocks!
1
49
Replying to @ivanfioravanti
可以分享一下你为什么不用 Mlxserve 吗?
59
Replying to @ivanfioravanti
Ball out sir. Max quants or nothing
47
Replying to @ivanfioravanti
80 t/s on an M3 Ultra is ridiculous. curious if oQ8 still feels good once the context gets long
52
Replying to @ivanfioravanti
10% on a 262k context window, so 26K used. Next time, include it, and don't make me look through your ugly arse UI. 80 t/s lossless quality at 8-bit with a minimum of 200K used of the context would be impressive. Pulling tricks won't make it lossless. The current speed at 200K stands at 42 t/s under oMLX and that is not best, yet.
31
Replying to @ivanfioravanti
higher quants always win out if you can spare the ram
20