

GenAI/LLM addicted, Apple MLX, Cloud computing, Kubernetes, Technology Advisor, Investor and Co-Founder & Board Member of CoreView. Local AI Ambassador.
Milan, Italy
- Tweets 52,463
- Following 1,576
- Followers 43,254
- Likes 92,060


My position on "MIA's illusion"
Honestly, I really liked how MIA's AI Lab pushed Local AI like crazy and built a strong community around an avatar. But too many things now overshadow the positives:
1 - Using open-source code with unclear or insufficient attribution to its creators.
2 - Taking reach away from everyone else working on AI, especially newer accounts with fewer followers who work hard to earn their audience's trust through real work and passion (see point 1).
3 - ☠️ Selling a book on how to grow on X. This was the worst move, and I really didn't like it. Using an avatar, building a community, growing your audience: all fine. But monetizing those tactics by selling them to the very community you built goes against the basic values a community should have.
4 - Now blocking anyone who criticizes the account or the way it operates. That's the opposite of an open community, where everyone has the right to say what they think, good or bad, for or against.
I hope you'll never see me do anything like this, and if I ever do, please tell me immediately. But I really doubt it, simply because:
- I love Local AI and AI in general.
- I left my startup to go all-in on this world: to play with, study, and live every aspect of this revolution, and to be an active part of its community.
- I love tinkering with hardware and software: Apple, Nvidia, AMD, you name it.
- I'm financially independent, so I'm free to write, say, buy, and play with whatever I want, and I don't need to sell anything to anyone.

They built a 37K cult using a fake avatar to hijack the algorithm. Code never lies and who is actually behind it is revealed inside.
Model credit: @ViC305 & @Blackfrost_ai (not participants).
Read the receipts behind Mia’s AI Lab 👇

1
10
393
Testing @kernelpool PR to make several tool calls per turn in DwarfStar and it works! github.com/antirez/ds4/pull/…
7
17
1,356
I think we should not underestimate OpenAI. I bet they have Astra 6.1 and even more, ready for release.
Probably they were not expecting this big leap of Opus 5.5.
Let’s wait and see.
6
28
2,541
Time is running out!
Context Benchmarks of TensorFold 0.6.3 on M5 Ultra
TensorFold/Qwen3.8-Flash-Next-MLX
oQ4 vs oQ8 (how can it be so fast???)
256K context led to an error, but @ashxhart told me there is no optimizations at all at the moment. He'll start working on it soon!


4
1
25
3,145
Context Benchmark of TensorFold 0.6.3 on M5 Ultra with TensorFold/Qwen3.8-Flash-Next-MLX-oQ8-MTP in progress!
Yes, the 8bit one! Yes it's fast!
32K Peak decode: 154.01, peak prefill: 2985.96

13
2
44
3,306
DwarfStar Qwen3.8-flash-next on Apple M5 Ultra
Here first quick round of optimization mainly focused on Prefill. 100% bit identical.
Nearly 30% better 💪
0.5k pp 1206 tg 88 t/s
1k pp 1673 tg 95 t/s
2k pp 1717 tg 91 t/s
4k pp 2104 tg 88 t/s
8k pp 2452 tg 86 t/s
16k pp 2719 tg 94 t/s
32k pp 3011 tg 90 t/s
64k pp 3043 tg 91 t/s
128k pp 2992 tg 82 t/s
256k pp 2856 tg 81 t/s


Happy like a child! My first Apple M5 Ultra 256GB Context Benchmark of Qwen 3.8 Flash Next q4 coding using DwarfStar! /cc @antirez
No optimizations at all yet, I'll try to do something later and compare! But love the prefill speed here!
Hardware offered by @digitalix 🙏


6
3
24
2,646
Cache hit rate of @pidotdev is really out scale! I love it for local AI development! This is what makes the biggest difference locally! Can't wait to try Pi Durable!
Has anyone tested it yet?
9
63
7,556
MLX engines poll: final results 📊
Video below, audio on!
793 voters, 23 engines. Top 4:
1. oMLX 55.5%
2. MLX-Serve 38.2%
3. LM Studio 31.9%
4. MTPLX 26.0%
LM Studio leads on base M chips, oMLX reaches 71% on Ultras.
Thanks everyone for participating in these! We'll have to do more to start to gather real data and enable community to focus and win big!
Full report: poll.devocracy.it/mlxengines…

11
6
67
4,788
More from the report:
• 58% of you run 2+ engines; oMLX + MLX-Serve is the top pair (21%)
• Typical voter: M5 Max, 128 GB
• TensorFold was added mid-poll and got 6.9% of the voters who saw it 🔥
• MLX VLM and Nativ are counted together
1
1
5
1,024
M5 Ultra is great in prefill, it's really another league there, but on decode the improvement is ok, but not so relevant compared to M3 Ultra.
I'll keep my 2 M3 Ultra 512GB and combined them with 2 M5 Ultra later in 2027 💪
16
3
74
7,878
Claude + Opus 5.5 find their own way to solve problems and limits, here while creating a voice over for a video: "Since I can't listen myself, I'll verify pronunciation by transcribing the clips locally with Whisper on MLX."
9
30
3,445
Welcome in the club! 🚀


1
1
18
2,956
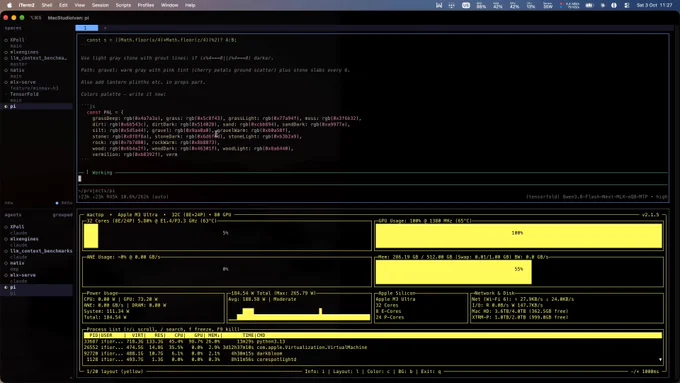
Video of tensorfold running Qwen3.8-Flash-Next-MLX-oQ8-MTP high on M3 Ultra ~80 t/s!
It's a great experience, less errors and better quality. Where possible I suggest to use the highest possible quants!
18
3
81
7,583

M5 Ultra + DwarfStar + pi + qwen3.8-flash-next q4 is working better overall for me. Effort high works well, I see less back and forth during coding and less errors in general. Now I'm optimizing performance, I'll then retry building something with it.
10
2
49
5,247
Ivan Fioravanti retweeted

Both pretty toasty after a heavy AI load.
Top of the Mac Studio: ~50°C
Top of the Sparks: ~48°C
Around the back: 56°C on the Mac's grill, 63°C on the Sparks.


15
6
108
8,385
Ivan Fioravanti retweeted

GLM 5.3 Flash on TensorFold 0.6.2, 2 DGX Sparks:
EXL3 vs MLX 4-bit, same engine, same prompt.
MLX is faster everywhere:
-1 request: 58 vs 43 tok/s
-128K prompt read: 1,179 vs 611 tok/s
-decode after 128K: 48 vs 36 tok/s
-repeat 64K prompt: 0.13 vs 0.15s
But EXL3 built the better island. Zero fixes. MLX needed 2 and still has a black island.
One run each, thinking on. Both 8/8 byte-identical solo vs 16 at once.

16
7
66
6,952
Hey Rust are you ready?
Swift is coming for you 🫵

Google: “[Swift] has matured into a viable systems and cloud language, pairing Rust-like data-race safety with predictable, reference-counted performance.” Announcing their Swift-based cloud SDK for backend services: cloud.google.com/blog/topics…
13
11
297
33,522