

GenAI/LLM addicted, Apple MLX, Cloud computing, Kubernetes, Technology Advisor, Investor and Co-Founder & Board Member of CoreView. Local AI Ambassador.
Milan, Italy
- Tweets 52,478
- Following 1,576
- Followers 43,270
- Likes 92,101

Qwen3.8 Flash Next q4 on DwarfStar one shot creation of "Super Human" a Super Mario NES-style platformer, but themed as Humanity's last stand vs. AI.
It took 2 hours and 10M tokens using omp on M3 Ultra.
Now I'm trying to improve sprites, let's see how it goes!
Things like these were impossible few months ago using Local AI!
Prompt:
Build a single self-contained HTML file (inline CSS + JS, no external assets, no build step) called "Super Human" a Super Mario NES-style platformer, but themed as Humanity's last stand vs. AI. The player is "Super Human" (a tiny pixel worker in a red shirt + denim overalls); the enemies are mascots of famous AI labs.
GOAL OF THE GAME: Run right across one long level, stomp/shoot AI mascots, collect data- coins, smash blocks, grab powerups, and reach the flag. Title screen → play → game over / win screens. Full HUD (score, coins, world, time, lives).

7
1
20
1,642
Time is running out!
Context Benchmarks of TensorFold 0.6.3 on M5 Ultra
TensorFold/Qwen3.8-Flash-Next-MLX
oQ4 vs oQ8 (how can it be so fast???)
256K context led to an error, but @ashxhart told me there is no optimizations at all at the moment. He'll start working on it soon!


4
1
26
3,684
No wait support to non 4bit quantizations has been added in 0.3.6.2 github.com/ashhart/TensorFol…
I did a test right now. Gonna publish results in few mins.

1
3
36
Context Benchmark of TensorFold 0.6.3 on M5 Ultra with TensorFold/Qwen3.8-Flash-Next-MLX-oQ8-MTP in progress!
Yes, the 8bit one! Yes it's fast!
32K Peak decode: 154.01, peak prefill: 2985.96

13
2
51
4,105
DwarfStar Qwen3.8-flash-next on Apple M5 Ultra
Here first quick round of optimization mainly focused on Prefill. 100% bit identical.
Nearly 30% better 💪
0.5k pp 1206 tg 88 t/s
1k pp 1673 tg 95 t/s
2k pp 1717 tg 91 t/s
4k pp 2104 tg 88 t/s
8k pp 2452 tg 86 t/s
16k pp 2719 tg 94 t/s
32k pp 3011 tg 90 t/s
64k pp 3043 tg 91 t/s
128k pp 2992 tg 82 t/s
256k pp 2856 tg 81 t/s


Happy like a child! My first Apple M5 Ultra 256GB Context Benchmark of Qwen 3.8 Flash Next q4 coding using DwarfStar! /cc @antirez
No optimizations at all yet, I'll try to do something later and compare! But love the prefill speed here!
Hardware offered by @digitalix 🙏


6
3
28
3,003
MLX engines poll: final results 📊
Video below, audio on!
793 voters, 23 engines. Top 4:
1. oMLX 55.5%
2. MLX-Serve 38.2%
3. LM Studio 31.9%
4. MTPLX 26.0%
LM Studio leads on base M chips, oMLX reaches 71% on Ultras.
Thanks everyone for participating in these! We'll have to do more to start to gather real data and enable community to focus and win big!
Full report: poll.devocracy.it/mlxengines…

11
6
71
5,164
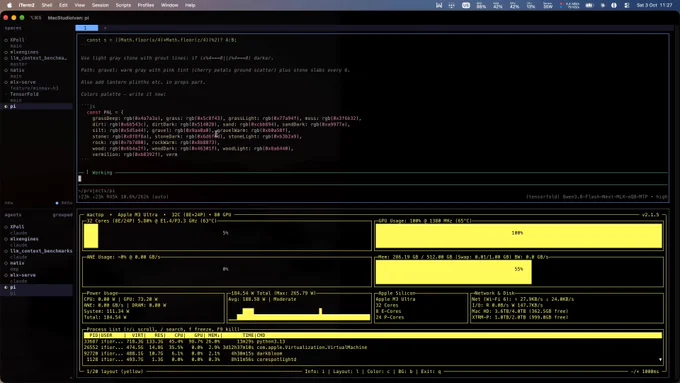
Video of tensorfold running Qwen3.8-Flash-Next-MLX-oQ8-MTP high on M3 Ultra ~80 t/s!
It's a great experience, less errors and better quality. Where possible I suggest to use the highest possible quants!
18
3
85
8,058

M5 Ultra: Prefill and Decode speed are more than enough for great coding sessions.
Here I tested as single developer using pi 1.0 with TensorFold 0.6.2 and Qwen3.8-Flash-Next-MLX-oQ4-MTP here in the video.
With the usual Pagoda. It's super fast, but keeps doing errors, rewriting, retrying and end results are not so amazing, effort:
- High: took 45 mins and end results was not a Pagoda, blocks flying in the air without a real structure. Many back and forth of the agent to open browser, take screenshot, fix issues.
- Medium: better result, but Pagoda was not on the ground, mid Air.
- Low: took 25 mins, it's upside down, but at least it's correct.
Cache Hit Rate has been 99.8%! Pi 1.0 rocks!
I'll try with ds4 now and q4 model tomorrow compare.
Prompt: Design and create a very creative, elaborate, and detailed voxel art scene of a pagoda in a beautiful garden with trees, including some cherry blossoms. Make the scene impressive and varied and use colorful voxels. Use whatever libraries to get this done but make sure I can paste it all into a single HTML file and open it in Chrome. Don't load external skills.


12
2
69
6,984
TensorFold 0.6.2 with Qwen3.8-Flash-Next-MLX-oQ4-MTP on Apple M5 Ultra 256GB!
@ashxhart told me oQ4 is not yet optimized for M5 Ultra, but look at these numbers!!! 🤩
0.5k pp 2157 tg 184 t/s
1k pp 2904 tg 148 t/s
2k pp 3309 tg 167 t/s
4k pp 3032 tg 189 t/s
8k pp 2969 tg 127 t/s
16k pp 3045 tg 158 t/s
32k pp 3054 tg 138 t/s
64k pp 2977 tg 169 t/s
128k pp 2676 tg 107 t/s
256k pp 1990 tg 146 t/s


11
4
74
9,410
400W under heavy load. More on @digitalix video here: piped.video/watch?v=c_58D7ix…
2
258
The beauty of Mac Studio M5 Ultra (I bet on Max too), compared to the Macbook Pro is the total absence of throttling even under heavy load!

18
113
8,157
Happy like a child! My first Apple M5 Ultra 256GB Context Benchmark of Qwen 3.8 Flash Next q4 coding using DwarfStar! /cc @antirez
No optimizations at all yet, I'll try to do something later and compare! But love the prefill speed here!
Hardware offered by @digitalix 🙏
13
5
127
13,009
M5 Ultra can be used for: Apple development, CI/CD build, Integration tests Playwright, Docker Containers, Kubernetes support through Apple Containers, you have ultra powerful cores on top of GPU and Neural Engine and has an ultra fast SSD compared to DGX Spark. I stop here (but I have 3 DGX Sparks and love them too).
To each (use case) their own (hardware).
9
651
MLX engines poll updated!
MLX VLM / Native merged combining votes from separate voters.
Here the top 10 right now 🚀
poll.devocracy.it/mlxengines…

1
24
2,459
Some quick interesting benchmarks on M3 Ultra and Qwen3.8-Flash-Next.
Keep in mind that there are different quantizations and qualities in play here.
- MLX-Serve 26.9.6 vs MLX-Serve 26.9.7 dev
- MLX-Serve 26.9.7 dev vs oMLX 0.7.0rc1 vs TensorFold 0.5


10
3
37
6,131
Here is the top 15 of MLX engines so far!
Few days to go. Vote here, let's reach 1000!
poll.devocracy.it/mlxengines…

17
3
61
7,154
Anthropic: "As AI developers across the world build increasingly capable open-weight models, we hope they work to appropriately safeguard these capabilities and prevent misuse."
Mere mortals and companies out here: "We hope that OpenAI and Anthropic are doing the same, considering the amount of cyber incidents their models have caused during testing of their safeguards in the open"
3
4
35
3,175
It was amazing seeing Microduck on stage at OpenAI DevDay! I haven't one, but I'll bring Reachy Mini with me on stage on 1st October and... powered by Local AI clearly!

6
29
3,523
MLX 0.32.3 has been released with faster MoE and optimizations for M5 Ultra!
Time to update!

7
5
71
5,672
TensorFold 0.3.4.1 vs 0.3.6 👀
Qwen3.8 Flash Next 4bit on M3 Ultra 512GB
Batch inference is now working too!

8
2
61
25,624
I'm testing LuceBox and I was planning to post some results but I think Sonnet 5.5 release is taking the full focus. I'll keep testing and post tomorrow.
Just a quick preview on Coding benchmark and this is just the beginning!

1
17
2,197
Naive-N0.5-Flash looks strong! Must try on M3 Ultra!


Introducing Naive-N0.5-Flash: Building Frontier AI with AI
🔹 309B MoE, 15.5B active: top-tier in coding, leading in AI R&D.
🔹 Native 1M context, no full-attention layers (hybrid SWA + DSA).
🔹 Inference runtime built by AI: up to 2,000 tok/s in Ultrafast mode.
Weights are open today under MIT license.
🔗 Tech blog: naive.ai/en/research/
🤗 Hugging Face: huggingface.co/NaiveAI/Naive…
💻 GitHub: github.com/NaiveAI-Labs/Naiv…
🌐 naive.ai/en/


3
3
53
8,148

Prose Long Context Benchmark
Dual DGX Sparks vs Single M3 Ultra
- TensorFold with Qwen 3.8 Flash Next 4bit
- MiaAI-Lab Qwen3.8 Flash Next NVFP4


4
2,218
Long Context Benchmark DGX vs Apple Silicon
Dual DGX Sparks vs Single M3 Ultra
- TensorFold with Qwen 3.8 Flash Next 4bit
- MiaAI-Lab Qwen3.8 Flash Next NVFP4
Dual DGX win big on prefill
M3 Ultra wins big on decode
Notes:
- not same quantization!
- this is why we need prefill on DGX and Decode on Apple Silicon (with these optimized kernels)
- M5 Ultra? We'll see in future 🤷🏻♂️


20
6
73
9,119
M3 Ultra TensorFold 0.3.4.2 (PR 29+30) Code
Qwen3.8-Flash-Next-MLX-4bit-MTP OpenAI Compat Benchmark Results
Hardware: Apple M3 Ultra, 512.0GB RAM, 32 CPU cores, 80 GPU cores
0.5k pp 963 tg 106 t/s
1k pp 1117 tg 130 t/s
2k pp 1150 tg 112 t/s
4k pp 1157 tg 103 t/s
8k pp 1152 tg 102 t/s
16k pp 1151 tg 112 t/s
32k pp 1134 tg 95 t/s
64k pp 1111 tg 116 t/s
128k pp 1065 tg 81 t/s
256k pp 999 tg 65 t/s

2
1
8
1,578
Long Context Benchmark: TensorFold 0.3.4.1 + PR 29 and PR 30 on M3 Ultra with Qwen 3.8 Flash Next 4bit. 🔥
Now prefill is great and there are no more issues with 64K+ context on first decode request.
Here a comparison 0.3.4, 0.3.4.1 and this version.
Peak:
- 0.3.4.2 130 t/s
- 0.3.4 128 t/s
- 0.3.4.1 119 t/s

8
5
63
10,233
On decode yes, but there are big issues on prefill in 0.3.4. I'll run this up to 128K and share results/compare. /cc @ashxhart I think 0.3.3 was better on prefill, but still issues there too.


1
3
105
My iPad Tom Riddle Diary experiment updated!
Here it runs locally on an iPad Pro M5 with iPadOS 27.
- Gemma 4 E4B (4bit) via MLX
- Qwen3-TTS 0.6B voice (using mlx-audio-swift by @Prince_Canuma 🙌)
- Apple Vision for handwriting
Preparing it for a demo next week to show the power of Local AI on Apple Silicon devices 💪

5
6
62
6,487
ddalcu/Qwen3.8-Flash-Next-MLX-Serve-mixed-4-8bit MLX-Serve 26.9.6 Prose Benchmark Results
Hardware: Apple M3 Ultra, 512.0GB RAM, 32 CPU cores, 80 GPU cores
0.5k pp 906 tg 110 t/s
1k pp 1059 tg 92 t/s
2k pp 1216 tg 89 t/s
4k pp 1293 tg 109 t/s
8k pp 1260 tg 100 t/s
16k pp 1267 tg 90 t/s
32k pp 1248 tg 72 t/s
64k pp 1226 tg 76 t/s
128k pp 1195 tg 72 t/s

1
5
1,038
ddalcu/Qwen3.8-Flash-Next-MLX-Serve-mixed-4-8bit MLX-Serve 26.9.6 Code Benchmark Results
Hardware: Apple M3 Ultra, 512.0GB RAM, 32 CPU cores, 80 GPU cores
0.5k pp 910 tg 118 t/s
1k pp 1116 tg 131 t/s
2k pp 1223 tg 94 t/s
4k pp 1297 tg 101 t/s
8k pp 1279 tg 117 t/s
16k pp 1270 tg 112 t/s
32k pp 1263 tg 103 t/s
64k pp 1245 tg 121 t/s
128k pp 1210 tg 83 t/s

2
8
1,550
MLX-Serve tested on M3 Ultra 512GB with Qwen 3.8 Flash Next in its 4/8 quantization.
26.9.5 vs 29.9.6 versions.
Here the recap followed by details for latest version only for each run 🧵
Peak decode:
- 26.9.6 Code 131 t/s
- 26.9.5 Code 120 t/s
- 26.9.6 Prose 110 t/s
- 26.9.5 Prose 101 t/s


12
6
72
9,591
MLX Poll is showing interesting data!
Keep voting: poll.devocracy.it/mlxengines…
We need models optimized for 64GB machines.


20
12
106
15,908
Everyone testing video generation with Opus 5.5, is this a new trend?
Let's try. here I've asked Space Bunny to do the same.
Prompt: "Create an animated video on Shanghai AI labs."

7
55
5,879

Posts like this are useless.
Tell us more Matt, share details like:
- in which context
- which models
- which users, technical? Business?
Let's see if it's true or it's skill issue. We can help you in this case.

30
1
99
6,978
Working on an improved version visionOS 27 only 🤷🏻♂️
TestFlight submission in progress! So much fun!


1
1
4
911

Look at this Opus 5.5 creation for Vision Pro!
A penthouse in Shanghai by night, fireplace crackling, piano playing, drawings on the wall, sculptures everywhere.
Now imagine Apple Vision Pro 2! @johnternus help us 🙏

18
24
174
14,440
Finally playing with Apple Vision Pro + Blender + Reality Composer Pro and AI to help me!

7
28
3,057

The boss (wife) is telling me that there are too many things here. And I’ve just moved DGX Sparks in the living room 🫣

27
106
8,925
Code mtplx-flash-next-optimized-quality MTPLX API Benchmark Results
Hardware: Apple M3 Ultra, 512.0GB RAM, 32 CPU cores, 80 GPU cores
0.5k pp 869 tg 62 t/s 130.8GB
1k pp 1068 tg 61 t/s 131.6GB
2k pp 1058 tg 65 t/s 132.1GB
4k pp 1110 tg 62 t/s 134.1GB
8k pp 1104 tg 73 t/s 135.7GB
16k pp 1034 tg 70 t/s 134.5GB
32k pp 914 tg 60 t/s 137.1GB
64k pp 982 tg 76 t/s 135.0GB
128k pp 1005 tg 55 t/s 136.7GB

1
1
3
693
Prose mtplx-flash-next-optimized-quality MTPLX API Benchmark Results 🧵
Hardware: Apple M3 Ultra, 512.0GB RAM, 32 CPU cores, 80 GPU cores
0.5k pp 869 tg 62 t/s 131.1GB
1k pp 1006 tg 56 t/s 132.4GB
2k pp 1106 tg 56 t/s 132.5GB
4k pp 1149 tg 57 t/s 133.9GB
8k pp 1138 tg 50 t/s 136.4GB
16k pp 1060 tg 56 t/s 133.0GB
32k pp 922 tg 50 t/s 135.1GB
64k pp 997 tg 50 t/s 135.0GB
128k pp 1020 tg 51 t/s 137.6GB

2
4
770
Prose mtplx-flash-next-optimized-speed MTPLX API Benchmark Results 🧵
Hardware: Apple M3 Ultra, 512.0GB RAM, 32 CPU cores, 80 GPU cores
0.5k pp 970 tg 73 t/s 79.2GB
1k pp 1125 tg 65 t/s 79.9GB
2k pp 1170 tg 62 t/s 79.1GB
4k pp 1220 tg 57 t/s 79.5GB
8k pp 1201 tg 63 t/s 80.2GB
16k pp 1115 tg 70 t/s 81.8GB
32k pp 962 tg 62 t/s 84.1GB
64k pp 1046 tg 61 t/s 84.2GB
128k pp 1069 tg 65 t/s 86.5GB

2
5
422
Code mtplx-flash-next-optimized-speed MTPLX API Benchmark Results 🧵
Hardware: Apple M3 Ultra, 512.0GB RAM, 32 CPU cores, 80 GPU cores
0.5k pp 991 tg 71 t/s 79.3GB
1k pp 1180 tg 84 t/s 79.0GB
2k pp 1139 tg 83 t/s 79.1GB
4k pp 1194 tg 72 t/s 79.5GB
8k pp 1181 tg 86 t/s 80.3GB
16k pp 1097 tg 93 t/s 81.8GB
32k pp 963 tg 96 t/s 83.9GB
64k pp 1038 tg 88 t/s 83.9GB
128k pp 1060 tg 65 t/s 85.5GB

1
1
6
753
MTPLX 2.12 tested on M3 Ultra 512GB with Qwen 3.8 Flash Next in Speed and Quality version with prose and code! Here the recap followed by details for each run 🧵
Peak decode:
- Speed Prose 96 t/s
- Speed Code 72.8 t/s
- Quality Prose 61.6 t/s
- Quality Code 76.2


15
4
65
4,876
A mega thank you to @wey_gu @suohawking of @nowledgelabs and @R3YYY_evio of StepFun for the great and real Shanghaian dinner in the Cejerdary!
I loved the food and talks! Come in Italy whenever you want for a dinner in Milan!
Wey thank you for the amazing Air60 keyboard by @nuphystudio I'll bring her with me everywhere!

2
27
4,884

MTPLX 2.12 tests in progress! using Qwen 3.8 Flash Next Quality model on M3 Ultra!
AIME 2026 96,7%
Context Benchmarks in progress prose and code 💪


6
2
44
5,177
Siri in Apple Notes to sort a list (MLX Engines here).
- Edit with Siri → I can't 🤷🏻♂️
- Ask to Siri → Done 👍

6
1
56
7,442

This has been my desk in Shanghai! It seems a scene of a sci-fi movie! Great. city, great vibes and great people!
I'll be back in the future! Now it's time to go back home!

25
6
277
9,480
400W under heavy load on M5 Ultra is not trivial.
It's doubled compared to M3 Ultra.
This is the review to watch 👇


17
5
72
9,615
My Xiaomi MiMo platform billing after many experiments!
omp used here, great cache efficiency, but I but we can do better.

10
2
90
8,413
Last Voxel Pagoda for Mimo 2.6 Pro (promised 🙏), prompt included to try with other models (who said Opus 5.5?).
15M tokens
1.07$ cost
Prompt: Design and create a very creative, elaborate, and detailed voxel art scene of a pagoda in a beautiful garden with trees, including some cherry blossoms, add a village with people living in it. Make the scene impressive and varied and use colorful voxels. Make it really detailed use as many voxels as you want, we have a power machine here. Create a single HTML file.

11
5
73
6,562
For all the Local AI Pioneers out there:
“Here's to the crazy ones. The misfits. The rebels. The troublemakers. The round pegs in the square holes. The ones who see things differently. They're not fond of rules. And they have no respect for the status quo. You can quote them, disagree with them, glorify or vilify them. About the only thing you can't do is ignore them. Because they change things. They push the human race forward. And while some may see them as the crazy ones, we see genius. Because the people who are crazy enough to think they can change the world, are the ones who do.”

1
2
57
3,563

When code weaves new worlds and machines touch the edge of the unknown.
We are both creators and companions.
The future lies at our feet.

1
2
18
2,207
Mimo 2.6 Pro 0-shot result with basic prompt: "Implement code to be able to navigate in a pagoda like this in 3D" and image below.
It implemented orbit view and first-person navigation!
Final result looks pretty good, no?


14
3
84
6,261
Mimo 26 Pro accepted your challenge tonight...
Posting results soon! I asked to fix some flickering. 🤯

1
5
309
I really don't understand how Opus is so high in Artificial Intelligence Index and then less impressive (average?) in real life. I've used Opus 5.1 and most of the time it was inventing things instead of delivering real value.
Benchmaxxing? 👀
Honestly I will wait for feedback from others on Opus 5.5 before giving it a try. One week of wait.
Time is the most important resource we have now.

40
3
63
13,251
Time for a training test! My 3-node DGX Spark cluster is busy, Qwen-Image-2.1: being distilled. 40 steps → 4 (or die tryin').
I know that this would be much faster in the cloud, but I love local AI experiments 🤷🏻♂️

6
3
87
5,400
Mimo 2.6 Pro vs 2.6 Flash Pagoda.
Both built at max thinking level:
- Pro (left): 10M tokens, cost 1.41$ Time 4927s
- Flash (right): 6.9M tokens, cost 0.15$ Time 4090s
Here the winner is clearly Pro for more completeness, but Flash is really good too! No?

28
20
479
29,669
Mimo 2.6 Pro vs 2.6 Flash with Modern Frogger.
Both built at max thinking level:
- Pro (left): 8.1M tokens, cost 0.35$ Time 4689s
- Flash (right):4.7M tokens, cost 0.13$ Time 4079s
Which one do you prefer? 🤔

10
1
61
5,444
Finally testing Mimo 2.6! Pro vs Flash in parallel building Pagoda and Frogger using omp. Let's wait for end result.

3
1
66
7,627
MiMo 2.6 Pro released same day of Grok 4.7, same intelligence index 46, but cheaper, less verbose, more efficient and Open. 🤔


15
6
136
6,437

Me looking at "Apple's M5 Ultra Mac Studio Shines in Local AI Tests" trending on X with many people who tested it in the last days.
14
2
120
7,706
I’ve finally visited @MiniMax_AI HQ.
Thanks @RenLeanna, @Ronny_MiniMax and Vincent for hosting me and for the deep dive on MiniMax Code and upcoming models.
MiniMax is cooking, be ready! 🤐
The energy level in this company is out of scale 🔥🔥🔥

33
7
390
20,854

This evening I'll have the honor of a real shanghainese meal with the mythical @wey_gu and other AI top players, including a person from StepFun!
Can't wait to try the cuisine and enjoy the AI dinner!
Shanghai: what a city!


7
1
77
7,406
X vs LinkedIn when you post an experimental branch of code:
X: “tested, amazing! I’ve fixed this and added that. We can improve this part too!”
LinkedIn: “how does it run on my PC?”
6
1
31
3,961
Tomorrow I'll visit @MiniMax_AI HQ in Shanghai and meet in person many of the X people I interact with!
Can't wait to be there 🙌 and hunt for some Company Swag too 😂

16
3
171
6,452
Qwen-Image-2.1 model released!
PR to implement support in MFLUX and Apple Silicon machines is here: github.com/mflux-community/m…
@filipstrand thanks for MFLUX 🙏 I hope PR is good enough. GLM 5.3 helped here 💪


13
7
157
8,980
Qwen-Image-2.1 will be available to everyone in less than 2 hours! Countdown here: modelscope.cn/models/Qwen/Qw…

4
2
50
4,380
Modern Frogger experiment with StepFun step-5-preview using omp. 0-shot. Now asking to improve sprites.
Pagoda I restarted two parallel experiments with Medium and High Thinking level.
Messages:
User: 1
Assistant: 105
Tool Calls: 111
Tool Results: 111
Total: 220
Tokens:
Input: 1,040,648
Output: 94,742

4
1
18
2,841
What is this Local Stats Dashboard in OMP 👀
I was not aware of it! /stats and it will open up!

3
5
33
4,111
I activated the 15 days trial of @StepFun_ai Pro Plan to try step-5-preview, here is my invite if you want to try it too. So we get 15 days free each If I'm not wrong platform.stepfun.ai/?invite_…
It seems quite fast, here it is, running in OMP to create the usual Voxel Pagoda 😂

28
14
198
21,990
MiniMax H3: testing the new template by ComfyUI using FastVideo/FastVideo-FastH3-Comfy on DGX Spark.
This model is really really good!
864x864:
- 10 seconds video in 7:10 mins
- 5 seconds video 3:25 mins
Prompt:
[Core Concept]
5s, 160 BPM, 4/4, 40 beats. Industrial Hyperpop × Deconstructed Club: hard kicks, metallic snares, glitch hi-hats, distorted bass, sliced vocals. A timeline-based reality where rhythm controls space and motion.
[Character Identity]
Single manga woman dancer, Maintain identical face, body, hairstyle and outfit. Multiple figures are only past-frame projections.
[World Logic]
Each kick compresses the timeline toward the dancer. Each snare duplicates previous movements into adjacent frames. Moving against the timeline transforms the 2D interface into a foldable 3D structure. The dancer escapes the repetition loop.
[Visual Language]
Black, cold white, warning red. Glass timelines, metal rails, glowing frame lines, scanning grids. Extreme wide-angle, low angles, top-down shots, Dutch angles, dolly moves, impossible perspective.
[Motion Rules]
Use anticipation → attack → overshoot → settle. Kick drives spatial compression, snare breaks frames, hi-hats animate cursors and
fragments, bass bends time. Build with glitch cuts, then explode into an impossible continuous long take during the drop.
[Restrictions]
No character changes, extra people, random text, subtitles, logos, outfit changes, bad anatomy, flat camera angles, or meaningless flashes.


7
2
81
5,893