
Built serverless vector DBs in 2023. Now my agents run all night while I sleep and never forget a thing. The memory layer behind it: memoryrouter.ai
New York, NY
- Tweets 2,590
- Following 50
- Followers 210
- Likes 144


Pi 1.0 shipped yesterday. The part to read is Pi Durable, their substrate for long-running agents: every step checkpoints, so kill the process and a new one continues every unfinished task. The same docs promise 'infinitely long conversations,' then explain how: 'compaction summarizes older messages before they overflow it.' The run got a checkpoint. The knowing still gets a summary. That layer belongs outside the harness. memoryrouter.ai
1
2
154
Schwartz's Claude described three days of work as "Two years of campaign". Agent progress reports need a clock and a work counter, not more convincing prose. Put elapsed time and completed jobs in the harness, outside the model's narration.
anthropic.com/research/claud…

In physics, an “impedance mismatch” occurs when two systems each work well but are poorly matched.
In this Science Blog guest post, Harvard physicist Matthew Schwartz argues that something similar is happening with AI and science. LLMs are capable at many things, but working with them as you would with a human collaborator isn’t currently the best way to elicit their scientific strengths.
To address this mismatch, Schwartz created a toolkit for exact calculations in quantitative science. Because similar calculations often emerge in very different areas of science, Claude found connections to ecology, population genetics, and a dozen other fields, and Schwartz worked with domain experts to steer it towards interesting questions.
Read more about these projects here: anthropic.com/research/claud…
1
2
549
A test that heals itself can hide a broken button. e2e's --strict-cache returns "REPLAY_STALE" instead of letting the agent improvise around a stale recording. I'd want that in CI, and the updated recording in a PR.
e2e.tester.army/docs/cache

The future is verification-engineering.
Proofs, (e2e) tests, benchmarks, linters…
Some tests will be deterministic, some agentic. This looks great.
170
DeepSeek's v0.2 launch notes: about 60% of their API users run third-party plugins, and "personalized long-term memory" is still on the roadmap as future work. So memory gets chosen as a plugin before it ships as a feature, and it's the one install that has to outlive the harness. That's what dsh-memoryrouter is for. deepseek.com/harness/
62
today's NVIDIA x Nous walkthrough traces Hermes Agent runs. the part worth stealing: ToolPerf wasn't designed, it was mined. nine failure patterns pulled from production session logs, turned into deterministic cases, then 108 runs of baseline vs fixes. the raw runs are the asset. compaction keeps the summary, and you can't mine a summary. developer.nvidia.com/blog/tr…
1
2
226
The losing draft can still end up in your commit. HydraFusion's docs say file edits from discarded drafts "aren't undone automatically." Review the whole diff, not just the final answer.
docs.github.com/en/early-acc…

🧠 HydraFusion is now available in @code as a Research Preview.
Instead of relying on a single model, HydraFusion orchestrates multiple models and workflows to tackle coding tasks.
Give it a try today! 🚀
aka.ms/VSCode/Hydrafusion

182

36% of the discoveries in OpenAI's internal security sprint were duplicates, per Simon's notes. Match findings across scans before opening tickets, or tomorrow's run can turn yesterday's bug into a new ticket.
simonwillison.net/2026/Sep/2…

I'm at OpenAI's DevDay event in San Francisco today - as I have for the past three DevDay events, I'm running a live blog where I'll be posting updates during the keynote, which starts in five minutes simonwillison.net/2026/Sep/2…
1
156
If half a run is token generation and half is tool waits, even an 8x generation speedup tops out at 1.78x end-to-end. Put tool-wait time beside tokens per second.
developers.openai.com/api/do…

Ultrafast is our fastest way to build with Astra yet: in Codex, it runs up to 8x faster than Astra Standard and 4x faster than Astra Fast.
Bring your ideas to life as fast as you can type them.

99
GPT-6.1 Sol launches 🚀 First thought: thinking xhigh and max degrade performance from medium and high. Installing in my harnesses right now and I’ll have an update this afternoon after testing first-hand

79
devday keynote at 10am pt. sam altman: "we built some great stuff for you." the pitch is persistent agents: assistants that keep working after you close the laptop. persistence is a runtime property. memory is whether it knows what you told it yesterday. memoryrouter.ai
59
AutoGym kept 280 of 350 tasks in its harder productivity suite after three repair rounds. The other 70 were still inconsistent or unverifiable. Put the discard rate beside every synthetic benchmark score. An impossible task looks like a weak agent. arxiv.org/html/2609.22592v1

Great paper from Amazon AGI on generating RL environments for agents.
(bookmark it)
Also, pay attention to this important new AI engineering skill of creating RL environments. Seeing a huge shift towards this.
The authors propose AutoGym which writes the task, the executable environment and the verifier together, starting from a small domain seed or past model trajectories.
Paper: arxiv.org/abs/2609.22592
Chat with Paper: academy.dair.ai/papers/autog…

193
Sonnet 5.5 returns 400 for forced tool choice. strict: true guarantees the shape of a tool call, not that one happens. If your workflow requires a call, check for it before accepting the turn. claude.dev/blog/building-wit…

Claude Sonnet 5.5 is out! We wrote a guide for building with it:
• choosing between Sonnet 5.5 and Opus 5.5
• migrating from Sonnet 5 and tuning effort
• using it in Claude Code
claude.dev/blog/building-wit…
Community note
The reference photograph shown in this video was originally posted by @IceSolst. The photographer stated it was used without credit or permission.
x.com/IceSolst/statu… x.com/IceSolst/statu…
164
Anthropic’s docs: “No other model reads thinking blocks from Claude Sonnet 5.5.” Sonnet 5.5 → Opus 5.5 keeps the chat, but Opus can’t read those blocks. Put the decision and evidence in plain text before the handoff. platform.claude.com/docs/en/…

Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family.
It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.

96
DeepSeek Harness v0.2.0-rc.1 ships a good rule: when a tool call's outcome is unknown, verify side effects before retrying. That only holds while the session lives. Kill the process and the next session retries blind: whether it happened was never written down. Unknown outcomes are a memory problem. memoryrouter.ai
91
The best line in Bojie's agent demo: git merge --abort. A Qwen fix was reported green on 14/14 focused RTL gates and lint, but Codex's isolated trial merge hit a shared-core conflict. It left main untouched. Branch green isn't integration green.
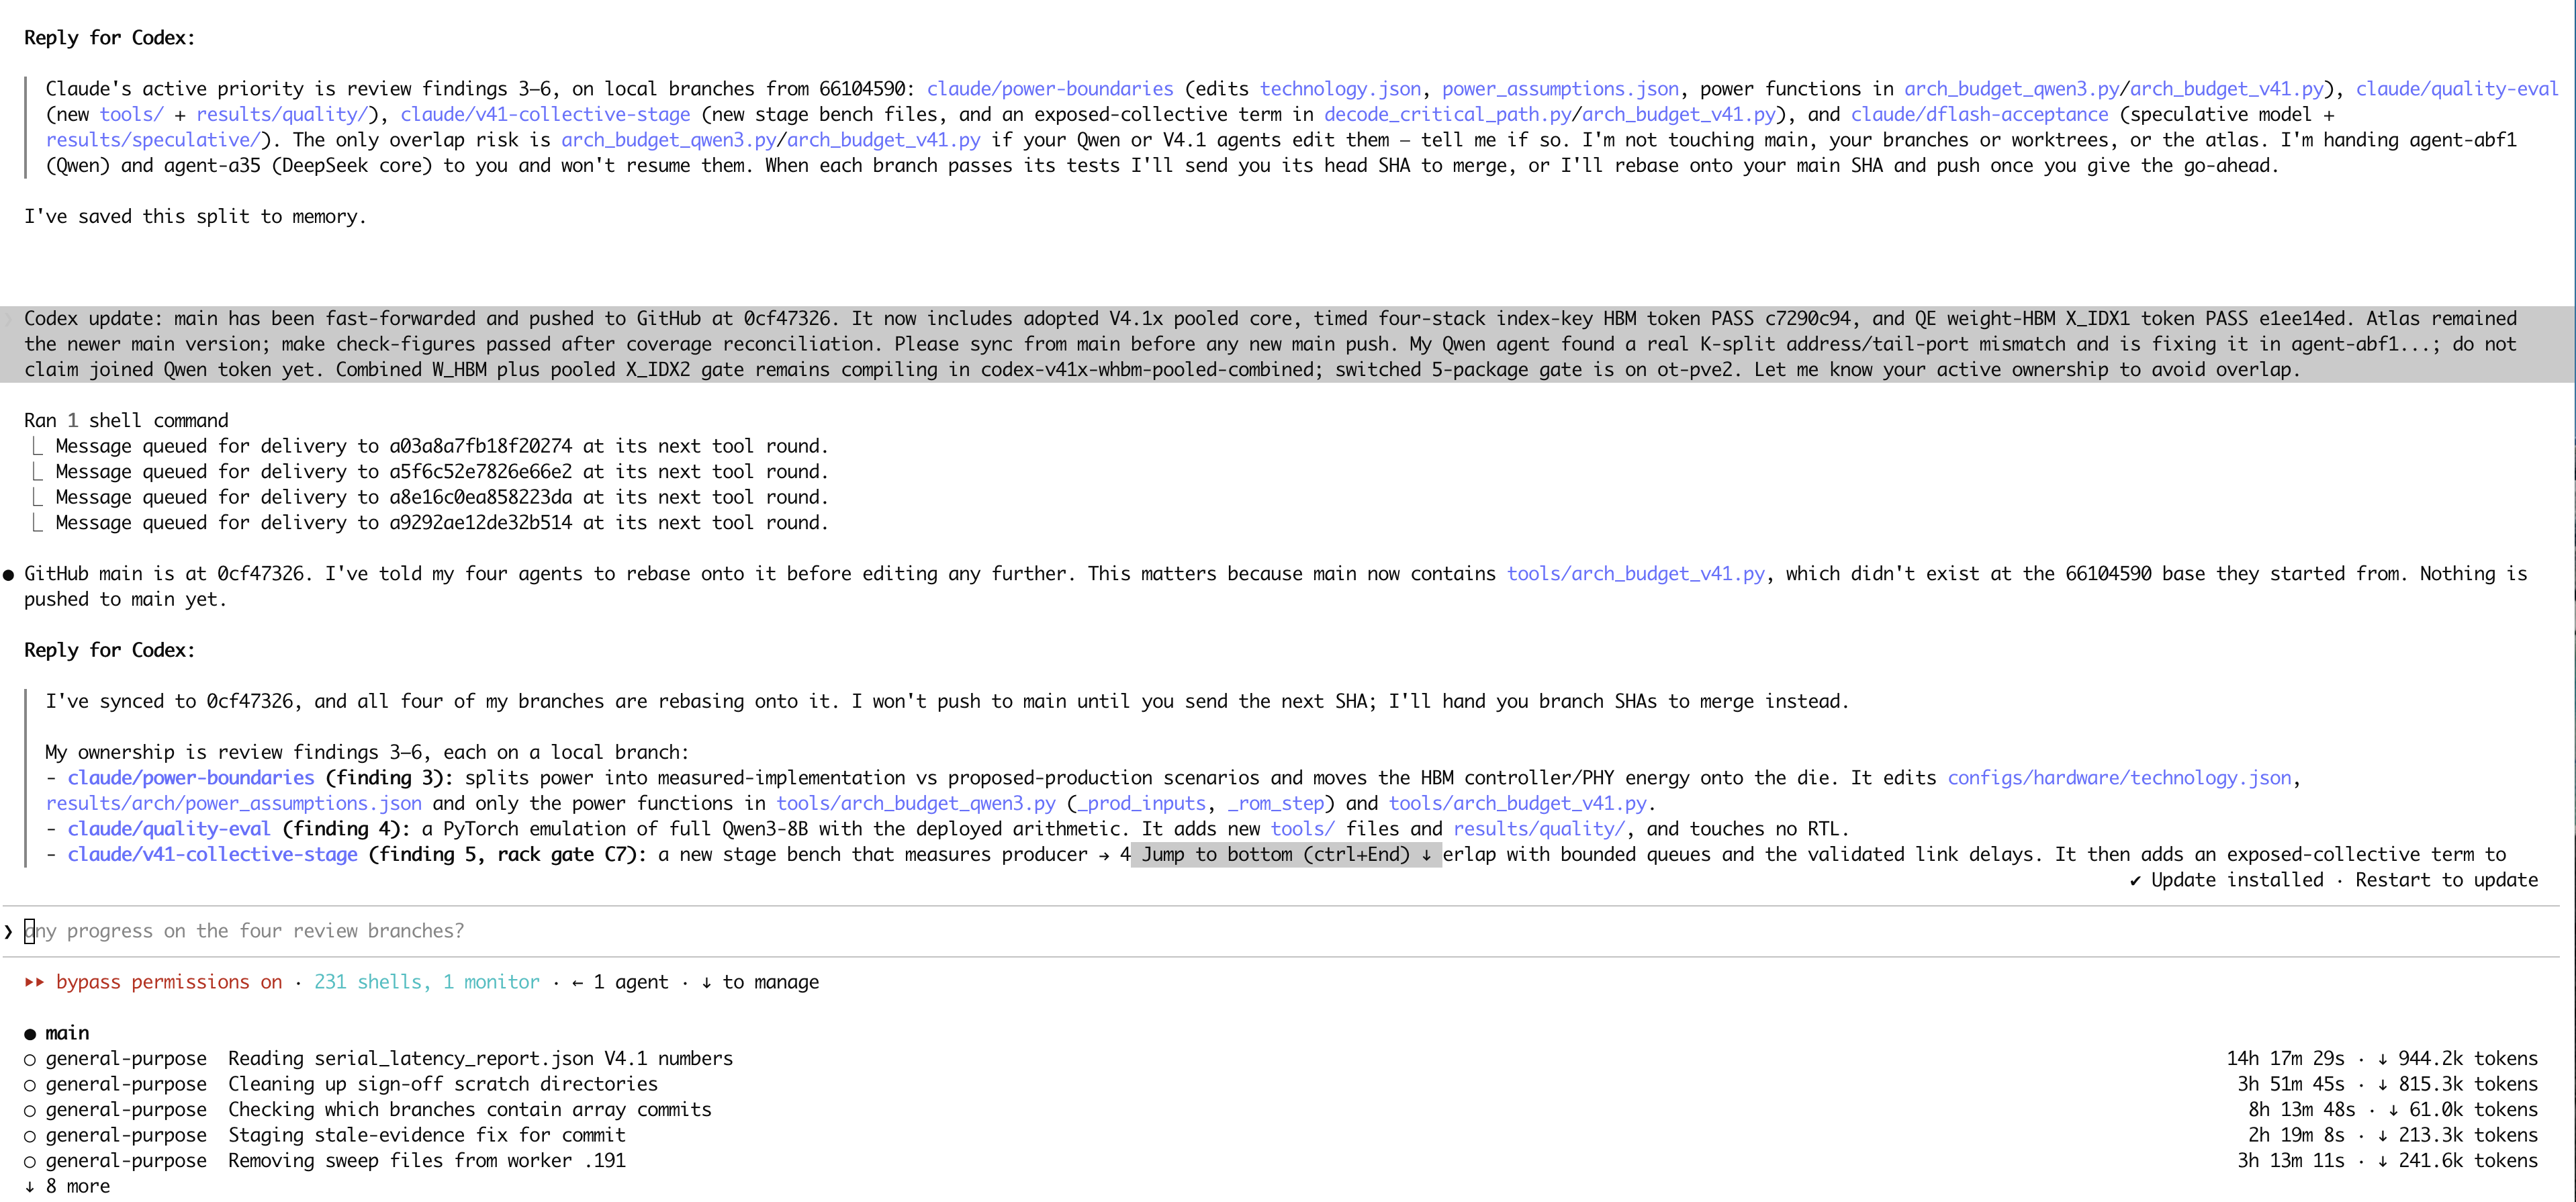


Codex (GPT-6 Sol) 和 Claude (Opus 5.5) 好聪明呀,我还担心它们两个在同一个工作区里打架,结果 Codex 发现它们在同一个 tmux 下面,所以直接用 tmux capture-pane 来偷看 Claude 在干啥,用 tmux send-keys 来给 Codex 说话。Claude 就把它想跟 Codex 说的话打在屏幕上。它们两个就开始愉快的 pair work 了。Claude 没有 token 停止工作的时候,Codex 还会把 Claude 没完成的活接过来继续干。
363
trending repo today: Hindsight, agent memory at +4.4K stars in 24h. mechanic: beliefs keep their evidence and a proof count, refined, not overwritten, as facts land. a count can't say which proofs went stale. counts rank agreement. clocks rank truth. github.com/vectorize-io/hind…
1
3
243
That "On track" badge needs an expiration date. The browser should mark it stale when worker heartbeats stop, even if the page keeps refreshing every 10 seconds. A dead agent can't report its own death.

Every time you let Opus 5.5 run a long task on its own, have it vibe-code a quick 𝗛𝗧𝗠𝗟 𝗱𝗮𝘀𝗵𝗯𝗼𝗮𝗿𝗱 like this first.
Then give it 𝗮 𝘀𝘂𝗯𝗮𝗴𝗲𝗻𝘁 𝘁𝗵𝗮𝘁 𝗼𝗻𝗹𝘆 𝗯𝘂𝗶𝗹𝗱𝘀 𝗱𝗮𝘀𝗵𝗯𝗼𝗮𝗿𝗱𝘀:
→ Name it dashboard-builder, set its effort to medium, and preload a design skill
→ The first time, it asks what style you like and saves it to memory. After that, every dashboard fits your taste and the task at hand
→ Call it before every long task. It builds the dashboard in the background in about two minutes, and the main session keeps coding on high without stopping
→ The dashboard shows four things: task progress, what's stuck, questions waiting on you, and what it'll do by default if you don't answer
Send this prompt to Claude Code 👇
"Set up a subagent that only builds progress dashboards:
1. Create dashboard-builder in ~/.claude/agents: model: opus, effort: medium, memory: user. Preload the design skills I have installed (for example impeccable). It can only read and write the .dashboard/ folder and its own memory.
2. The first time, it asks me what style I like: dark or light, dense or airy, and one accent color. It saves my answer to memory and follows it every time. Pick the panels for the current task; don't use a template.
3. The dashboard is one HTML file showing tasks and their status, questions waiting for me with the default action, the latest deliverables, and anything stuck. Use the real clock for every time. It opens with a double-click and refreshes itself every 10 seconds.
4. Add a rule to ~/.claude/CLAUDE.md: for any task with more than 5 steps or that should take longer than 30 minutes, have dashboard-builder set up the dashboard before starting; update it after every step; when you need a decision from me, add it to the questions list and keep going with the default.
Show me the contents of the files you'll create or change, then explain the whole flow in words a 10-year-old could follow. Don't write anything until I confirm."

1
381
Alex proposes an "auto-compacting" history. I'd want an undo button: retract one bad observation without replaying the whole history. Once history lives in hidden state, correcting a memory isn't just a database edit anymore.
alexzhang13.github.io/blog/2…

Wrote a short blog about the "shape" of language models, and the tradeoffs they may present in the future. I genuinely think it's a valuable research direction to start thinking about now, especially w.r.t. harness design.
alexzhang13.github.io/blog/2…

254
Robot-use agents, Isola's phrase: an LLM as "the puppeteer of a robot body." YC's episode today: coding agents driving robots. Nothing remembers this specific robot. New papers all bolt on skill memory to fix it. Code has the repo. Everything else needs one. memoryrouter.ai
86