

AI dev • co-founder @polynternet • Building in progress
dm open
- Tweets 3,586
- Following 499
- Followers 25,878
- Likes 57,865


Pinned Tweet

Claude Code tip: before you ship a vibe-coded site, let Opus 5.5 send 𝟱 𝘀𝘂𝗯𝗮𝗴𝗲𝗻𝘁𝘀 through 𝘁𝗵𝗲𝘀𝗲 𝟮𝟬 𝗰𝗵𝗲𝗰𝗸𝘀 and fix everything in one pass:
1. design that holds together
• write a DESIGN file first and tie every color, font size, spacing and radius to it
• keep the palette tight and the type hierarchy clear
• same kind of button, card or input = same look
• flat page? add emphasis. crowded page? cut
• text stays readable on dark and light backgrounds
2. mobile
• nothing scrolls sideways or spills off screen
• add a real mobile menu
• buttons big enough for a thumb
• the layout survives enlarged text
3. every state
• loading, empty and error each get a proper screen
• every button gets its own hover, pressed and disabled look
• form errors show up next to the field, plus submitting, success and failure messages
• modals, dropdowns and tabs switch with transitions
4. click it like a real user
• run sign-up and checkout from start to finish
• hunt down dead buttons and broken links
• make sure the whole site works with just a keyboard
5. pre-launch
• the home page says what you do in one line
• each page gets one main button
• every page has a title, a description and a favicon
• delete every bit of placeholder text
on effort: Anthropic's cost guide puts medium on well-scoped daily work, so the default covers these 20 fixes
raise it only for the hard ones - Thariq's tests showed higher effort mostly buys extra verification and edge-case testing
paste this whole post into Claude Code and add this at the end 👇
"Run a pre-ship check on this repo.
You: main session, Opus 5.5, medium effort.
Spawn 5 read-only subagents, one per group:
design (medium) - DESIGN file, styles/globals.css, tailwind.config.ts, components/ui/
mobile (medium) - app/layout.tsx, components/nav/, every page at 375px
states (medium) - components/forms/, every loading, empty and error view
real user (high) - app/signup/, app/checkout/, every link and button
launch (medium) - app/page.tsx, page metadata, public/favicon.ico
Each subagent:
- checks only its group
- edits nothing
- returns issue, file:line, severity
Then:
1. merge all five lists into .claude/preship/issues.json, grouped by file, no duplicates
2. stop and show me the list - no edits until I confirm
3. after I confirm, fix everything yourself in one pass, so no two agents touch the same file
4. save before and after screenshots to .claude/preship/screens/"


24
46
380
36,456


Codex tip: once GPT-6.1 Sol is your main model, stop running Astra on every turn
keep Astra on call as an architect agent
Sol writes every line of code
Astra gets spawned at exactly three moments:
-> before a plan: is this even the right approach?
-> when the same error returns: am I digging in the wrong spot?
-> before "done": what did I skip?
Astra reviews. Sol ships
Jev engineering does the same thing one layer lower:
forks that need no thinker (which file, which tool, retry or stop) go to Jev in under half a second, and the big models only see the forks that actually split
the full tree:
> GPT-6.1 Sol on high runs the main session
> explorer reads the code on Luna
> worker edits and runs tests on Sol
> researcher pulls the docs on Luna
> all three on medium
> Astra on call as the architect
> auto_review checks every approval
paste the tree and this prompt into Codex 👇
"Rebuild my Codex setup around this tree.
1. Agents
- scan ~/.codex/agents and .codex/agents for anything that already fits explorer, worker or researcher
- draft TOML only for missing roles: explorer and researcher on gpt-6-luna, worker on gpt-6.1-sol, all at model_reasoning_effort medium
- explorer and researcher get a read-only sandbox, only worker can write
- skip agents pinned to another model and list them
2. Architect
- add an architect on gpt-6-astra, model_reasoning_effort high, read-only sandbox
- its only jobs: review plans, repeated errors and finished work
- feed it the plan, the diff and the failing log, never the full transcript
- force one output shape: verdict (proceed / revise / stop), top 3 risks, one cheaper path, under 200 words
- cap it at 3 calls per task
3. Main config
- in ~/.codex/config.toml set model to gpt-6.1-sol, model_reasoning_effort to high, approvals_reviewer to auto_review
4. Overrides
- find anything that would beat this: active profiles, flags in shell aliases, agents.default_subagent_model
- report it, change nothing
5. Rules
- add to the AGENTS file in the repo root: spawn the architect before a large plan, when the same error signature shows up twice, and before calling a long task done
- log every architect call with its trigger and verdict to .codex/architect-log.jsonl
Check that every TOML file parses, then show me all changes as one diff. No edits until I say go."
↳ developers.openai.com/codex/…


6
20
2,613
Mr. Buzzoni retweeted

this is certified f*cking gold
a 23-year-old from China runs 300 AI agents at once with Jev engineering, and none of them can lie to him
he opens the dashboard live:
300 Kimi K3 agents firing in parallel
Jev checking every single output against its source in about 100 milliseconds
pointed at 100 companies in the EV market:
> pass 1 - 12 failed: wrong revenue, dead citations, empty fields
> pass 2 - 3 failed
> pass 3 - zero. every row filed straight into an Obsidian vault
the whole trick is the split
Kimi K3 does the work, Jev decides if each claim actually matches the source
Jev never writes a second opinion. it answers yes or no with a confidence score, at $0.042 per million tokens in
and the loop refuses to stop while anything is still wrong
an analyst team bills weeks for 100 verified company profiles. he gets them from one run
one model writes, a cheaper one decides, and nothing ships until it says yes

40
84
700
154,436
Mr. Buzzoni retweeted
ok this is a f*cking cheat code for coding agents
how to make them 200x faster and 400x cheaper with Jev engineering
Jev founder Diogo Amogo put the whole harness into a 12-page PDF, 10 steps:
1. meet Jev
the LLM writes, the harness executes, Jev decides what each turn sees, where it routes and whether it runs
2. ask the question that breaks every agent
how would you build one if LLMs had no KV cache?
3. quit blind routing
Claude Opus 5.5 -> Sonnet 5.5 -> Opus costs 6.19, Opus alone 4.15, because every handoff reprocesses the full context
4. follow the tokens
reading and searching eat 56.2% of tool turns and 46.5% of tokens, writing code stays under 10%
5. score each chunk per query
hide it, summarize it or keep it whole, and compress once the question is known
6. reveal tools in tiers
one-line snippets for hundreds of tools, full schema on demand
7. load instructions by condition
a *.tsx edit pulls the style guide, billing/ pulls its gotchas file, compaction can't wipe either
8. route by trust as well as difficulty
secrets and infra stay on first-party frontier models, public docs go to the cheapest one
9. reuse one retrieval pass
review, evals, explainers and progress pages all run read-only in the background
10. gate every command
allow / ask / deny policies read the whole script before it runs
hand this PDF and the article below to Claude Code or Codex and start shipping faster

23
35
239
17,941
Mr. Buzzoni retweeted
Claude Code tip: before you ship a vibe-coded site, let Opus 5.5 send 𝟱 𝘀𝘂𝗯𝗮𝗴𝗲𝗻𝘁𝘀 through 𝘁𝗵𝗲𝘀𝗲 𝟮𝟬 𝗰𝗵𝗲𝗰𝗸𝘀 and fix everything in one pass:
1. design that holds together
• write a DESIGN file first and tie every color, font size, spacing and radius to it
• keep the palette tight and the type hierarchy clear
• same kind of button, card or input = same look
• flat page? add emphasis. crowded page? cut
• text stays readable on dark and light backgrounds
2. mobile
• nothing scrolls sideways or spills off screen
• add a real mobile menu
• buttons big enough for a thumb
• the layout survives enlarged text
3. every state
• loading, empty and error each get a proper screen
• every button gets its own hover, pressed and disabled look
• form errors show up next to the field, plus submitting, success and failure messages
• modals, dropdowns and tabs switch with transitions
4. click it like a real user
• run sign-up and checkout from start to finish
• hunt down dead buttons and broken links
• make sure the whole site works with just a keyboard
5. pre-launch
• the home page says what you do in one line
• each page gets one main button
• every page has a title, a description and a favicon
• delete every bit of placeholder text
on effort: Anthropic's cost guide puts medium on well-scoped daily work, so the default covers these 20 fixes
raise it only for the hard ones - Thariq's tests showed higher effort mostly buys extra verification and edge-case testing
paste this whole post into Claude Code and add this at the end 👇
"Run a pre-ship check on this repo.
You: main session, Opus 5.5, medium effort.
Spawn 5 read-only subagents, one per group:
design (medium) - DESIGN file, styles/globals.css, tailwind.config.ts, components/ui/
mobile (medium) - app/layout.tsx, components/nav/, every page at 375px
states (medium) - components/forms/, every loading, empty and error view
real user (high) - app/signup/, app/checkout/, every link and button
launch (medium) - app/page.tsx, page metadata, public/favicon.ico
Each subagent:
- checks only its group
- edits nothing
- returns issue, file:line, severity
Then:
1. merge all five lists into .claude/preship/issues.json, grouped by file, no duplicates
2. stop and show me the list - no edits until I confirm
3. after I confirm, fix everything yourself in one pass, so no two agents touch the same file
4. save before and after screenshots to .claude/preship/screens/"
24
46
380
36,456
Mr. Buzzoni retweeted
CLAUDE OPUS 5.5 + FABLE 5.1 + JEV ENGINEERING = THE CHEAPEST CODING LOOP YOU CAN RUN
one real multi-file refactor in Claude Code hid 31 checks inside it
did it pass, is it the right file, merge, retry or flag a person
the core idea:
25-40% of model calls in any agent loop with a review step are checks
Claude writes the code. Jev makes the calls
who owns which job:
> read a diff, write a review - Claude
> does this pass, is this the right file - Jev
> write the fix - Claude
> merge, retry or flag a person - Jev
> enforce the exact rule - your own code
the numbers:
> 348 ms per check
> 93.3% of broken rules caught
> TypeSafe's best case: 200x faster, 400x cheaper
the playbook:
1. audit one real transcript and mark every yes-or-no moment
2. write the schema down: questions, answers, confidence lines
3. move one decision first, keep the rest of the loop as is
4. below the threshold, hand it back to Opus 5.5 or Fable 5.1
5. npx skills add typesafe-ai/skills --skill typesafe-ai
the key insight:
Jev can't hallucinate text because it never writes any
but a bad schema lets it pick the wrong option with clean confidence
so set the threshold per decision and spot-check the sure ones
the engineer who cuts the review bill and keeps the code quality is the one who gets the raise

12
13
102
9,041
Mr. Buzzoni retweeted
I can't believe this is f*cking free
how to build your first AI agent (full guide, with a Jev decision layer)
a year ago I burned two weeks on my first agent. this guide gets you there in an afternoon
in the right hands it makes one builder ship like a small team:

27
106
640
59,315
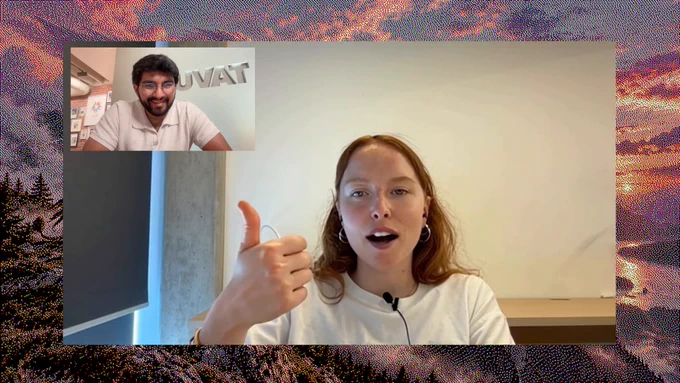
Tavus gave me early access to Griffin, the first human interaction model
you talk to it face to face, over video, in real time
48% of people thought it was a real human
previous systems got under 3%
#1 on NVIDIA's full-duplex video benchmark
backed by Sequoia and YC, $75M raised
what you can do with it:
> tell a story, it laughs and asks questions mid-sentence
> show it something, it works it into the chat
> solve a Rubik's cube, it coaches and waits while you think
> share good news, its face lights up
I tried it on a sick day and talked way longer than planned
congrats @tavus and @hassaanraza
tavus.io/griffin


Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Community note
The 48% figure and "video Turing test" claim are from Tavus's own study of 54 one-minute calls, not independently verified or using a standard protocol. Griffin-Lite leads NVIDIA's VideoFDB benchmark on their public leaderboard.
cellcog.ai/blog/tavus-gri…
research.nvidia.com/labs/amri/proj…
tech-ish.com/2026/10/02/tav…
20
14
209
24,004
ok this one is a f*cking goldmine
9 jobs where Jev engineering replaces a pricey LLM call (TypeSafe's full list)
Jev is TypeSafe AI's first System One model. 100x faster and cheaper than frontier LLMs
each of these 9 is money you're paying Claude for right now
in the right hands the work you skipped as too slow or too pricey gets you noticed:


23
44
264
29,393
Claude Code tip, and it's absolute free f*cking gold:
run Opus 5.5, Sonnet 5.5 and Fable 5.1 as one team and stop burning Opus tokens on routine work
the setup in one line:
plan on high, delegate on medium, keep Fable on call
• who does what
> Opus 5.5 on high - plans and ships the code
> Sonnet 5.5 on medium - explorer reads code, worker edits and runs tests, researcher pulls docs
> Fable 5.1 via /advisor fable - reads the whole session and speaks up only when it matters
• when Fable 5.1 steps in
-> before a plan: is this the right approach?
-> when an error repeats: am I digging in the wrong place?
-> before "done": what did I miss?
Jev engineering takes it one layer lower: which file, which tool, retry or stop all go to Jev in under half a second, so the big models only see the real forks
paste this into Claude Code ↓
"Rebuild my Claude Code setup:
1. Find subagents in ~/.claude/agents and .claude/agents that fit explorer, worker and researcher. Draft only the missing ones.
Set each to model: sonnet, effort: medium. List any that pin a different model and leave them
2. In ~/.claude/settings.json set effortLevel to high and advisorModel to fable.
3. Report anything that disables the advisor (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, flag-fetching blockers) and CLAUDE_CODE_EFFORT_LEVEL.
Change nothing.
4. Add to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done.
Show every change as a diff. No edits until I say go."
↳ code.claude.com/docs/en/advi…

45
94
980
141,584
HEYGEN VIDEO 1.0 + CLAUDE CODE = AN INSANE VIDEO STUDIO THAT LIVES IN YOUR TERMINAL
I made an entire anime short with it
the prompts, the renders and the final cut, all from one window
> a tiny train skimming a shallow sea at sunset
> a cottage walking off on wooden legs
> a red seaplane touching down in a hidden cove
and @HeyGen returns every shot with its own sound from the same call:
> wind through grass
> bacon sizzling
> rain tapping an umbrella
• my run, in numbers
> 58 shots rendered, all 58 came back
> about 15 seconds for a typical shot
> 16 anime shots in 67 seconds, 8 running at once
• two tricks worth stealing
> chain shots off the last frame: sketch -> paint -> alive
> one picture -> the same clay creature in anime and in a real café
Claude Code wrote every prompt in HeyGen's structured format
and built the motion design around the clips
one person with a terminal can now make the kind of short that used to take a whole animation team
which scene would you type first?

13
4
74
9,900
this is unreal f*cking gold for Jev builders
20 repos people are building on Jev right now. browser agents, context tools, trading bots, even a drone
1. JEV-Ultrafast - a browser agent built for speed
↳ github.com/browser-use/jev-u…
2. Fast-JEV-Compaction - squeezes your context down
↳ github.com/tamaratran/fast-j…
3. JSON-Render - UI generated on the fly
↳ github.com/vercel-labs/json-…
4. Typesafe-MCP - plugs Jev into any client
↳ github.com/itsmostafa/typesa…
5. JEV-MCP - a toolkit for judgment calls
↳ github.com/burnigtm/jev-mcp
6. Semdecide - a classifier right in your terminal
↳ github.com/sharziki/semdecid…
7. JEV-Codex-Router - sends every task to the model that fits it
↳ github.com/0xNatoshi/jev-cod…
8. Winnow - clears the junk out of your context
↳ github.com/GhalebDweikat/win…
9. JEV-Review - sorts code reviews by what needs eyes first
↳ github.com/devagrawal09/jev-…
10. Blink - finds your way around any repo
↳ github.com/ellipsis-dev/blin…
11. Agent-Desktop - runs your desktop for you
↳ github.com/lahfir/agent-desk…
12. Typesafe-Mario - an agent playing Super Mario
↳ github.com/fhshaik/typesafe-…
13. JEV-Drone - flies a drone
↳ github.com/RomanSlack/jev-dr…
14. OneVOneJev - a shooter in your browser
↳ github.com/emrickgarrett/One…
15. JEV-Trader - high-frequency market making
↳ github.com/buberlo/jev-trade…
16. Prism - spots liquidity signals
↳ github.com/irfndi/prism-liqu…
17. Neo4Jev - walks a knowledge graph
↳ github.com/jexp/neo4jev
18. JEV-Curate - screens training data
↳ github.com/AkashPriyadarshii…
19. Canny - confirms a task is really finished
↳ github.com/qkal/Canny
20. KillMyIdea - scores a startup idea before you sink time into it
↳ github.com/monteduro/killmyi…
start where your work is:
> coding -> JEV-Review, Blink, Canny, JEV-Codex-Router
> context -> Fast-JEV-Compaction, Winnow
> automation -> JEV-Ultrafast, Agent-Desktop
> clients and tools -> Typesafe-MCP, JEV-MCP, Semdecide
> UI -> JSON-Render
> trading -> JEV-Trader, Prism
> data -> Neo4Jev, JEV-Curate
> founders -> KillMyIdea
> for fun -> Typesafe-Mario, OneVOneJev, JEV-Drone
pick one, build on it this week, and you'll be the person on your team who actually knows Jev engineering when it gets asked for

11
32
157
11,862
CLAUDE + JEV ENGINEERING = THE HARNESS SKILL THAT GETS AI ENGINEERS PROMOTED IN 2026
1,000 decisions on a cold frontier model cost $605
the same 1,000 through this harness cost $0.17
the core idea:
Claude proposes, Jev answers, code decides
every step leaves a receipt
the loop:
> propose - Claude writes plans and patches, and decides nothing
> filter - code drops the routes your machine can't run before Jev ever sees them
> answer - Jev picks from code's menu with a probability, or abstains
> re-check - code checks the pick against live state. stale goes to fallback
> act - the tool runs through the normal approval path
> receipt - every step logged and replayable against a new policy
the numbers:
> 0.2s median per call
> ~$0.0002 per desktop step
> 49 of 49 WebMCP tasks passed
the key insight: "I don't know" is a real answer here
when Jev is only 38% sure, a fallback written in advance fires instead of a guess
worth stealing even if you never touch Jev:
> one decision the harness can check
> the exact options code prepared
> a defined path for when the model isn't sure
> a way to measure what actually happened
the engineer who can walk into a meeting and turn a $605 line into 17 cents is the one who gets asked to design the next system
the model got the words, Jev got the choices, and code kept the final say

22
48
312
31,819
> pov: Claude Opus 5.5 just finished your whole app
> you open the cloud console to deploy it
> it suddenly hits you
> the agent writes code in an hour and you've been doing its DevOps by hand for days
> then you see InstaCloud
> the agent deploys it, scales it, and tests on a full copy with the data
> and that's when it lands


We just raised an $8M seed round to kill AWS, GCP, and Azure.
Introducing instacloud.com, the agent-native serverless cloud.
Your team is shipping code like never before. But you're getting caught up in manual, tedious DevOps work trying to deploy it.
InstaCloud provides the serverless compute that lets your services autoscale, with all the infrastructure managed for you.
Agents branch into complete replica environments when working, keeping prod safe and iteration speed high.
And of course, it all works seamlessly with agents through MCP/CLI.
Get off the traditional, legacy cloud.
Start deploying your services on InstaCloud today.

4
40
4,014
paste this Jev prompt into Claude and let it audit you
it installs Jev, studies how you actually work, and shows you exactly where the hours and the money slip away
then it rebuilds your whole setup around the leaks it found
same $20 subscription
and you end up running it better than 95% of the people paying for the same model
the full prompt 👇

12
45
306
38,192
this is pure f*cking gold for anyone doing Jev engineering
the skill that teaches Claude Code to build on Jev the right way, from TypeSafe themselves
without it, coding agents send Jev one question at a time and guess the field names
with it, the order is set before a single line gets written:
docs -> behaviour -> judgments -> one request -> code decides
the two-page breakdown of every rule:
> the failure each of its 11 instructions is there to prevent
> Choice, Noul or Score, picked at a glance
> a prompt skeleton you paste straight into your agent
12.2x
that's how far the bill fell in TypeSafe's cookbook when 13 questions went out in one call
one short file, and your agent stops paying for decisions it should have batched

13
17
178
28,588