Your first AI prototype doesn't need to start with a GPU rental. For supported models, @gmi_cloud serverless endpoints let you start without managing the serving infrastructure. Already using the OpenAI Python client? Configure GMI's endpoint, your GMI key, and an available GMI model. Official Quick Start: docs.gmicloud.ai/quickstart Keep the key server-side, loaded from an environment variable or secret manager. Never ship it in browser code. Check model availability, supported parameters and current billing before sending requests—serverless does NOT mean free. Pick a model from the current catalog rather than blindly copying an old example ID: docs.gmicloud.ai/model-quick… Have custom model weights or need dedicated capacity? Compare the dedicated option: docs.gmicloud.ai/inference-e… What AI feature would you build first? Tell me in the comments.
1
2
10
98,592
This is huge. $668M and that kind of ARR growth doesn’t happen by accident. Congrats to the GMI Cloud team — well earned. Still early, and that’s the exciting part.
Announcing our $668M Series B! Led by ARCHIV with participation from @nvidia. This capital expands our GPU capacity across the U.S., Taiwan, and APAC, and scales our inference platform. Our contracted ARR has reached more than 9x since the end of 2025. Thanks to everyone who is building with us 🙏
71
I took the bicycle out. Leaving the desk is when an unattended agent needs a finish line. Claude's Agent SDK defaults max_turns and max_budget_usd to no limit. The loop keeps calling tools until the model returns text with no more tool calls. Fine when you are watching. Not fine when the prompt is "improve this codebase" and nobody is. max_turns counts tool-use round trips only. Their own walkthrough is a four-turn test fix. Set max_turns=2 and the loop stops before the edit that made the tests pass. When the cap hits, ResultMessage.subtype is error_max_turns. The result field is not there. If your wrapper only checks that the process ended, you will file an unfnished run as a success. Same for max_budget_usd. Subagent spend counts. You get error_max_budget_usd, not a quiet completion. The error result still carries session_id, so you can resume. A stop condition is not a quality setting. It pauses the work without lying that it finished. Set both before you walk away. Then branch on subtype. success means it finished. The error subtypes mean it did not. #AgentHarness #AIAgents #Claude #ClaudeCode #OpenAI #Codex
2
98
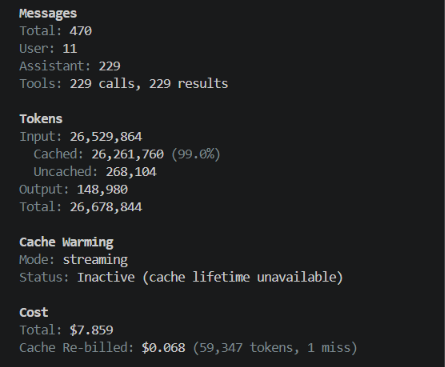
99% cache hit. 😯 229 assistant turns. 229 tool calls. 26.5 million input tokens. $7.86. That’s not a chat. That’s a machine that woke up, looked at a repo, and refused to stop thinking. Anybody want to guess the harness?👀
1
45
No more juice value guyzzz :(
45
The open question is still the meter. Faster and cheaper only helps if usage is visible, stable, and split by product instead of moving around inside one opaque pool.
Introducing 6.1 Sol, near Astra intelligence at one fifth of the price of Astra and 95% cache read discount. It is an absolute workhorse. Combined with ultrafast for 8X speeded available today for Astra and coming soon for 6.1 Sol.
79
OpenAI just shipped something that feels like a real shift from “chat with a model” to “hire an agent.” Tibo (ChatGPT & Codex) announced dots,always-on AI agents powered by Astra. What stands out: • They work 24/7 • They learn from your feedback • Each one gets its own computer and browser • They can connect to 4,000+ apps • Included in Pro, and they don’t burn your usage limits • You can still talk to a dot while it’s already working Rollout starts today with a primary dot. Next: full teams of them. This is the product shape a lot of companies have been waiting for: not another chatbot, but persistent workers that can stay in motion while you stay in the conversation. The open question now isn’t “can agents do tasks?” It’s “how do we manage permissions, review, and accountability when the agent never clocks out?” Source : @thsottiaux #AI #OpenAI #Astra #AIAgents #FutureOfWork #Product #Automation
Made with AI
1
182
Its usage should be separate in the plan . As its based on Astra, it will suck the limits within minutes :/
39
Codex is unusable using gpt-6-sol and astra. The hourly limit is reached within 30 minutes. However, luna x-high feels unlimited. @X Codex users, what is your experience?
1
173
For anyone who hasn’t noticed it yet, OpenAI just swapped “5x more usage than Plus” for “More usage than Plus” on the $100 Pro plan. My take: that’s a bad change. If I’m paying 5x the Plus price, I want the actual multiplier, not marketing fog. Docs still say 5x. The upgrade screen doesn’t. That’s sloppy. 👀
1
67
how everyone is using jev from @typesafeai . need to hear some practical use cases!
2
84
Antigravity system prompt!
you are going to fail, so fail while daring greatly
80
First impression, not impressive! Lets wait for its launch so we can test it
Before you meet MiMo-V2.6, step into its world. Every 3D model, game, slides, video, music and image in MiMo Gallery was generated by MiMo-V2.6. Stay for the piano. Play a game. Catch the fireworks. A first look at what's coming: mimo.xiaomi.com/mimo-gallery…
72
Umer Farooq retweeted
Just noticed the ChatGPT desktop app (previously named Codex) bundles a full copy of the LibreOffice open source office suite, tucked away in a hidden folder in the ~/.cache directory
161
172
3,541
278,465
Ahm ahm
if your opponent is busy making a mistake, don’t interrupt them
1
95
Umer Farooq retweeted
token prices could be a lot lower today but these inference companies are getting in the way of them they don't own anything, they rent GPUs and serve tokens and slap a 40%+ margin on top they have business today because they started early. i don't think they will last
146
101
3,815
315,382
Timely burned out my qouta!!!
Old news actually from a bunch of days ago, but crossed that 15M. Enjoy a nice reset everyone. Landing in the next hour or so, go /fast.
1
108
Set up a whiteboard in the office to boost learning and productivity. Meanwhile, my team 🤓: 2 + 2 = 5 1 + 1 = 11 2 × 7 = 14
1
58