
Developer Advocate @GMI_Cloud AI Consultant
- Tweets 1,268
- Following 673
- Followers 150
- Likes 123


I have never in my life achieved inbox zero until I just made it an active goal for my dot to help get it done. Let’s see how long it lasts, but it’s a great feeling.


Down to 6110 unread from the over 9000 unread emails just earlier. Will get to inbox zero with clean filters within the next 48 hours. Dot has accepted the challenge.
402
45
2,048
303,409

I had an old X account for years. Less than 100 followers. Whatever I posted, I’d get fewer than 10 views.
I used to think, “What a terrible platform.”
Nobody cared about me. Nobody even saw me.
So what was I supposed to do here?
Now, I realized the problem wasn’t X. It was me.
I was posting, but I wasn’t really participating. I didn’t connect.
90
10
229
7,867
A sufficiently large quantity is a quality all its own.
Big difference between bacteria with one cell and a human with 35 trillion cells, even though both are made of cells.

Anything TSMC contributes to Terafab would basically be supplemental
Terafab itself is going to be absurdly massive
The goal is 1 TW of compute production every year.....around 50× the current global output of AI compute
This isn’t just another fab. It’s being built for a scale the semiconductor industry simply does not operate at any known scale today

1,545
1,920
13,510
3,457,750
Fortunately our future models will be much better at code deletion and simplification. Just in time
1,049
275
12,036
872,703

We’re open sourcing a state of the art multimodal Decision Model, pplx-decider-27b, and are offering it in a new Decisions API at 4 cents per million input tokens and free output tokens. We intend to bring down the price even further over the coming days. Enjoy!

Introducing the Perplexity Decisions API.
It's powered by pplx-decider-v1-27b, our multimodal decision model trained to output a probability distribution over a fixed set of answers instead of text.
It costs $0.04/million input tokens and scores 85.71% across benchmarks.

77
88
1,497
133,152
Your first AI prototype doesn't need to start with a GPU rental.
For supported models, @gmi_cloud serverless endpoints let you start without managing the serving infrastructure. Already using the OpenAI Python client? Configure GMI's endpoint, your GMI key, and an available GMI model.
Official Quick Start:
docs.gmicloud.ai/quickstart
Keep the key server-side, loaded from an environment variable or secret manager. Never ship it in browser code. Check model availability, supported parameters and current billing before sending requests—serverless does NOT mean free.
Pick a model from the current catalog rather than blindly copying an old example ID:
docs.gmicloud.ai/model-quick…
Have custom model weights or need dedicated capacity? Compare the dedicated option:
docs.gmicloud.ai/inference-e…
What AI feature would you build first? Tell me in the comments.

1
2
11
98,905
This is huge. $668M and that kind of ARR growth doesn’t happen by accident.
Congrats to the GMI Cloud team — well earned. Still early, and that’s the exciting part.

Announcing our $668M Series B!
Led by ARCHIV with participation from @nvidia.
This capital expands our GPU capacity across the U.S., Taiwan, and APAC, and scales our inference platform.
Our contracted ARR has reached more than 9x since the end of 2025.
Thanks to everyone who is building with us 🙏

88
One more thing, you can now build and deploy MCP servers right through ChatGPT. And restrict its access to anyone you want or share it with the world.

Announcing one more launch: ChatGPT Sites can now host MCP servers, including plugin extensions! 🤯
> @sites create a todo list that I can use in ChatGPT
This will:
· Create an MCP server with extensions
· Deploy that MCP server to Sites
· Turn the MCP server into a plugin
· Install the plugin for you across web, mobile, and desktop
ChatGPT is slowly becoming malleable software that anybody can customize to their needs. Very excited to see what you all build with this!
429
285
5,193
863,218

Introducing Gemini 4 Argon, our new frontier model, rolling out to cyber defenders starting today, and more widely as soon as possible. I am really excited by the progress we have made here. Argon is priced at $2 in and $10 out during introductory pricing!


1,015
1,055
14,772
1,548,561

Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.

1,968
4,636
42,912
8,757,378

I took the bicycle out.
Leaving the desk is when an unattended agent needs a finish line.
Claude's Agent SDK defaults max_turns and max_budget_usd to no limit.
The loop keeps calling tools until the model returns text with no more tool calls. Fine when you are watching. Not fine when the prompt is "improve this codebase" and nobody is.
max_turns counts tool-use round trips only. Their own walkthrough is a four-turn test fix. Set max_turns=2 and the loop stops before the edit that made the tests pass.
When the cap hits, ResultMessage.subtype is error_max_turns. The result field is not there. If your wrapper only checks that the process ended, you will file an unfnished run as a success.
Same for max_budget_usd. Subagent spend counts. You get error_max_budget_usd, not a quiet completion.
The error result still carries session_id, so you can resume. A stop condition is not a quality setting. It pauses the work without lying that it finished.
Set both before you walk away. Then branch on subtype. success means it finished. The error subtypes mean it did not.
#AgentHarness #AIAgents #Claude #ClaudeCode #OpenAI #Codex

2
112
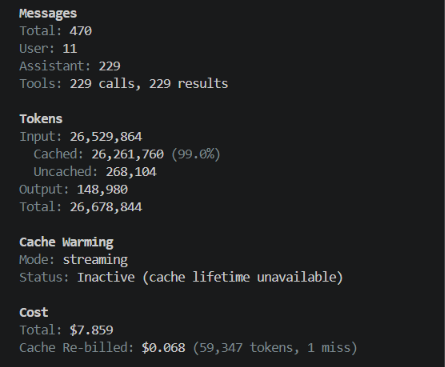
99% cache hit. 😯
229 assistant turns.
229 tool calls.
26.5 million input tokens.
$7.86.
That’s not a chat.
That’s a machine that woke up, looked at a repo, and refused to stop thinking.
Anybody want to guess the harness?👀
1
53

I got community noted, but the note is wrong 😅
Your primary dot is included in your plan and will be available 24/7. If you ask it to create a codex task for you, that one will be drawing usage as usual. But when your dot does work directly, that uses nothing and is all on top of your plans usage. In the future you will be able to increase the speed and allow your dot to have more bandwidth, this will be a paid feature, but the baseline functionality will always just be included in your plan.
Announcing dots. Dots work 24/7 for you, learn from your feedback, have their own computer, browser and can be connected to over 4k apps in our ecosystem.
They’re powered by Astra our best model yet. Included in your Pro plan, without drawing down on any of your usage. You can even call a dot while it’s working.
We’re getting you started with your primary dot today and soon you’ll be able to create entire teams of them.
614
160
4,649
1,259,365

The open question is still the meter.
Faster and cheaper only helps if usage is visible, stable, and split by product instead of moving around inside one opaque pool.
Introducing 6.1 Sol, near Astra intelligence at one fifth of the price of Astra and 95% cache read discount. It is an absolute workhorse.
Combined with ultrafast for 8X speeded available today for Astra and coming soon for 6.1 Sol.
80
Introducing 6.1 Sol, near Astra intelligence at one fifth of the price of Astra and 95% cache read discount. It is an absolute workhorse.
Combined with ultrafast for 8X speeded available today for Astra and coming soon for 6.1 Sol.
1,113
952
19,701
2,232,168