
Developer Advocate @GMI_Cloud AI Consultant
- Tweets 1,266
- Following 666
- Followers 145
- Likes 122


I feel, all social platform works almost same. Provide value or be cringe = gettin followers.
1
1
27
Your first AI prototype doesn't need to start with a GPU rental.
For supported models, @gmi_cloud serverless endpoints let you start without managing the serving infrastructure. Already using the OpenAI Python client? Configure GMI's endpoint, your GMI key, and an available GMI model.
Official Quick Start:
docs.gmicloud.ai/quickstart
Keep the key server-side, loaded from an environment variable or secret manager. Never ship it in browser code. Check model availability, supported parameters and current billing before sending requests—serverless does NOT mean free.
Pick a model from the current catalog rather than blindly copying an old example ID:
docs.gmicloud.ai/model-quick…
Have custom model weights or need dedicated capacity? Compare the dedicated option:
docs.gmicloud.ai/inference-e…
What AI feature would you build first? Tell me in the comments.

1
2
11
98,791
This is huge. $668M and that kind of ARR growth doesn’t happen by accident.
Congrats to the GMI Cloud team — well earned. Still early, and that’s the exciting part.

Announcing our $668M Series B!
Led by ARCHIV with participation from @nvidia.
This capital expands our GPU capacity across the U.S., Taiwan, and APAC, and scales our inference platform.
Our contracted ARR has reached more than 9x since the end of 2025.
Thanks to everyone who is building with us 🙏

82
I took the bicycle out.
Leaving the desk is when an unattended agent needs a finish line.
Claude's Agent SDK defaults max_turns and max_budget_usd to no limit.
The loop keeps calling tools until the model returns text with no more tool calls. Fine when you are watching. Not fine when the prompt is "improve this codebase" and nobody is.
max_turns counts tool-use round trips only. Their own walkthrough is a four-turn test fix. Set max_turns=2 and the loop stops before the edit that made the tests pass.
When the cap hits, ResultMessage.subtype is error_max_turns. The result field is not there. If your wrapper only checks that the process ended, you will file an unfnished run as a success.
Same for max_budget_usd. Subagent spend counts. You get error_max_budget_usd, not a quiet completion.
The error result still carries session_id, so you can resume. A stop condition is not a quality setting. It pauses the work without lying that it finished.
Set both before you walk away. Then branch on subtype. success means it finished. The error subtypes mean it did not.
#AgentHarness #AIAgents #Claude #ClaudeCode #OpenAI #Codex

2
106
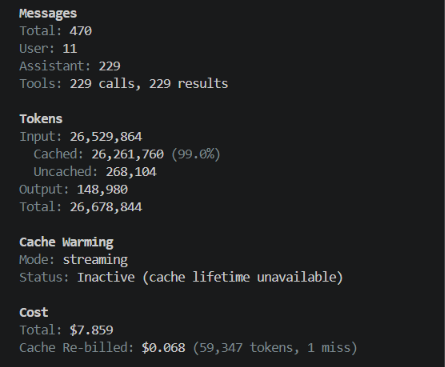
99% cache hit. 😯
229 assistant turns.
229 tool calls.
26.5 million input tokens.
$7.86.
That’s not a chat.
That’s a machine that woke up, looked at a repo, and refused to stop thinking.
Anybody want to guess the harness?👀
1
48

The open question is still the meter.
Faster and cheaper only helps if usage is visible, stable, and split by product instead of moving around inside one opaque pool.

Introducing 6.1 Sol, near Astra intelligence at one fifth of the price of Astra and 95% cache read discount. It is an absolute workhorse.
Combined with ultrafast for 8X speeded available today for Astra and coming soon for 6.1 Sol.
80
Hopefully the juice value would be same for codex and api.Don’t want to see api benchmarks and use a nerfed variant
2
2,157