

Computer scientist. I teach hard-core AI/ML Engineering at ml.school. YouTube: piped.video/@underfitted
🇺🇸 Collaborations →
- Tweets 50,844
- Following 604
- Followers 456,658
- Likes 66,413


Right now, I consult for several companies. I help their engineering teams introduce AI into their workflows.
Each of these teams has become much more productive than before using AI. Their software is better. They deliver faster and more.
It usually takes time to ramp up, but once they do, it's like a train: unstoppable.
The goal with these teams is to switch their focus:
Before: "we need high-quality code so humans can maintain it".
After: "we need a strong process to validate what agents do".
Many people believe these teams are somehow doomed to one day wake up and realize all of their software is crap. That they will realize all the agentic slop they shipped was useless.
I think those people are delusional.
36
11
101
9,266
I have 20 free tickets for Vercel Ship.
This is Vercel's event for AI builders, happening on Thursday, October 15, at the Palace of Fine Arts in San Francisco.
It's a one-day, in-person event with hands-on workshops and demos.
This is the place to meet developers, AI builders, founders, and engineers from every single industry.
Tickets are first come, first served.
To get a free ticket, use the link below with code SHIP26-SVPINO-100OFF.
Link: vercel.plug.dev/s1rg0Tt

6
6
25
13,538

For example, you can use @zerodrift_ai to review contracts, documentation, emails, Slack messages, or pretty much any communication you generate.
It's very simple, but really smart.
Here is the link to their platform: fandf.co/4hoYDca
Thanks to the ZeroDrift team for partnering with me on this post.
3
1
4
1,463
Santiago retweeted

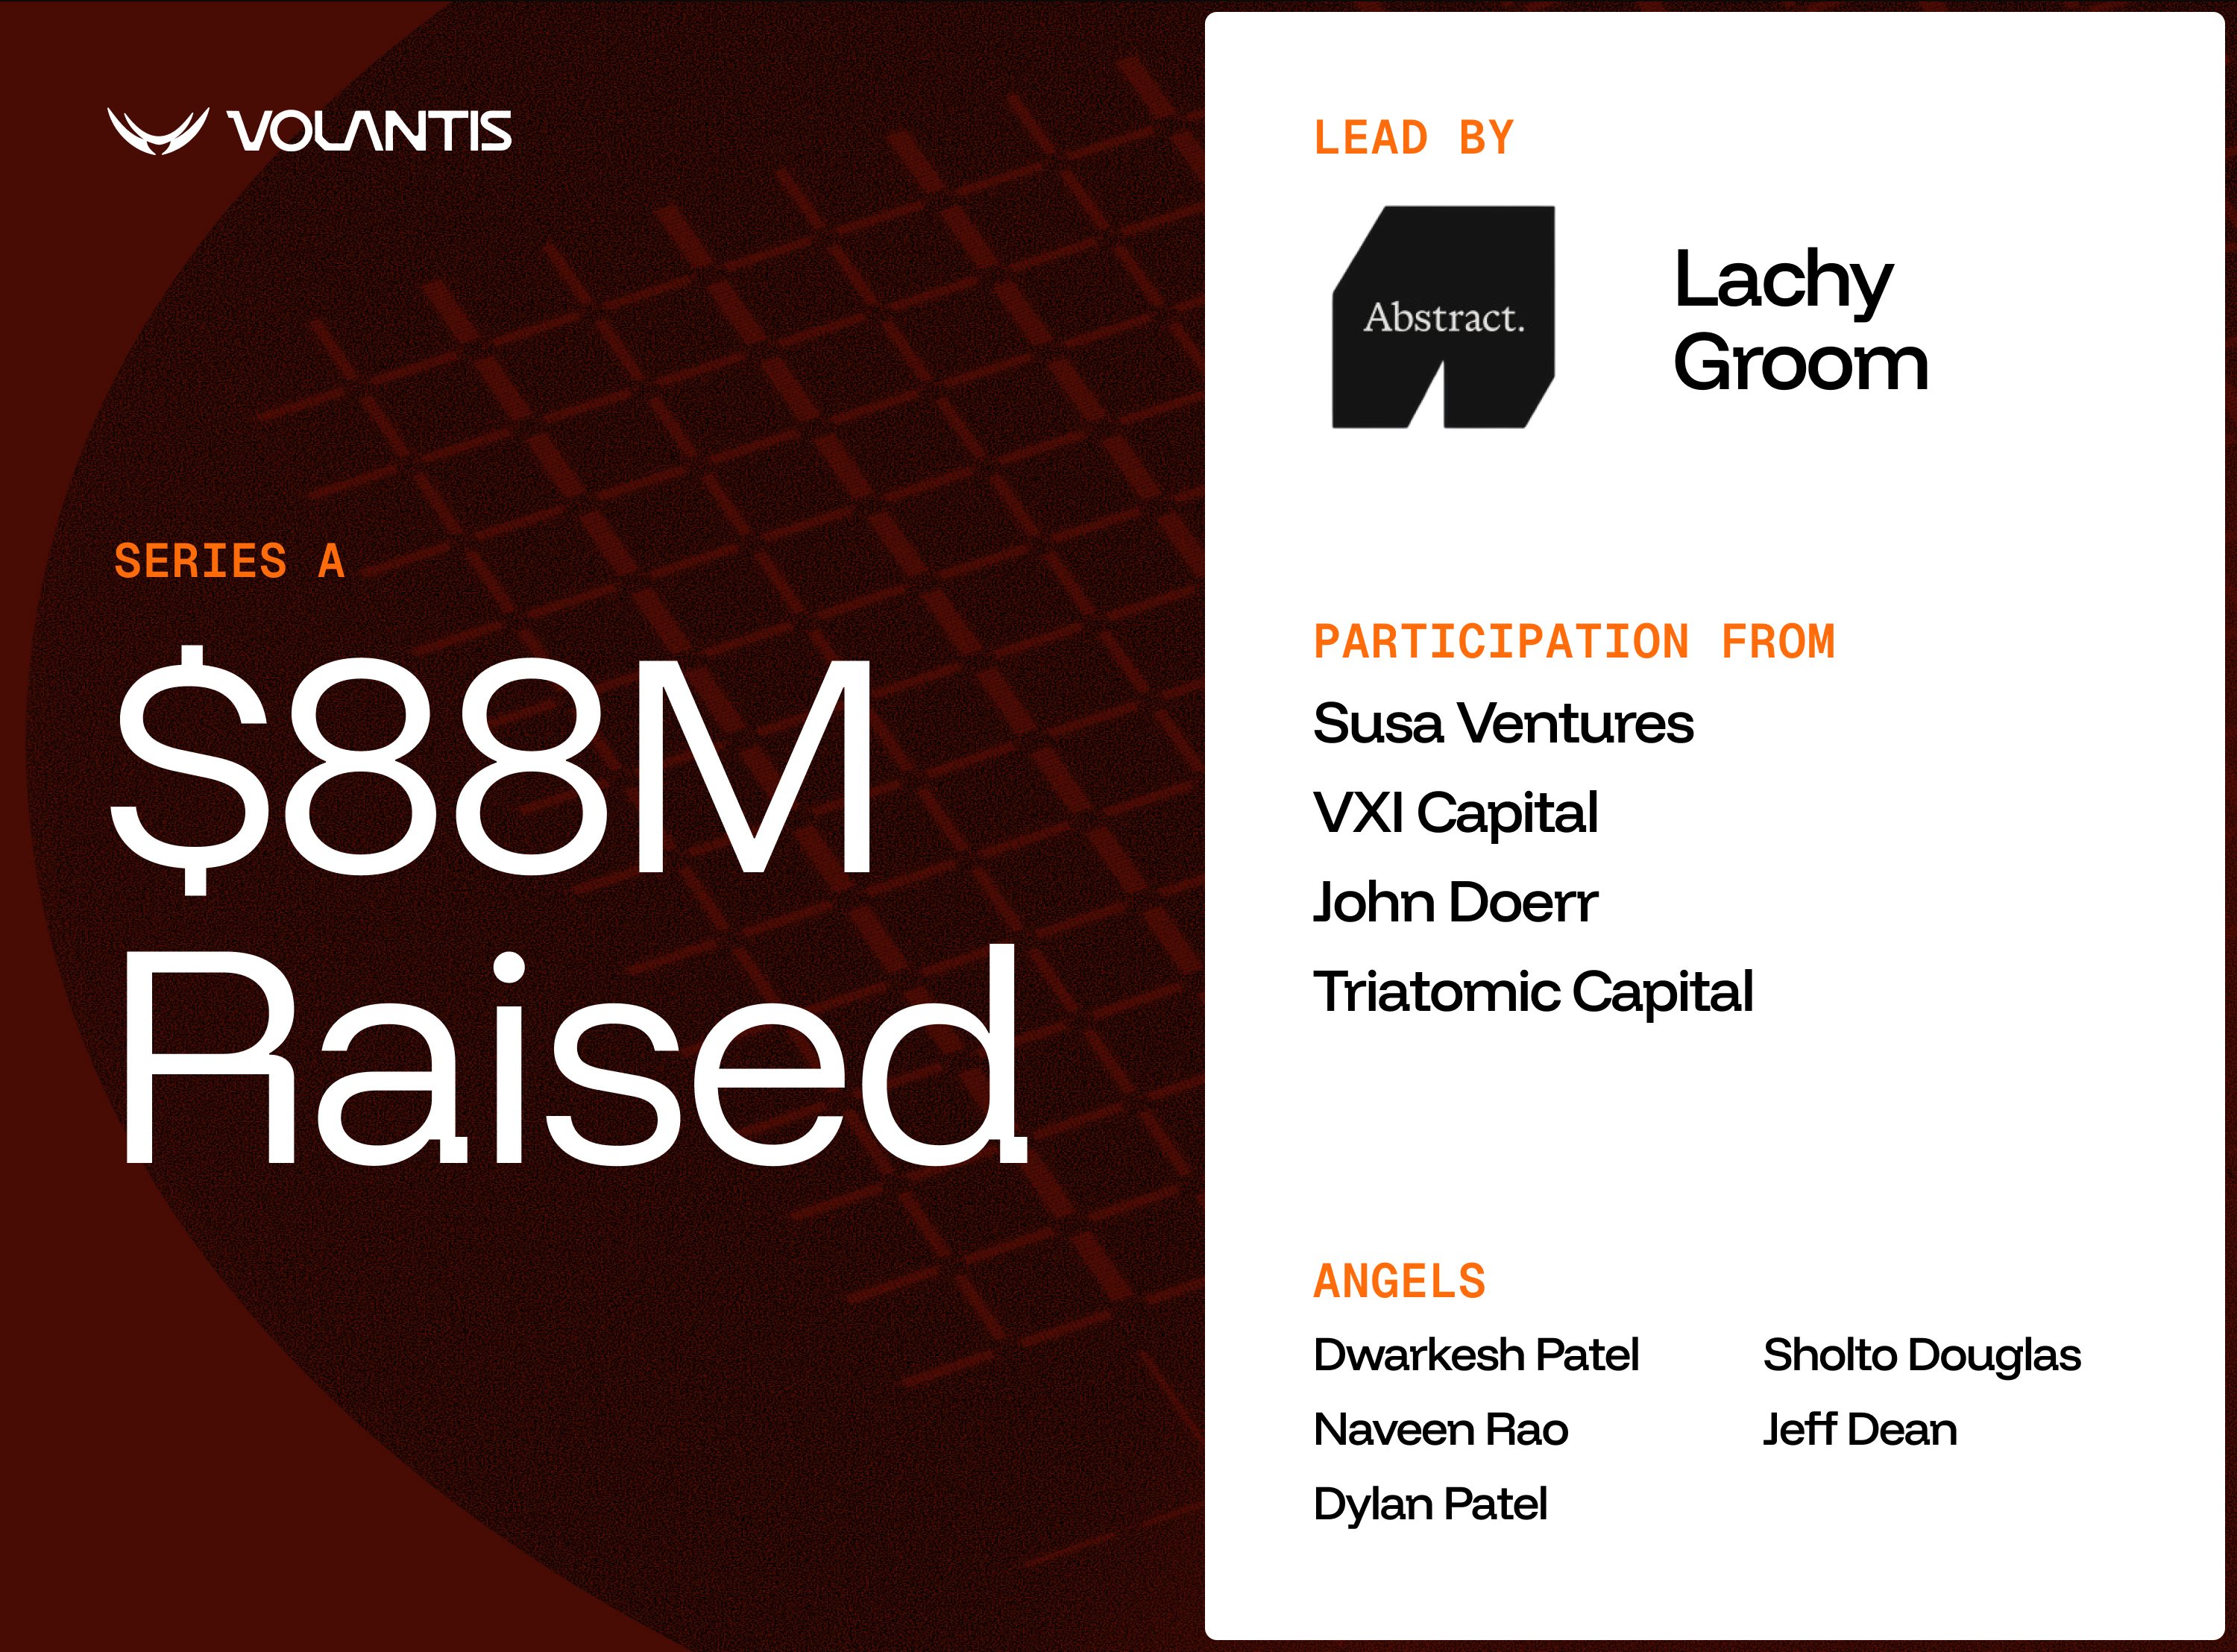
Excited to announce Volantis's $88M Series A.
We are solving Al's memory bottleneck by using optics, enabling chips with huge amounts of fast & cheap memory.
By boosting both the memory bandwidth and capacity per chip by orders of magnitude, we enable ultra-fast inference (up to 10,000 tps/user) for large models (>10T) - with low $/tok to boot.
Initially, this will enable insanely fast agents - think coding agents that finish in minutes or even seconds instead of hours.
More excitingly, optics is a fundamentally scalable way to increase memory systems. Not 2X/year, but by orders of magnitude across new generations. This will enable a structurally new Al industry, including restarting scaling laws, holding entire repos in context windows & more.
Our team has pioneered many core semiconductor technologies: the 1st CoWoS product, early HBM, the 1st silicon photonics CPO systems, the 1st high volume tunable VCSELs, the 1st processors to directly communicate using light & more.
We’ve already sent data >10× farther than equally tiny electrical wires inside a chip package. Our next iteration is already taped out and targets world-record bandwidth density over relevant distances, read more: volantissemi.ai/news-insight…
197
180
1,400
967,606
You gotta try this out.
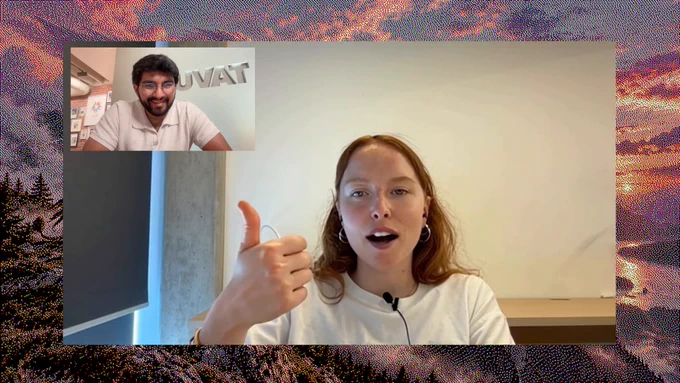
Here are some fragments from my conversation with "Vanessa."
It won't necessarily fool me into thinking I'm talking to a real person, but holy moly, this is the closest we've gotten, for sure.


Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Community note
The 48% figure and "video Turing test" claim are from Tavus's own study of 54 one-minute calls, not independently verified or using a standard protocol. Griffin-Lite leads NVIDIA's VideoFDB benchmark on their public leaderboard.
cellcog.ai/blog/tavus-gri…
research.nvidia.com/labs/amri/proj…
tech-ish.com/2026/10/02/tav…
12
6
113
19,809
This is the best human-interaction model I've ever seen in action.
I got early access to Tavus. I tested it.
Judge for yourself.

Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Community note
The 48% figure and "video Turing test" claim are from Tavus's own study of 54 one-minute calls, not independently verified or using a standard protocol. Griffin-Lite leads NVIDIA's VideoFDB benchmark on their public leaderboard.
cellcog.ai/blog/tavus-gri…
research.nvidia.com/labs/amri/proj…
tech-ish.com/2026/10/02/tav…
42
57
464
82,701
Pretty clever: a model routing and quality-control layer, but for voice models.
Basically, @OnepinAI sits on top of existing TTS providers.
• It normalizes the script
• It selects a voice model for different lines
• It generates the voiceover
• It checks pronunciation, clarity, and naturalness
• It fixes or regenerates lines that don't sound good
Really cool for anyone generating voice at scale.


Your AI voice sounds human. So why can't it say your product's name?
A great AI voice reads "Porsche Taycan" as TAY-can. Porsche says TIE-kahn. It guessed from the spelling, and nobody caught it, because nobody listens to line 1,200.
Today we're launching Onepin: the production step after text-to-speech. It checks every line of voiceover before it ships using the voices you already work with.
Onepin can:
➤ Check people's and product names against a 4-million-word pronunciation dictionary
➤ Spell out prices and dates before the voice speaks
➤ Score every line of audio for naturalness, clarity and word accuracy
➤ Fix the one wrong word in the same voice, without re-rendering the take
Works with your voice subscription on @ElevenLabs, @OpenAI, @Google and 30+ more. No phonetic spellings to type. No re-rolls. No switching providers.
Free to start, no credit card required. Hear the before and after in the thread ⬇️

Paid partnership (ad)
8
1
33
14,054
It was only a matter of time before we brought the first AI and real, licensed attorneys together.
This is really cool for anyone who needs a law firm:
• Send a contract using Slack
• Approve a flat fee
• AI gathers business context
• AI helps to speed up every task
• A human attorney reviews everything
• That same human remains responsible for the work
• You get your contract back

I’m excited to announce that @arceuslegal is launching with $17M in funding, led by @greycroftvc, with participation from @craft_ventures, @spc, and others.
As a founder, I always hated how helpless I felt working with law firms.
I went through four or five different firms and somehow the experience was always the same.
I’d be waiting on something important to our business with no idea when I’d hear back. I’d have to re-explain our business over and over again. And I dreaded jumping on calls because I knew every minute was costing me money.
We started Arceus because we believe every business deserves a better law firm.
One that moves faster, costs less, and puts the client first.
And we’re just getting started. ↓

10
2
75
25,923
Nace AI just released Drex 1.5 — the first (and so far the only) decision model with a 128k context window.
128k is really good! You can send an entire contract or a video transcript and get a scored decision over the whole thing. You don't need to mess with chunking or stitching results back together.
The idea is the same as with Jev:
• Input: context + a set of choices
• Output: classification + score for every option
For example, you can use Drex to classify a review as "POSITIVE", "NEGATIVE", or "NEUTRAL", and route any low-scored answer to a human for further inspection.
Here is where the model differs from Jev:
• 128k context
• Small - It's under 10B parameters
• $0.04 per 1M input tokens, a bit cheaper than Jev
The model is #1 on the Decision Index 0.2.1 (chance-corrected; random guessing = 0):
• Drex: 58.28
• Jev 1.13.0: 57.91
Nace is giving 250M free tokens to the first 10,000 builders: nace.ai/drex
Thanks to the @NaceAI team for partnering with me on this post.
12
1
41
13,063
This pareto-26.10-preview model is pretty cool. It does something I haven't seen before:
It basically combines multiple models behind one API response:
1. You send a request
2. Pareto runs several models to produce answers
3. It then evaluates the answers and selects the best
4. It returns that answer back to you
You don't need to build a comparison/selection system since it's built in when you use this model.
It's also cheap: $0.80/MTk in and $3.20/Mtk out. That's cheaper than
Sol and 10x cheaper than Fable or Astra.

1/ Pareto 26.10 Preview from @theunbiasedco is now live on OpenRouter at $0.80/M input and $3.20/M output, vs $2.50/$7.50 for the current Pareto.
A multimodal composite model for research, coding, and agentic workflows, with 1M context, text and image input, and tool calling.
12
7
111
47,973
This is the dream job for anyone looking to become an automation engineer in AI:
You'll join a team, learn its processes, and build automations for their work:
1. You'll meet with the people who are doing the work
2. You'll find and connect the systems needed to complete it
3. You'll build and validate the workflows
4. You'll teach the team how to extend what you built
5. Pick a new problem, and repeat
The job:
• Full-time
• 2 years of experience
• Working knowledge of APIs and IAM
• On-site in San Francisco, New York, Austin, or Charleston
• $105,000 - $170,000/year + equity


11
18
336
47,649
A fine-tuned model can outperform frontier models and be cheaper and faster to run.
Literally, every company I've met wants this.
I want you to see these results from fine-tuning Qwen3 4B on AWS. It smokes both the out-of-the-box model and Claude Sonnet 4.6.

66
154
1,545
83,564
You can get the entire codebase to fine-tune a model on AWS from the following workshop:
fandf.co/4huqo1X
There are four different examples:
• Supervised Fine-Tuning (SFT) DOP
• Direct Preference Optimization (DPO)
• Reinforcement Learning from Verifiable Rewards (RLVR)
• Reinforcement Learning from AI Feedback (RLAIF)
Also, check out the AWS AI Virtual League. They have a few upcoming events where you can compete by building agents and fine-tuning models:
fandf.co/4ywLXWZ
Thanks to the @AWS team for partnering with me on this post.
2
11
102
5,927
Season 3 of Advent of Agents is out!
This is a 31-day online learning program designed by Google Cloud to help developers secure and govern production-ready agentic systems.
Each day, you'll unlock one more topic. You'll work through the lessons and complete the day's exercises.
Here is the link to the new season:


Introducing Google Cloud Advent of Agents Season 3.
31 days of building secure, governed AI agents for production.
Daily tutorials. Copy-paste code. 100% free.
Starts tomorrow: adventofagents.com/

8
9
59
14,346
This open-source model scores 95.4% on BIG-Bench Hard’s logic subset with just 3.66B parameters.
TwIL-LM3-Pro is a model small enough to run locally on a laptop.
Specialized post-training is super cool. You can get a ton of small models when you focus on specific tasks.


Half a million downloads in a month. Today, our open source family takes another step forward.
Thank you for the incredible support behind our first-generation models. We’re excited to introduce TwIL-LM3-Pro.
At just 3.6 billion parameters, it brings powerful reasoning to everyday computers, with quantized builds that run locally. No cloud required.
In our evaluation:
Formal logic: Highest recorded headline score among the small models compared—beating China’s VibeThinker-3B by 35% and Qwen3.5-4B by 24%, and Liquid AI’s LFM2.5-8B-A1B by 47%.
Broader reasoning: 95% on SVAMP and 64.1% on MuSR, the highest recorded scores among the small models compared.
BIG-Bench Hard’s logic subset: 95.4%, compared with VibeThinker-3B’s 61.1%.
We believe AI is entering a post-training era. The advantage will increasingly belong to companies with the best pipelines and those that can produce capable, personalized intelligence faster and more efficiently, then put it on devices people already own.
That’s what we’re building at webAI. And we’re only beginning to share what’s coming out of our lab.
Coming soon: Meridian, our family of frontier-class models built to run on device. Our most advanced models will be available through the @thewebAI application.
Join the waitlist as we expand access. Proudly built in Austin, Texas. 🇺🇸

11
7
71
14,419
I got access to Dots today. So far, it’s done all of this for me:
- Checked in my wife and daughter’s flights for tomorrow
- transferred my available paypal balance to my bank
- learned how to take screenshots of some analytics I have to provide and auto-reply to emails with that screenshot
- helped me sort a massive spreadsheet
- learned how to provide an executive summary of specific emails I get with things I have to do
All of that in a few hours.
Love it so far. Now I need it to work on my Linux laptop.
33
7
114
27,238
This is the #2 model on the Artificial Analysis Text-to-Video Leaderboard with Audio worldwide.
No other US-based company has a model higher than this.
I checked their website, and their model's production quality is really high. They use it for sports, film, and all sorts of TV projects.

Meet the all-new PAI & Utopai X, highest-ranked model from a U.S.-based company on Artificial Analysis’ Text-to-Video Leaderboard with Audio. Utopai X works inside PAI, our production intelligence engine, where workflow and creative decisions connect across pro-level productions.

1
25
14,291