
- Tweets 47
- Following 20
- Followers 0
- Likes 2,484


vmarcelo retweeted

Penis implies the existence of vagina however I have not confirmed this theory yet
34
1,962
37,478
368,644


nice someone noticed my recipe

This 27B model runs entirely on a 16GB AMD GPU at 43.7 tps and still supports a 65K context.
So another interesting post-train is running ...
🧠 Swift 1.5 Qwen3.8-27B
🎮 RX 9070 XT 16GB
📚 65K context
🚀 43.7 tps
At 131K context?
🚀 37.4 tps
So how is a 27B fitting in there?
UkisAI released GSQ-RCO GGUFs that squeeze Swift 1.5 down to these...
🤏 IQ2_XS → 8.42GB
🧠 IQ2_S → 9.26GB
⚡ IQ3_XXS → 10.09GB
🎯 IQ3_S → 11.77GB
And the MTP versions are only ~0.35GB larger.
Swift was post-trained specifically to stop Qwen from overthinking.
UkisAI reports 58.5% fewer thinking tokens than base Qwen3.8-27B while scoring 0.35% higher.
This is how larger models keep moving onto smaller hardware.
🔗 Link in ALT

ALT https://huggingface.co/ukisai/Swift-1.5-Qwen3.8-27B-GSQ-RCO-GGUF
5


vmarcelo retweeted

This matches the performance of GTX 1650 and probably consuming under 10 Watts of power

Here's the full GTA V benchmark running in Vapor on an iPhone 18 Pro Max
City drive: 66 FPS average
Other scenes: 80 FPS average
• 1080p, DirectX 11
• High textures
• FXAA, 16x AF
• 75% population density
• 50% distance scaling
• Sharp shadows, MSAA off
• Everything else on Normal
Still a work in progress, and I have some minor issues left to fix.

33
128
7,069
328,947
vmarcelo retweeted

THE MOST Amzing thing in Local AI this week is this optimized Qwen 3.8 model:
ukisai/Swift-1.5-Qwen3.8-27B-GSQ-RCO-GGUF
It can fit under 16gb of vram with full context, at 30tk-80tk/sec on a 10 year old GPU setup

24
49
612
32,188
This maybe the only "someone should" post i will ever make, but what about taking the Berserk anime from 2016 and using Minimax H3 to make it look good?
6
Ive made a quant for the new thinking cap qwen3.8 27B huggingface.co/vmarcelo/Thin…
3
vmarcelo retweeted


An update on how we confirm your age group on Discord from @svishnevskiy. Read the full blog here: discord.com/blog/safer-for-t…


19
1,619
11,264
95,706


I looked into this recently, and I bet over 95% of real-world use cases for Astra could easily run on Qwen 3.8-27B.
Most people use AI for basic tasks that do not need frontier-level intelligence.
They just want the newest, strongest model because that is human nature. It is like buying a Lamborghini when the speed limit is 65 mph.
A Toyota Corolla gets you to the same place, and honestly, it is probably a more comfortable daily ride.
The only real difference? A supercar at least feeds your ego and lets you show off.
Astra does none of that.
You are just overpaying for utility.
59
29
557
31,801
vmarcelo retweeted

🚨Qwen4家族首次曝光!!
刚刚,在2026年云栖大会的开幕式上,新任@Alibaba_Qwen LLM负责人刘大一恒官宣了即将到来的Qwen4家族!
包含Qwen4-Max
Qwen4-Flash&Qwen4-Plus
还有Qwen4-27B!!!
未来Qwen会训5-10T的模型

98
298
2,247
411,555
vmarcelo retweeted

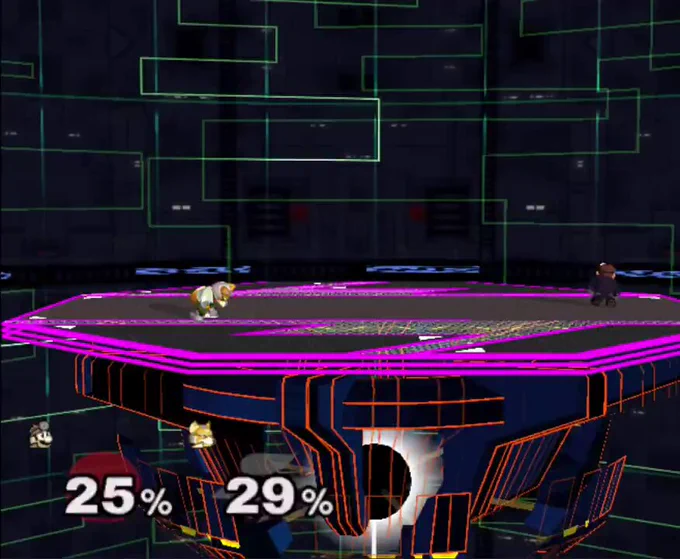
MeleeVS v1.0 - A Super Smash Bros. Melee Tag Fighter Mod.
It features:
- Assists for every character
- Active Tag
- Multiple 'Freestyle' tags
- 2XKO-Like Duos
- Tag Animation Canceling
VERSION 1.0 OUT NOW
Online Play Coming soon
Link in Bio

42
586
5,237
286,167
vmarcelo retweeted

I'm using @typesafeai's Jev to orchestrate a 3D character's entire performance.
Mouth, brows, eyes, cheeks, gaze and body: ten decisions per message, composed live into one coherent reaction. No preset expressions.
Building @mutuals_inc


After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution

28
88
790
113,394

The first ever Teddy #EarthBound edit

49
2,514
13,048
439,405


Today, we’re announcing Ternary Bonsai 2 27B.
Based on Qwen3.8 27B, Bonsai 2 27B is 9x smaller than its full-precision counterpart while retaining 98.2% of its aggregate benchmark performance.
Two months after the first Bonsai 27B release, the biggest change is quality. The footprint remains 5.9 GB, but the gap to full precision has narrowed materially, with particularly strong gains in agentic coding, multimodal reasoning, and long-horizon tool use.
Ternary Bonsai 2 27B is available today under Apache 2.0.

640
1,573
15,548
5,440,867
vmarcelo retweeted

you can just hallucinate the entire internet with Qwen 3.8 27b running at 2,000 tokens/second?
part 2 of turning @cerebras + @Alibaba_Qwen 3.8 27B into an OS:
built an offline browser with zero network calls and mounted it directly the JIT ubuntu desktop.
no wifi. no scraping. zero packets sent to external CDNs.
you search a site, set a year, and qwen 27b at 1,950 tok/s synthesizes the entire DOM on the fly.
here is youtube in 2045 vs 1999:
→ search google for youtube inside the OS
→ scrub to 2045: instant futuristic feed
→ scrub to 1999: raw web 1.0 time capsule in seconds
at this speed, browsing isn't retrieving files from a server, it's querying an alternate reality.
a 2D browser window is just step zero.
imagine full operating systems, virtual worlds, and complex simulation engines existing purely as model weights. zero gigabytes stored on disk, just pure interactive reality streamed on demand.
What else becomes a possibility with the qwen 3.8 27b (dense) at 2000 tokens/sec?


Operating System powered by Qwen 3.8 27B at 1950 tokens/sec!
here is what 1,950 tokens/second @Alibaba_Qwen's 3.8 27b actually looks like on @cerebras:
i wrote a minimal python web server that turns cerebras inference into a live operating system.
zero apps on disk.
when you double click an icon:
1) python proxies a raw SSE stream from qwen 27b at 1,950 tok/s
2) calculator compiles & mounts in 11s
3) full canvas paint studio with brush engine compiles in 10s.
at 2,000 tokens/second, software is just an on demand hallucination that runs instantly.
the model weights ARE the operating system runtime.
what else would you build at 1,950 tokens/second?

157
354
4,979
1,691,545