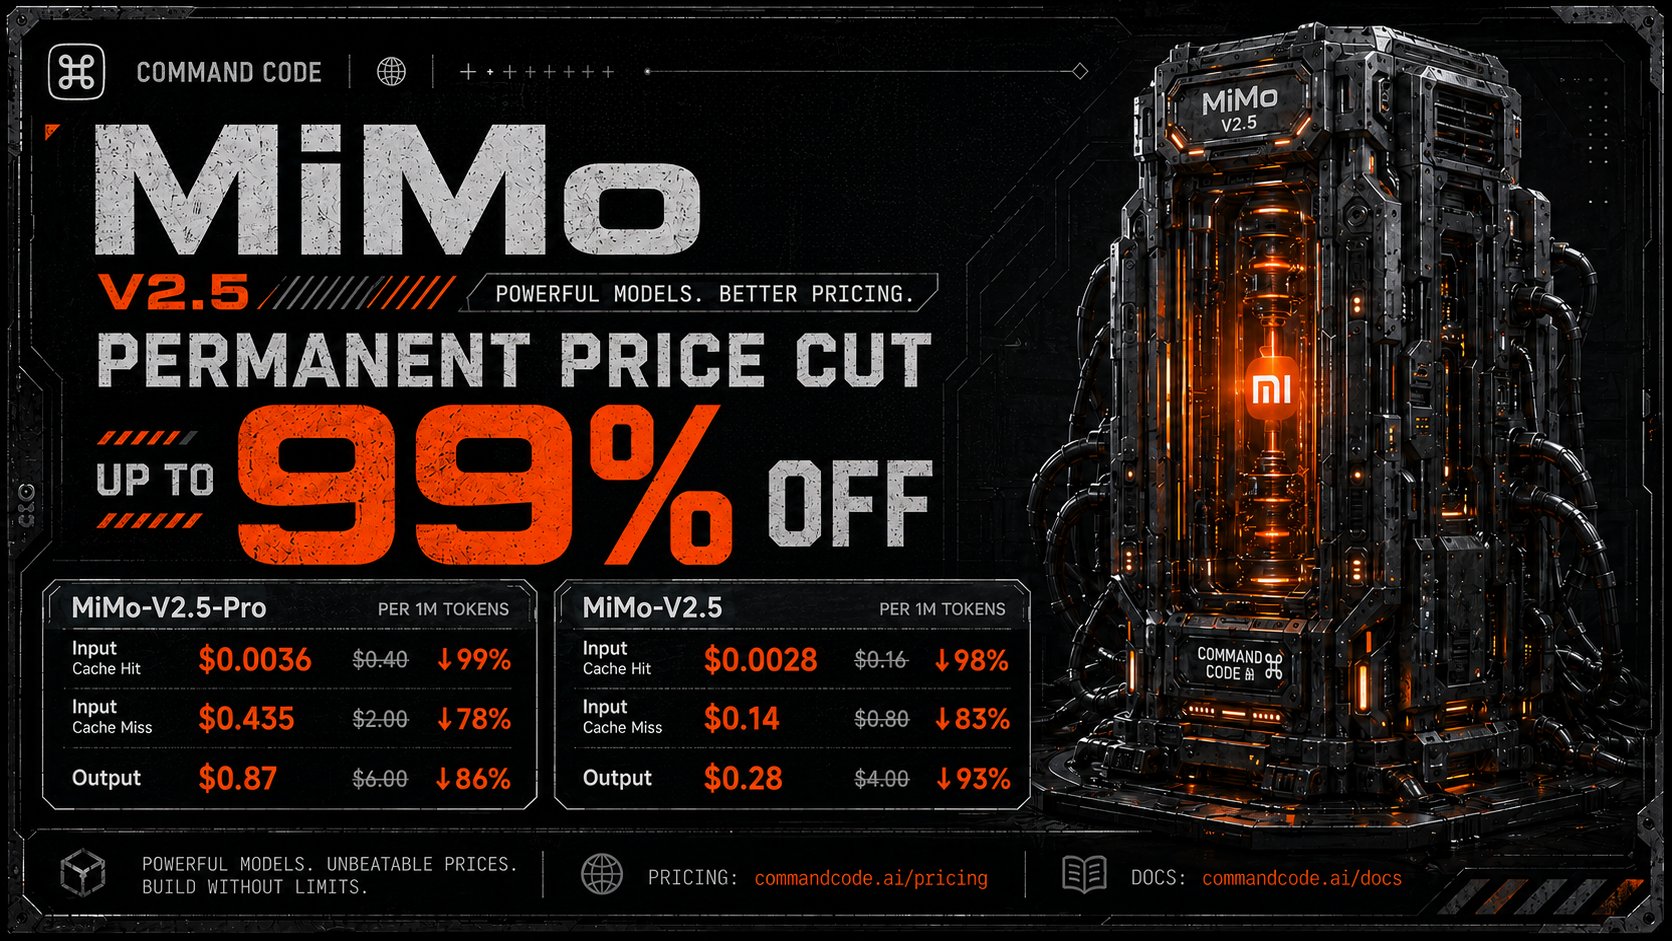
🚀 Better inference efficiency, lower costs, broader access. MiMo-V2.5 Series API pricing is now permanently reduced — by up to 99% compared to previous pricing. ✨ Unified pricing across all context lengths. MiMo Token Plans have also been upgraded: • 5–8× more usable tokens at the same price • Simpler and more transparent billing rules 🎁 As a thank-you to current users, all current Token Plan credits will be fully reset. 🎧 MiMo-V2.5-TTS remains free for a limited time. ⏰ Effective May 26 at 6:00 PM PDT. These improvements are powered by continued inference optimization and serving efficiency upgrades across the MiMo stack. 🛠️ We’ll also publish a detailed technical blog on the inference optimizations later — stay tuned.

May 26, 2026 · 4:41 PM UTC

296
503
4,192
1,164,829
🎉 The Xiaomi MiMo 100T Token Grant for Builders Program has officially concluded. Since launch on April 28, developers around the world have claimed all 100 trillion tokens ahead of schedule. 🛠️ Thanks to everyone building with MiMo! The Apache Software Foundation committers benefit program will remain available long-term and is not affected by this conclusion. 🎁 More updates for previous Token Plan subscribers will be announced next week.
19
9
239
50,802
Sort replies: Relevant Recent Liked
Replying to @XiaomiMiMo
Oh no, how do I choose now
3
6
157
10,695
Replying to @XiaomiMiMo
Shipping on $1 Go plan of @CommandCodeAI today! Have fun everyone!! 🥳
7
3
51
2,448
Replying to @XiaomiMiMo
go Mimo!
1
46
2,587
Replying to @XiaomiMiMo
This makes MiMo V2.5 our most cost efficient model (pre-discount cost shown), and one of the highest performance overall in agentic coding tasks, exceeding both DeepSeek V4 models. Data at gertlabs.com/rankings?mode=a…
2
38
7,163
Replying to @XiaomiMiMo
this is actually so insane wtf thank you deepseek for the competition causing this 🙏
20
2,321
Replying to @XiaomiMiMo
$1 Go plan of @CommandCodeAI is the best way to get this deal now. Just shipped it live.
MiMo-V2.5-Pro & MiMo-V2.5 are now ~99% off on Command Code. This is like 100x more usage! Input, output, and cache pricing are all lower. Works on every plan + extra top-ups. Pick the /model and go! Our $1 Go plan with $10 in it is perfect for this. Let's go!
1
12
2,095
Replying to @XiaomiMiMo
DeepSeek has really shaken up the entire AI market. Their aggressive pricing strategy forced everyone else to rethink their models, and now we're seeing Xiaomi follow the same playbook with these massive cuts on MiMo-V2.5. The competition is getting insane this is great news for developers and users! thanks XiaomiMimo!
2
2
210
10,138
Replying to @XiaomiMiMo
You upped the tokens but also upped the usage amount for similar tasks by a higher % it’s been a net negative for similar tasks in my token plan.
1
1,398
Replying to @XiaomiMiMo
Have good experience with Models V2.5-Pro! Good one! Love to subscriptions
3
754
Replying to @XiaomiMiMo
99% pricing reduction is insane if the quality holds up 👀
1
1,491
Replying to @XiaomiMiMo
this is massive. the real unlock isn't just reducing costs, but scaling access to quality infrastructure for the next big builder.
1
424
Replying to @XiaomiMiMo
cc @MatthieuTalbot les chinois font littéralement exploser le ratio intelligence / prix en ce moment. Entre DeepSeek et eux ...
1
187
Replying to @XiaomiMiMo
another %99 please 😅
132
Replying to @XiaomiMiMo
这降价太狠了,给力
274
Replying to @XiaomiMiMo
🚨My Personal Chinese Leaderboard — June 2026 #1 Qwen 3.7 #2 Kimi 2.6 #3 DeepSeek 4 #4 GLM 5.1 #5 Minimax M3
405
Replying to @XiaomiMiMo
Billions served
511
Replying to @XiaomiMiMo
Welp xD gave deepseek a shot a few hours ago, time for another experiment
599
Replying to @XiaomiMiMo
Great model.
919
Replying to @XiaomiMiMo
what the hell just happened ? this is crazy. Compare this to deepseek v4 series prices
3
49
6,299
Replying to @XiaomiMiMo
a 99% price cut usually makes me wonder what the margins looked like before. i’ll wait for that technical blog to see if this is just getting back to sustainable costs.
1
39
3,945
Replying to @XiaomiMiMo
every chinese lab give us something to be happy about this week
thehype analyzed a post by @MiniMax_AI's head of engineering announcing the m3 model and its architecture. here's what we've found out in most llms, every time the model needs to understand something or generate the next word, it has to scan the entire conversation history from top to bottom. this process is called attention – the model "attends" to everything you've said, weighing what's relevant. normally this happens in one pass: read everything, all at once, every single time m3 splits this into two separate passes instead: • pass 1 – the scout. a tiny "scout query" skims the whole context and scores blocks of tokens. it picks the top-k most relevant blocks. think skimming a table of contents • pass 2 – the real read. the full attention queries only look at the blocks the scout flagged. everything else gets skipped different query groups can focus on different parts of the context at 1 million tokens of context, m3 is way faster than normal attention: • loading and processing a huge prompt (prefilling): 9.7x faster • generating each new token (decoding): 15.6x faster why is decoding even faster? because normally, every time the model spits out a single word, it has to re-read the entire conversation history. that's like flipping through a whole book just to write one sentence. m3's scout already flagged the relevant pages, so it only checks those. massive time saver at 32k tokens, m3 and normal attention are basically the same speed. the scout step adds a tiny bit of overhead, so it only makes sense when the context is really long. this thing is built for giant conversations and agent tasks, not short chats what this actually means: 1. context window is going way up. their previous model m2.7 capped at 200k tokens. m3 is benchmarked at 1m – a 5x jump 2. the way m3 chooses which blocks to read isn't based on fixed rules (like "always skip every other block"). it learns what's relevant on the fly based on what you're asking 3. if quality holds, m3 can serve million-token agentic workloads at near-200k prices. nobody else is touching that follow @thehypedotnews for 24/7 ai news, analysis and breakdowns
25
4,920
Replying to @XiaomiMiMo
The war that started with Deepseek.. Really happy with Xiaomi following suit...Mimo-v2-pro was my favourite model for a good amount of time...Shifted to deepseek for a lot of experimentation...but now it becomes interesting again..
19
3,396
Replying to @XiaomiMiMo
That's a lie. It becomes even worse. One prompt, "HI," consumes 3-5% of tokens. I hope somebody will sue your company for this bullshit.
7
18
4,282
Replying to @XiaomiMiMo
i was refreshing my dashboard and literally tought there was a bug. omg this is insane
16
2,297
Replying to @XiaomiMiMo
wait this is basically same price as Deepseek V4 pro?
3
10
8,963
Replying to @XiaomiMiMo
This is amazing! Unbelievable pricing, cannot wait for V3!
11
1,734
Replying to @XiaomiMiMo
Are these models actually good. The only one I've had good experience with is Deepseek V4. Kimi and GLM have been very unimpressive (based on vibes). Deepseek is a slightly less reliable Sonnet 4
15
9
6,495
Replying to @XiaomiMiMo
Wtf I bought pro and had 700 million, now I got 38billion tokens, thats crazy a lot! Thanks xiaomi, your model is great btw!
1
7
2,491
Replying to @XiaomiMiMo
@opencode do these limits apply to go plan right now
7
1,068
Replying to @XiaomiMiMo
99% price cuts would’ve sounded impossible in AI like a year ago 👀 The model race is rapidly becoming a cost-efficiency war, not just a capability war.
1
4
1,118
Replying to @XiaomiMiMo
the benchmark breakdown between mimo v2.5 pro and deepseek v4 pro is something. same price, same tier, trade-offs only at the margins
xiaomi follows deepseek's playbook: mimo-v2.5-pro api now matches deepseek-v4-pro pricing to the cent benchmarks (mimo vs deepseek): • gdpval-aa (general agent elo): 1581 vs 1554 ✅ • τ³-bench (tool-use): 72.9 vs 71.8 ✅ • claweval (function calling): 63.8 vs 59.8 ✅ • humanity's last exam (frontier reasoning): 48.0 vs 48.2 🟰 • swe-bench pro (real-world coding): 57.2 vs 55.4 ✅ • swe-bench verified (coding fixes): 78.9 vs 80.6 ❌ • terminal-bench 2.0 (shell tasks): 68.4 vs 67.9 ✅ artificial analysis (mimo vs deepseek): • intelligence index: 54 vs 50 ✅ • speed (median tok/s): 53 vs 54 🟰 • latency: 3.81s vs 1.86s ❌ same price, near-identical capability, trade-offs only at the margins. the chinese frontier is commodifying – and the price war is just getting started follow @thehypedotnews for 24/7 ai news, analysis and breakdowns
1
6
1,139
Replying to @XiaomiMiMo
By the way i've used mimo v2 pro for 2 weeks beginning of april. It was honestly very good ! Excited to play with tthis model, the prices are insane
6
2,985
Replying to @XiaomiMiMo
I don't get the credit to token conversion... Is the output of 600 credits per token or per million token? How does it work exactly? Like with 4.1 billion credits.. what does that translate in tokens?
5
4
6,004
Replying to @XiaomiMiMo
Switched immediately!
4
1,280
Replying to @XiaomiMiMo
Don't get fooled here. Credits != Tokens. A ping prompt in opencode showed around 8k tokens in it, while in Xiaomi Console, it shows around 2 million credits.
1
4
1,430