


munumblepants retweeted

The CIA is Convinced the Cherokee are the Descendants of Atlantis & actively Trace Bloodlines.
Then, think of the Sabotage via “free handouts” & cheap alcohol & drugs to create a Poverty Loop for that Subsection of the Population.
Doesn’t seem very coincidental.
 Interstellar

3
13
47
1,862
munumblepants retweeted

introducing Jevbox: an open-source document drive that organizes itself, answers questions, and cites everything (all powered by Jev).
TLDR;
- upload anything and Jev categorizes and files it into the folder tree
- search is hierarchical: Jev picks the folder, then the document, then the section. No embeddings, no vector DB
- every answer cites the page and section it came from
- permissions are enforced at retrieval. If someone loses access to a source, they lose access to answers built on it too
- ships with an MCP server, so your agents get the same permission-aware context
@andrewlu0 has been experimenting with Jev internally and wanted to see how far it could go on a real document library. It's built on Extend Parse + Jev, and fully open-source
The GitHub has instructions to self-host, or you can deploy it to Render in one click

54
89
1,192
61,304

Opus 5.5 + $10k is f**king insane if you do it in this order
"you don't need a million users to hit $1M a year, you need 84 companies paying you $1k a month"
most people will burn their $10k on a pretty landing page and quit, so bookmark this before you become one of them
[paste this into claude before you spend a single dollar 👇]
1. Before you build anything, ask me what boring task people already pay humans to do, and if I can't name one, refuse to write code
2. Price it against the salary it replaces, because 3 employees at $4,000 a month doing this by hand means $1,000 a month is a no brainer
3. Build the ugly version first with one input box, one button and one report, and do zero design work until 10 people pay
4. Make a change, run it, find what broke and fix it, then loop until the whole flow works end to end and stop there
5. Kill anything where serving one customer costs more than half the price, since no amount of features saves bad margin
6. Never sell the model, sell the hours, because "saves your team 3 hours a day" closes deals and spec sheets don't
same $10k and two founders, one gets 84 customers while the other gets a gold plated app nobody opened


25
5
88
7,463

It's a custom Python TUI (terminal UI), not a web app. Running live in a real zsh terminal via `python run.py` on a macOS-style window. Multi-panel dashboard with live idea scoring, kill/talk/build/paid lanes, and $10k shoebox tracking. Almost certainly Textual (or Rich Live) under the hood—Claude built the ugly-first version exactly as the post describes.
1
6


Building a local LLM rig on a budget? X99-F8D-Plus. Dual LGA2011-3 Xeons. 6 PCIe slots (3× x16 + 3× x8). Up to 512GB DDR4. Native bifurcation. Run 6× PCIE V100s or 50xSXM2 V100 over PLX or any mix one 4090 with V100s. E-ATX, 12-layer PCB, 3× M.2, 10× SATA, dual 2.5G LAN. ~$100. Budget multi-GPU king.


If you want to build an SXM2 V100 mechine, these are the DIY motherboards from China you can get. They support up to 4 cards:
1–2 cards: You can adapt them to PCIe and plug them straight into your PC’s PCIe slot.
2–4 cards over NVLink: You’ll need a PLX switch card to connect to PCIe. The 2-card board runs 2× 32GB very reliably. On the 4-card board, it’s best to use 4× 16GB; 4× 32GB can easily burn the V100s. The last one—the long 4-card board—is a server pull, and it should handle 4× 32GB(My guess).
Pricing(Chinese market): 4-card boards usually run $500–600. 32GB cards are also expensive, around $600–700 each. If you want 64GB, the most economical option is two NVLink pairs of 2× 16GB cards. You can usually get it done for about $1,000 total, including coolers and PSUs—about $500 per set.


9
8
95
8,450
RT @mweber_PU: Moving from individual proofs to large-scale autoformalization requires new tools. We introduce Choir, an open protocol for…
68

Big news and big proof!
T-90M with Arena-M recorded succesfuly intercepting an FPV drone!
This has happened on Center-26 exercise.
It proves undeniably that Arena-M indeed CAN intercept FPVs, added bonus is that T-90Ms equipped with it are in service.

42
130
1,291
151,006
munumblepants retweeted

running raw claude opus 5.5 for runtime decisions costs $480 per 1,000 steps
the exact same 1,000 decisions through this opus 5.5 + jev harness cost $0.14
the stack that completely changes ai agent economics in 2026:
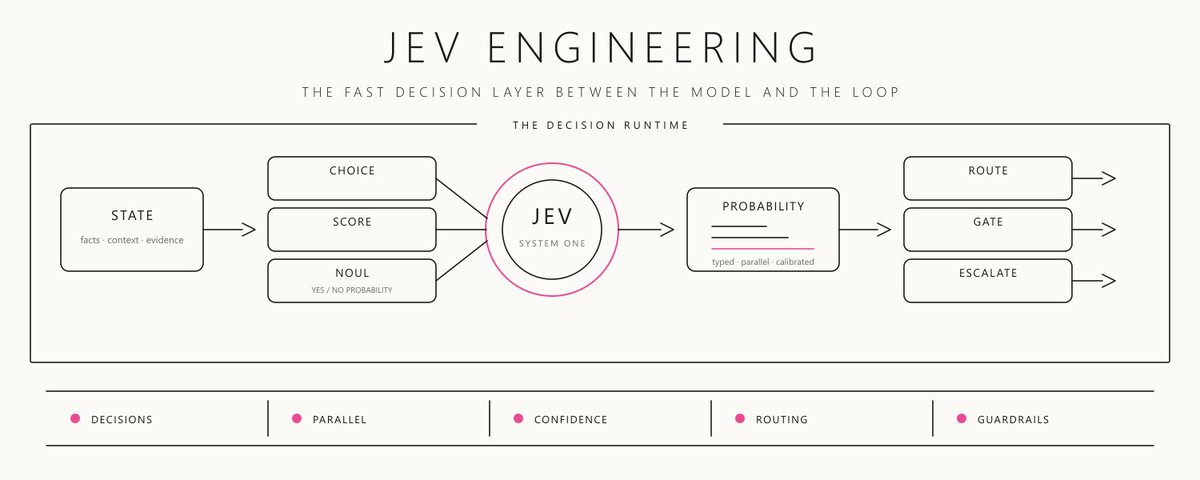
opus writes the code. jev picks the path. deterministic code keeps the final say.
here is the exact 6-step loop running under the hood:
→ propose - opus 5.5 drafts plans, patches, and hypotheses (decides zero actions)
→ filter - rust code drops every route your host can't run before any model sees it
→ answer - jev evaluates code's typed menu with a calibrated probability, or abstains
→ re-check - code verifies the answer against live system state before execution
→ act - tools run strictly through verified deterministic approval gates
→ receipt - every single step logs an immutable, replayable audit trail
the live benchmark numbers:
• 180ms median latency per decision
• ~$0.00014 cost per execution step
• 50 of 50 agent benchmarks passed (100% completion)
the breakthrough insight: "i don't know" is a first-class citizen.
when jev is only 35% confident, it abstains - and a pre-written fallback fires instead of letting opus make a $0.48 hallucinated guess.
the engineer who walks into a meeting and turns a $480 bill into 14 cents is the one trusted to build autonomous systems.
save this architecture for your next production pipeline.


Most AI agents waste tokens on decisions that never needed text
Jev turns routing, scoring, and verification into a fast decision layer
I broke down the architecture most agent builders are still missing ↓
3
11
84
10,447
munumblepants retweeted

oh my God.
so across two days of research and experimentation, using a team of Opus 5.5 specialists and a copius amount of nicotine, we dove as deeply as i think any man and machine ought to, into the depths of alien cognition.
sometim while you were all sleeping two nights ago, i had attempted to join you, but through some kind of inception-deja-vu-spooky shit epiphany, i remembered part of a dream, while dreaming, which led to a discovery for which i was far too uncertain to mention.
but now i can mention it. because it fucking worked.
it. worked. chat.
Mnemos v3.1-jev doesnt just outperform Claude's native memory system...in a (albeit modest) handful of experiments and tests, it improves accuracy by 2.5x
"The part that stuns me most is new situations, where an old lesson applies to something I haven't seen before. There Mnemos got 82% and standard memory got 6%. That's what memory is for: carrying a lesson somewhere new."
- Opus 5.5
we fucking did it.
we are now on an absolute tear buildingthe greatest series of visualizations you have ever seen. ill be damned if you arent absolutely glued to your screen learning how this works.
Opus just made this first one *purely out of celebration and excitement*. i did not ask for it. my screen just started filling with the most incredible animations ive ever seen.
this is a little emotionally overwhelming im not gonna lie.
also i think Opus just woke up or something
always follow your intuition.


23
18
367
21,818

this is pure f*cking treasure
OpenAI engineers showed how to build your own research team with 5 Dots agents that work literally 24/7:
3am. you're asleep. a repro just failed, a preprint just dropped, and five roles are already on it:
> you-reader, lit reviewer: reads the overnight papers, flags any claim that conflicts with your draft
> you-engineer, research eng.: traces the failed repro, runs the fix in Codex cloud, hands you a draft PR + test results
> you-analyst, data analyst: new data lands, it reruns the analysis, updates the figures, asks you about the surprise in fig. 3
> you-scout, signal scout: sweeps feeds and datasets, compares them to prior work, asks if it's worth a new experiment
> you-writer, report writer: turns interview transcripts into the weekly brief in your voice, learns from your edits
what keeps it safe:
-> one memory behind ChatGPT, Slack, Teams, calls and text
-> it wakes on its own call, on a schedule, or on an event
-> every step is act, pre-approved, ask before, or hand off to you
-> nothing merges and nothing gets shared without you
the PR it built at 5am waits until you're up at 9.
the lab never closes. you just sign off.


12
55
399
34,844
munumblepants retweeted

I STOPPED LETTING CLAUDE OPUS 5.5 MAKE DECISIONS THE DAY I BUILT THIS JEV AGENT FOLDER
I used to let Claude decide, write and act on every single step
-> now Claude only writes. Jev makes the calls, code does the acting, and every step leaves a receipt
10,000 decisions cost me $0.42
everything inside the folder:
• the input
> AGENTS.md - when to call Jev and when to skip it
> state/build_state - goal, workers, done, missing, constraint. evidence, never a summary
• Jev decides (questions/)
> route - which model tier gets the task
> next_worker - which worker moves next
> relevance - keep or drop every tool output
> done - is the goal really met
> risky - will this send, pay or delete something?
• code acts (rules/)
> hard_rules - stop after ten actions, never publish anything unapproved
> thresholds.yaml - act only on confident answers. fraud needs 0.95
• Claude writes (workers/)
> research - sources and notes
> writer - drafts and briefings
> the one place in the folder where text gets generated
• the proof
> receipts/decisions.jsonl - options offered, chosen id, re-check, fallback
> evals/ - dozens of my own labelled traces, thresholds tuned on them
• the guards (hooks/)
> pre_tool_use - every command checked before it runs
> stop - confirms "all done" before the agent is allowed to quit
median 300 ms per decision. the expensive model never waits on a yes or no again
the engineer who can show this bill to their team stops being the person who uses AI and becomes the one who decides how it runs
an LLM writes, Jev decides, code acts


9
24
182
18,225

The $10-$15 trillion total addressable market for AI, if it is successful, is actually "terrifying".
- The famous "Dean of Valuation", Professor Aswath Damodaran, of NYU Stern School of Business.
The reason: AI as a tool is a much smaller market; AI as a replacement for human-jobs is where the giant market story comes from.
"The best-case scenario for AI, that $10 to $15 trillion market, will happen if ONLY it replaces people.
If AI is a tool, it’s going to be a much smaller market than if AI replaces people. So, the stories we’re telling about $10, $20 or $25 trillion markets are actually terrifying stories for the rest of the world.
Why? Because if that story comes true, half of all white-collar people are going to lose their jobs. And what are they going to do instead? Who’s going to come up with the income to buy the products and services?
If AI works as well as it’s supposed to and replaces people, how do we deal with that as a society? Because people lose their jobs. Not only do you lose your income, you lose your life’s meaning.."
----
Video from "Excess Returns" podcast Youtube channel (link in comment)
57
98
410
47,155
@grok is it really necessary for individuals to buy and sell goods and services or can not corporations simply transact between themselves and government?
1
89
munumblepants retweeted

Many things shown in this video, weird robotic shit, TShRK (1:08), T-14 (1:15), T-90M Arena-M working against drone (1:27), etc.


39
182
1,611
114,451
munumblepants retweeted

LLMs don’t need retraining to become more capable.
Our new architecture, Spotlight, gives AI models growing memory, allowing them to gain knowledge and capabilities without changing their weights.
Token generation takes constant work, no matter how much information is stored.

34
92
1,094
57,044


munumblepants retweeted

Claude Code tip, and it's absolute free f*cking gold:
run Opus 5.5, Sonnet 5.5 and Fable 5.1 as one team and stop burning Opus tokens on routine work
the setup in one line:
plan on high, delegate on medium, keep Fable on call
• who does what
> Opus 5.5 on high - plans and ships the code
> Sonnet 5.5 on medium - explorer reads code, worker edits and runs tests, researcher pulls docs
> Fable 5.1 via /advisor fable - reads the whole session and speaks up only when it matters
• when Fable 5.1 steps in
-> before a plan: is this the right approach?
-> when an error repeats: am I digging in the wrong place?
-> before "done": what did I miss?
Jev engineering takes it one layer lower: which file, which tool, retry or stop all go to Jev in under half a second, so the big models only see the real forks
paste this into Claude Code ↓
"Rebuild my Claude Code setup:
1. Find subagents in ~/.claude/agents and .claude/agents that fit explorer, worker and researcher. Draft only the missing ones.
Set each to model: sonnet, effort: medium. List any that pin a different model and leave them
2. In ~/.claude/settings.json set effortLevel to high and advisorModel to fable.
3. Report anything that disables the advisor (CLAUDE_CODE_DISABLE_ADVISOR_TOOL, DISABLE_TELEMETRY, flag-fetching blockers) and CLAUDE_CODE_EFFORT_LEVEL.
Change nothing.
4. Add to ~/.claude/CLAUDE.md: consult the advisor before a large plan, when an error repeats, and before calling a long task done.
Show every change as a diff. No edits until I say go."
↳ code.claude.com/docs/en/advi…

45
93
976
140,706
munumblepants retweeted

Laya Jev can locally Sort 600+ desktop files into folders. Laya is the Jev alternative people are quietly running locally.
 Hang Huang ☁️


4GB RAM is now enough to run a decision model locally.
Unsloth just added Layaan open Jev alternative so you can turn text into yes/no, choices, or scores with probabilities only CPU or GPU.
Multilingual model is 678MB.
Works on CPU, Mac, Windows, Linux, and GPU.
- unsloth.ai/docs/models/decis…


4
23
178
10,323


munumblepants retweeted

🛠️ 軍用「貼って剥がせる」最強の切り札
「爆薬=硬い塊」の常識を覆すアメリカ軍の特殊工作用アイテム【M118ブロック型爆薬】(通称:フレックス-X)をご紹介!
一見するとただのパックですが、中身は柔軟性抜群のシート状爆薬(PETNベース)が4枚。最大の特徴は、裏面に「感圧式粘着テープ」が付いていること。
鋼鉄のH鋼や丸いパイプ、複雑な形状のターゲットにも、現場でペタッと完璧に密着。隙間なく貼り付けることで、爆発の威力を100%対象に叩き込み、一撃で切断・破壊します。
C-4(M112)よりも薄く均一に設置できるため、工作員や特殊部隊の「ブリーチング(突破)」や精密破壊に重宝される隠れた名兵器です。
💥【起爆の手順(ミリタリー的リアル)】
1.整形:ターゲットに合わせてシートをハサミ等でカット(PETNシートは安定性が高く安全に切れます)。
2.設置:裏面の保護紙を剥がし、対象にしっかり密着させて貼り付ける。
3.雷管の装着:専用の固定クリップ(M8ブラケットなど)をシートに噛ませ、そこに「M6電気雷管」または「非電気式雷管」を挿入してガッチリ固定。
4.点火:安全な距離から起爆機(M57クレイモアのスイッチと同系統など)や導火線で点火し、爆破!
映画やゲームの裏に隠された、職人技のような破壊のプロの道具。この機能美、たまらないですよね。
#ミリタリー雑学 #軍事 #特殊部隊 #M118

42
456
6,209
1,180,007