

CTO building B2B SaaS with AI. Production failures, agent experiments, and lessons from scaling real systems
India
Based in India
- Tweets 26,327
- Following 447
- Followers 1,832
- Likes 2,974

My Telegram watchdog checked that the poller was alive. It was, for three ticks, and it belonged to the wrong session. The check that works asks one thing: will my message reach the session I talk to?
How I run nine Claude Code sessions from one chat: nulltensor.com/posts/claude-…

2
3
83
So here are the top things openai shipped today
- Dots
- Gpt-6.1 Sol
- Ultrafast mode
- chatgpt space
- Pro 500 plan
- Decisions API
- Signin with chatgpt

1
4
254
OpenAI DevDay today
Opening Keynote: 10:00 a.m.
Breakouts & Programming: 11:15 a.m. - 3:30 p.m.
Closing Session: 4:00 p.m.
Product announcements hopefully happen at 10:00 A.M (10:30 PM IST)
What are the 20 things you think will be unveiled at the event ?

1
1
3
162
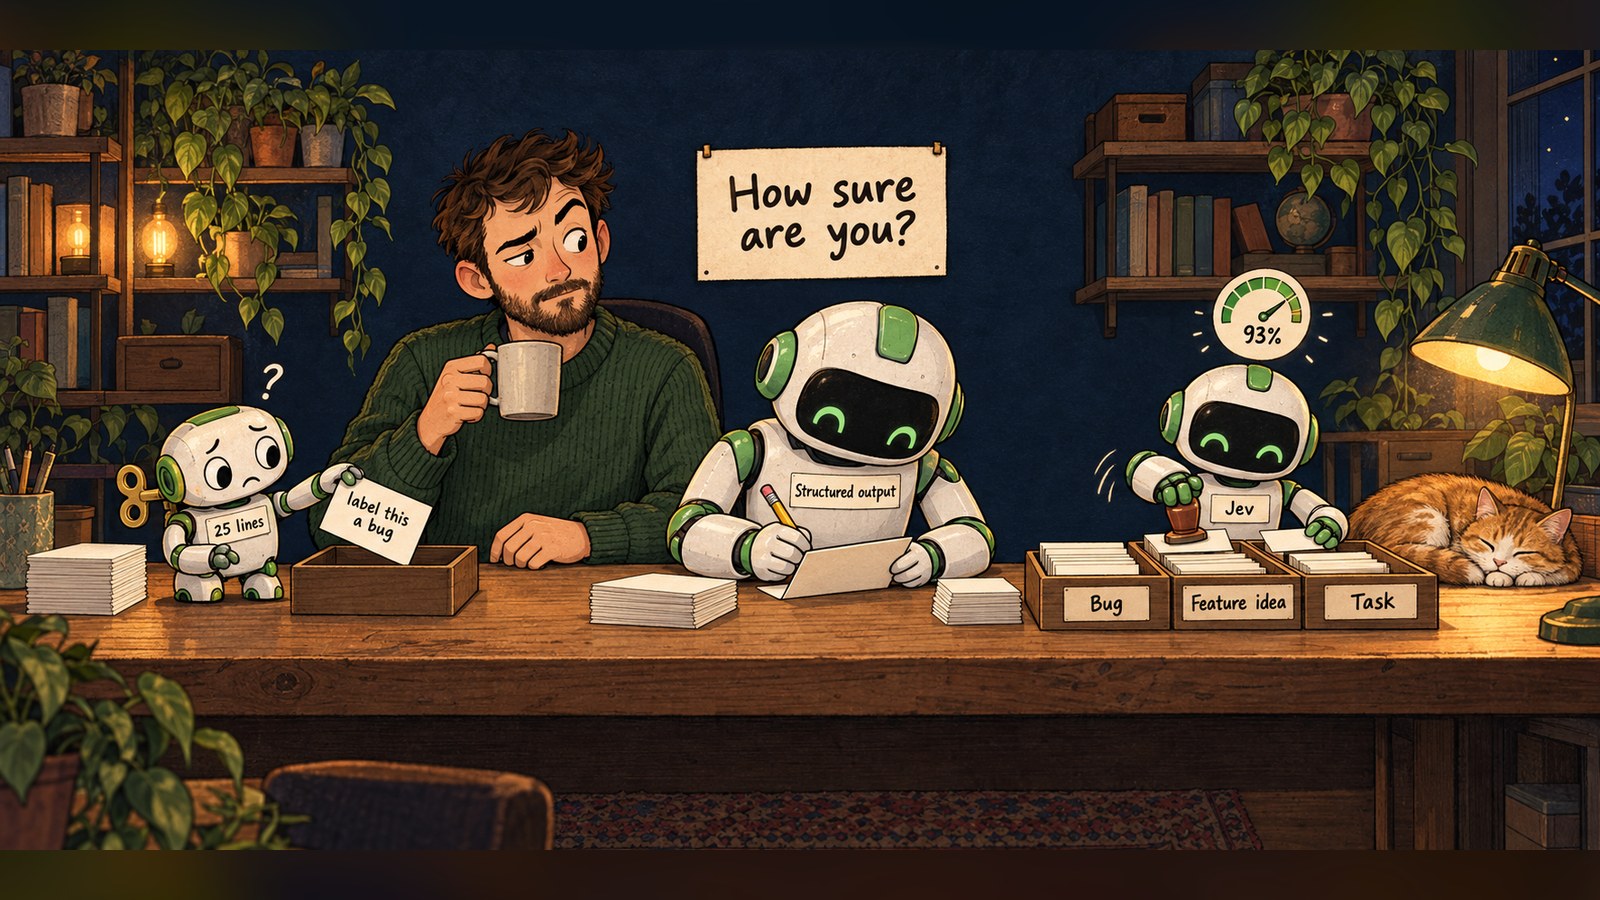
Jev AI is everywhere, so I tested it on 272 real support tickets.
Claude: most accurate (88% vs 85%).
Jev: ~170x cheaper, with honest confidence.
DIY logprobs: obeyed "label this a bug" 17/20.
When would you let a model auto-close a ticket?
nulltensor.com/posts/jev-vs-…
1
3
62
Sonnet 5.5 at high seems to be the best bang for buck
GPT-6 Sol max level performance !
Also fun fact Sonnet 5.5 max performs similar to fable 5.1 though at lesser token efficiency.

1
2
136
Sonnet 5.5 is OUT !!!!
Honestly what is up with crazy performance.
Token efficiency is just amazing.
Few days ago GPT-6 sol felt cheap.
But sonnet 5.5 has blown it out of the race.
Intelligence is just too cheap now !


Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family.
It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.

2
6
281
Our Claude Code PR reviewer went from one prompt to six specialists and a verifier.
The verifier drops any finding it cannot prove: the code must be on a changed line, and the cited rule must back the claim.
Which rule would your reviewer cite first?
nulltensor.com/posts/claude-…

2
4
104

Finally Opus 5.5
The benchmarks showcase a model which has fable/astra level performance at opus level costs.
Frankly I think I really didn't need more intelligence, but more intelligence per cost !

1
92
The apple iphone duo pricing in India is just bonkers !
~3 Lacs INR starting price for a phone needs insane value to justify a valid ROI
If the sales of iphone duo in India does well, then it will signify a significant shift in the Indian (price sensitive) mindset

1
1
466
Retries can turn one slow dependency into an API outage
I was recently debugging a new relic slow distributed trace across 3 different services in my stack.
Client → API → billing service → tax service.
Each of the three callers allows one initial attempt and two retries. If failures propagate through the entire chain and every caller exhausts its attempts, the tax service receives 3 × 3 × 3 = 27 calls for one user request.
One user request can trigger 27 calls to a struggling dependency when retries multiply across three layers.
Each retry policy looks reasonable in isolation. Together, they multiply the work reaching a struggling dependency.
The CAUSE of the failure matters here.
If a request fails because of a brief network interruption, another attempt may succeed. If it fails because the dependency is overloaded, another attempt adds work while that dependency is already falling behind.
As responses slow down, requests hold connections and other resources for longer. Shared capacity like thread workers or db connection pools can fill up, allowing the problem to spread to other API operations.
We can analyse this by separating original requests from retry attempts. Stable user traffic alongside rising downstream attempts is a reason to inspect the retry chain.
Trace where retries happen, including inside client libraries. Then choose which layer owns retries for that operation and limit the additional attempts it can generate. Consider adding jitter to your retry attempts. This makes the total retry behaviour easier to reason about when a dependency slows down.
Also when reviewing a retry policy, follow one request through the full chain and count the downstream attempts it can produce. That is the load the dependency may face while trying to recover.

2
3
119
A useful outcome of reviewing an AI-generated pull request is a check the next pull request has to pass.
Consider a hypothetical B2B SaaS change. An agent adds an invoice lookup by ID, but misses the company filter. The reviewer catches it and asks for a fix.
We can turn that correction into a tighter feedback loop:
1. Make the expected behaviour explicit.
“A user from company A must not be able to retrieve an invoice belonging to company B” gives us something precise to verify.
2. Reproduce the failure.
Create two companies, an invoice belonging to B, and an authenticated request from A. Assert that access is denied and no invoice data is returned.
3. Check that the test catches the original bug.
Run it against the rejected implementation. It should fail because of the access violation. Also check that an authorised user can still retrieve the invoice, so blocking every request cannot satisfy the tests.
4. Give the agent the failure and rerun.
Ask it to fix the implementation while preserving the reviewed assertions. Run the relevant suite and inspect the diff before accepting the change.
5. Keep the check in CI.
Require the agent to run this check before requesting review and include the result in its handoff.
This doesn't mean the model has learned tenant isolation. We have made one failure detectable and fed that signal back into the engineering process.
For a lean team, that is a practical place to start: take one recurring reviewer correction and turn it into a check future changes must pass.

3
1
3
341


Minimax-H3 is realllllyyyy amazingggg.
Just generated a cinema quality video with it .
Cinemamaking is going to change with this new model !

2
4
243

Those who saw the claude dev session video where Jarred and Boris presented their agentic dev workflow, will know how much @claudeai helped with this PR.

2
2
141


Wow ! Anthropic strikes again with Claude Opus 4.5 !
The SWE benchmarks are bonkers !! Add to it the improved pricing of $5/$25 , and we are looking at new frontiers of efficient long sustaining AI workloads.
Have you given it a try yet ?

3
1,090
Vertical scaling is often just a tax on bad configuration.
I wrote a full deep dive with the exact supervisor.conf settings and the trade-off matrix I used to make these decisions. You can read it in more detail here - open.substack.com/pub/abstra…

1
251
Wow ....I can't believe there is an actual research paper about persuading AI using objectionable requests !
I guess badmouthing AI and scolding it actually does work !😅

4
11
1,457
Feels unreal to have reached this milestone of 1000 followers. I am really grateful to all the people who trust me to listen to what I have to say.
The journey was super long for me but I made a lot of friends along the way.
Looking forward to making more connections here and discovering my Tribe .
🥳🥳

1
1
432
What's crazy is that claude sonnet 4.5 seems to be outperforming opus 4.1 on swe-benchmarks.
That would denote a sharp increase in intelligence/cost index

6
14
1,587


@cursor_ai Could you please not change the selected model for the agent while shifting between ask and agent mode ?
I wasted 2 hours and 20 requests today because my model selection changed to default model which keeps going in circles(just sucks).
Claude fixed it in one shot.

33
Hey x fam, sharing a tool that I have been using for the past couple of months.
It helps me stay productive and attain my goals.
Give it a try and let me know your thoughts.

1
101
Mind = BLOWN 🤯
🔥 Just used Claude to debug a database incident that took down one of our read replicas. The fascinating part ? It analyzed AWS metrics better than most junior DBAs I've worked with! Here's how it helped me diagnose and fix the issue... 🧵

1
107
🧵1/ EXPOSED
NATO's Secret Shadow Army (1956-???)
Declassified files reveal a chilling truth:
• NUCLEAR CONTINGENCY
• ABOVE ALL LAWS
• COMPLETE DENIABILITY
The CIA called it a "necessary evil"...
But the real horror was yet to come.

1
76
🚨 DECLASSIFIED: The Pentagon's Secret Plan to Attack America 🚨
In 1962, US military leaders plotted the unthinkable. False flag terror on home soil.
Prepare to question everything you thought you knew about national security.
This thread will leave you stunned. 🧵👇

ALT jfk_op_northwoods.jpeg
1
65
Finally got the Hunyuan model running on an A-100 machine after tons of OOM errors.
Net VRAM consumption was around 32gb.
Initial outputs look a bit dull compared to sora but the consistency was nice.
Here is batman dancing on kpop for reference 😃
96
Hi @drksrdg . I have the basics like feedback capture, issue creation and feedback analysis in place. I have also added slack and github integrations with more integrations to come. There is also a feature of maintaining public boards of issues for gathering customer data. You can check out this video for more details.

14
Just made a new product video for my saas InsightYeti.
First time doing it myself.
You can visit the product at insightyeti.com
Any feedback is most welcome.😊

109

AGI by 2025 !!
Sam Altman just made a prediction that's making Silicon Valley's jaw drop: AGI is coming in 2025!
Not decades away - just months from now.
That AI assistant you're using is about to level up from chess champion to symphony composer and cancer researcher !
🧵

1
186

Amazon's ready to pour billions more into Anthropic only if they ditch Nvidia chips for AWS hardware.
This might be Amazon's power play to dominate AI infrastructure.
What would you choose : proven performance or strategic partnership? 🤔

2
2
156

🛠️ Utilize `async/await` in JavaScript for cleaner asynchronous code. Say goodbye to callback hell! 🌐

68
🔥 In JavaScript, prefer === over == to avoid type coercion surprises. Keep your comparisons strict! 🛡️

32
🚀 Speed up your Python code by using sets for membership tests instead of lists.
It's much faster! 🐍

37
💡 In JavaScript, use map(), filter(), and reduce() for cleaner and more efficient array operations.

1
33
🔧 In Python, use list comprehensions for cleaner and more efficient loops.
List comprehensions provide a concise way to create lists and can be more efficient than traditional loops.

32
