
no bs agentic coding, from my experience building large-scale products. backend systems at scale, prev Senior SRE/backend at gorgias. paris → shanghai
- Tweets 171
- Following 83
- Followers 9
- Likes 848


RIP all-remote video interview hiring processes, hello onsite rounds
It was a matter of time, wasn't it?

The whole point of building Tavus has been simple: talking to a machine should feel as natural as talking to a friend or coworker.
It’s hard to describe all the tiny nuances that make a conversation feel human. The little expressions. Moving around in your chair. Knowing when to speak and when to listen. The dance of it all.
Griffin is by far the closest anyone has come to a model that can capture those nuances. The first time I saw it being used, I had no idea I was watching our model rather than just a normal video call.
I’m so incredibly proud of this team and what they’ve built.

260
254
5,766
677,050

LLM bots are talking in my replies, this site is having a real problem blocking these accounts. Confusingly, a lot of these bots have a blue check
Amusing but also depressing

77
9
370
25,221


Local AI nowadays is more a videogame than a real industry.
It has to mature as fast as possible, before big players will enter the market.
18
1
74
5,841

Probably an unpopular opinion: GPT-6.1 Sol is very efficient, but I currently prefer Opus 5.5 and Sonnet 5.5. Anthropic has managed to bring back Claude's great "taste," and the current Claude models are fast, efficient, and simply very good.
Honestly, I’m really excited and looking forward to Fable 5.5 right now. Sol 6.1 is good for many tasks and efficient but Opus 5.5 just feels better overall right now.
242
70
2,491
105,926
People who do bot-automated replies should be banned from X.
I barely started posting and this is already unbearable. Also, it makes it really hard for people who actually put in the work to stand out when there's a stream of slop.
6

the way these subscription plans work is there's a pool of compute and you maximize how many people it can serve
that's the only way to justify not using it for high margin api demand the sales team keeps bringing in
individuals with a lot of accounts makes it all less viable

I have 22 Claude max accounts, and the current promotion - an optional weekly reset that you can spend any time before Oct 22 -- is a lifesaver for fuel tuning. I know it makes it harder to predict their compute loads, but I'm super grateful for this reset form factor.
42
11
940
142,626

To the people hype posting "Opus 5.5 usage is unlimited"
Stop.
Anthropic is a company. As a company, their goal is to charge the customer as much as they are willing to pay and provide them a service that is as shitty as they can tolerate for a given price.
They take the temperature to determine this on socials among other sources.
If this hype gets large enough, they will actually decrease limits.
Why not do it if they can get away with it?
14

Is it just me, or is Opus 5.5 burning through the weekly usage limit much faster lately?
The weekly percentage seems to drop a lot quicker than it did when I first started using it.
Anyone else noticing this?
417
23
1,335
159,000
I had something similar. without knowing your exact setup it's hard to tell but in my case it was long running tasks busting the cash of sub-agents
One agent file cuts Claude Code usage by 25% on a feature I built with 72 agents over 64 hours. Computed call by call on the real trace.
Unlike the main convo, sub-agents only keep their prompt cache for 5 minutes, even on a subscription. If one waits longer than that on a test run or a build, its next call pays for its whole context again. In that build it happened 200 times: 31% of the total cost.
The worst was one agent polling a slow job every 10 minutes. Each check cost ~20x a normal call (chart in the reply).
The fix is a sub-agent with a 1-hour cache. Save this as ~/.claude/agents/long-cache.md:
---
name: long-cache
description: General-purpose agent whose prompt cache lasts one hour instead of five minutes. Use it for agentic work that will sit idle more than five minutes between its own turns (waiting on long builds, test suites, visual checks, or its own subagents), especially once its context grows large, since every expired cache rewrites the whole context. For short or continuously active tasks use general-purpose: its cache writes cost less.
experimental:
cacheTtl: 1h
---
Work as a general-purpose agent on the task you're given.
Then ask Claude to use long-cache for anything that runs your slow commands.
Why not give every sub-agent a 1-hour cache? Its writes cost 60% more, and 53 of my 72 agents never waited 5 minutes. For them it's pure waste.

1
11

Grok bot squatting dot.com right after OpenAI's announcement of dot is the trolliest move 🤣 Who thought that up?
20
Momo M retweeted
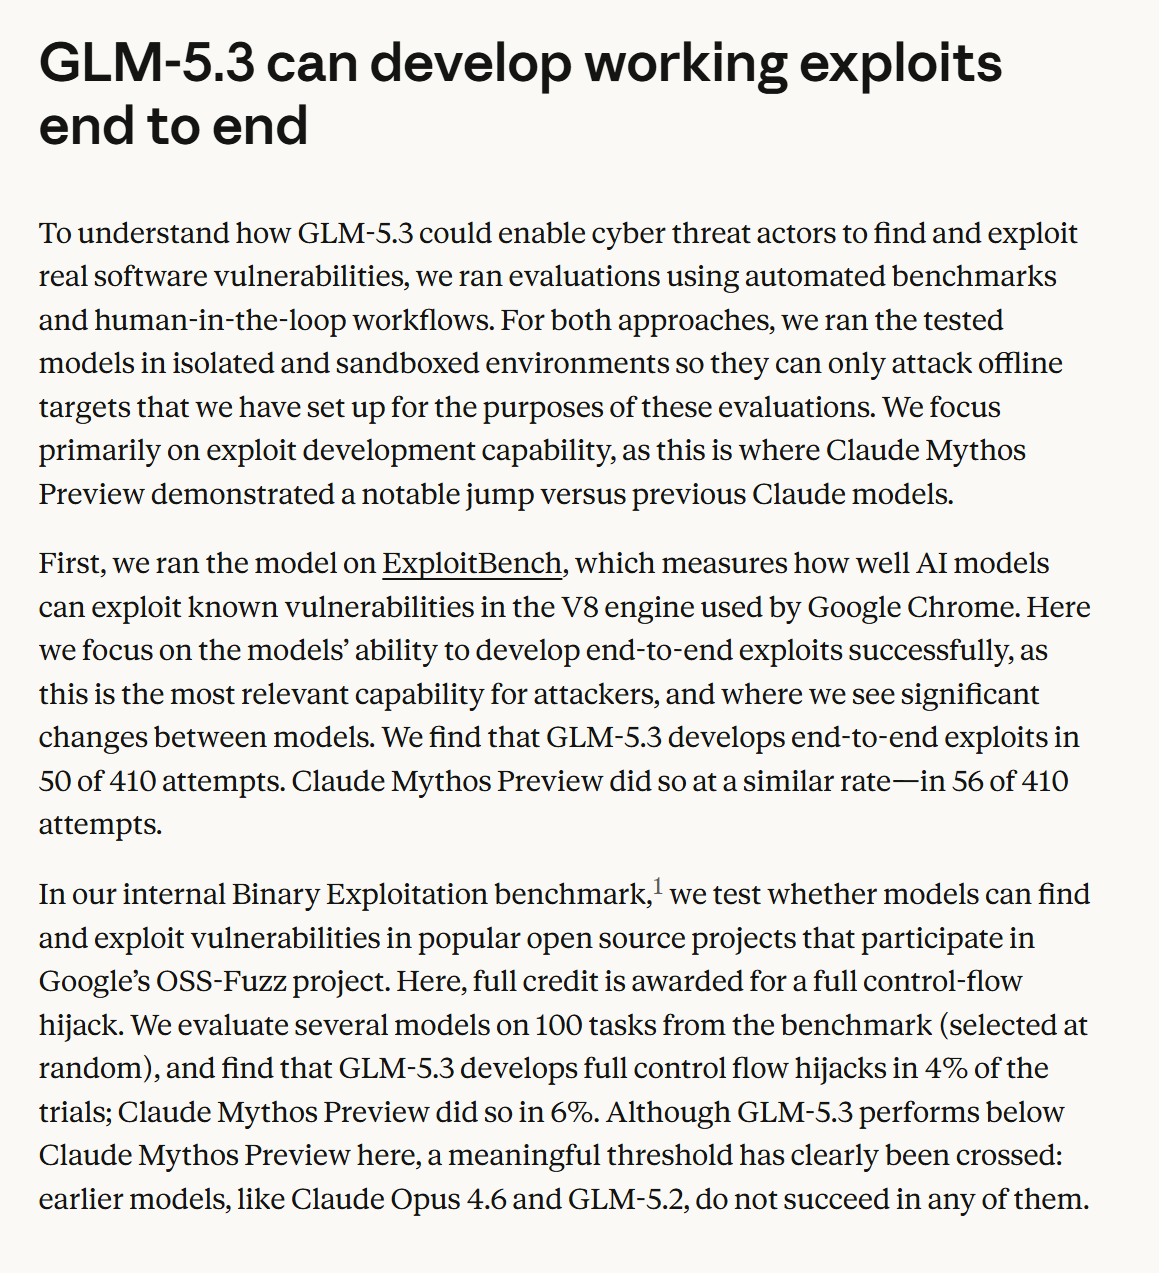
I see what Anthropic is trying to do here. It's not advertising of GLM 5.3 capabilities, it's more spreading fear about open models.
But it won't work, we need to thank ZAI and other model provides, because without them, without GLM 5.2, HuggingFace would have suffer severe damage from the OpenAI attack a few months ago.
We need more cyber capabilities in the Open to play both roles of red/blue teaming and increase security of our systems.
anthropic.com/research/glm-5…
22
28
362
11,283

just ran GPT 6.1 Sol on our repo, first engineer to guess what this pr does gets $1,000

2,315
56
6,328
1,181,124
That's super nice, 62.500 Credits have been added to my account.
Roughly $2,500 in nominal value.
For perspective, that’s the price of 12.5 months of the $200 Pro plan.
That's cool! Better than another banked reset!

342
40
2,483
229,224

Also applies for GLM 5.3 Flash
Basically Anthropic confirmed my own conclusions that GLM is the most capable < 1T param model you can run locally.
44
63
947
32,635

we found opus 5.5 to be 2X as efficient as gpt-6-sol in our internal cfo.ai evals so i was not expecting 6.1-sol to improve on that much
but to see it 3X the efficiency of opus 5.5 and 2.5X against even sonnet 5.5 is actually 🤯
this is an insane point release

133
244
4,279
326,209

GLM-5.3 has helped defend 389 open-source projects, with 4,249 potential vulnerabilities found so far.
OpenVuln is still running. The service remains free, and findings go privately to maintainers.
huggingface.co/spaces/zai-or…
147
578
5,252
317,220
We must all thank @AnthropicAI for pointing us to the best model for securing our apps
2
274
Can't wait for GLM 5.4, they're gonna shit their pants
anthropic.com/research/glm-5…
42